Category: Blog

Your blog category

  • Black Phone 2: Scott Derrickson Answers the Call of Evil

    Black Phone 2: Scott Derrickson Answers the Call of Evil

    This content appears in the newest problem of DEN OF GEEK publication. These are all of our magazine stories to read. Imagine if your worst dream merely kept repeating itself. The Grabber, Ethan Hawke’s Black Phone killer, is being made a genuine dread image by Universal Pictures and Blumhouse Productions. The veiled ]…]

    Scott Derrickson Answers the Call of Evil in Black Phone 2 second appeared on Den of Geek.

    Westeros is home to many, let’s say, less-than-humble heroes, according to George R. R. Martin. Large-than-life figures like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are certainly appealing to the fantasy world depicted in Martin&#8217, s&#8220, A Song of Ice and Fire&#8221, books, and HBO’s Game of Thrones and House of the Dragon. These individuals are more than likely aware of their enormous reputation.

    With the most recent Game of Thrones prequel line, A Knight of the Seven Kingdoms, all of that is all set to shift. This version of Martin &#8217, s &#8220, Tales of Dunk and Egg &#8221, novellas may also add the viewpoints of the Seven Kingdoms &#8217, lower class, as seen through the eye of this franchise’s most endearingly self-aware numbers.

    cnx. powershell. push ( function ( ) {cnx ( {playerId:” 106e33c0-3911-473c-b599-b1426db57530″, }). render ( “0270c398a82f44f49c23c16122516796” ), }),

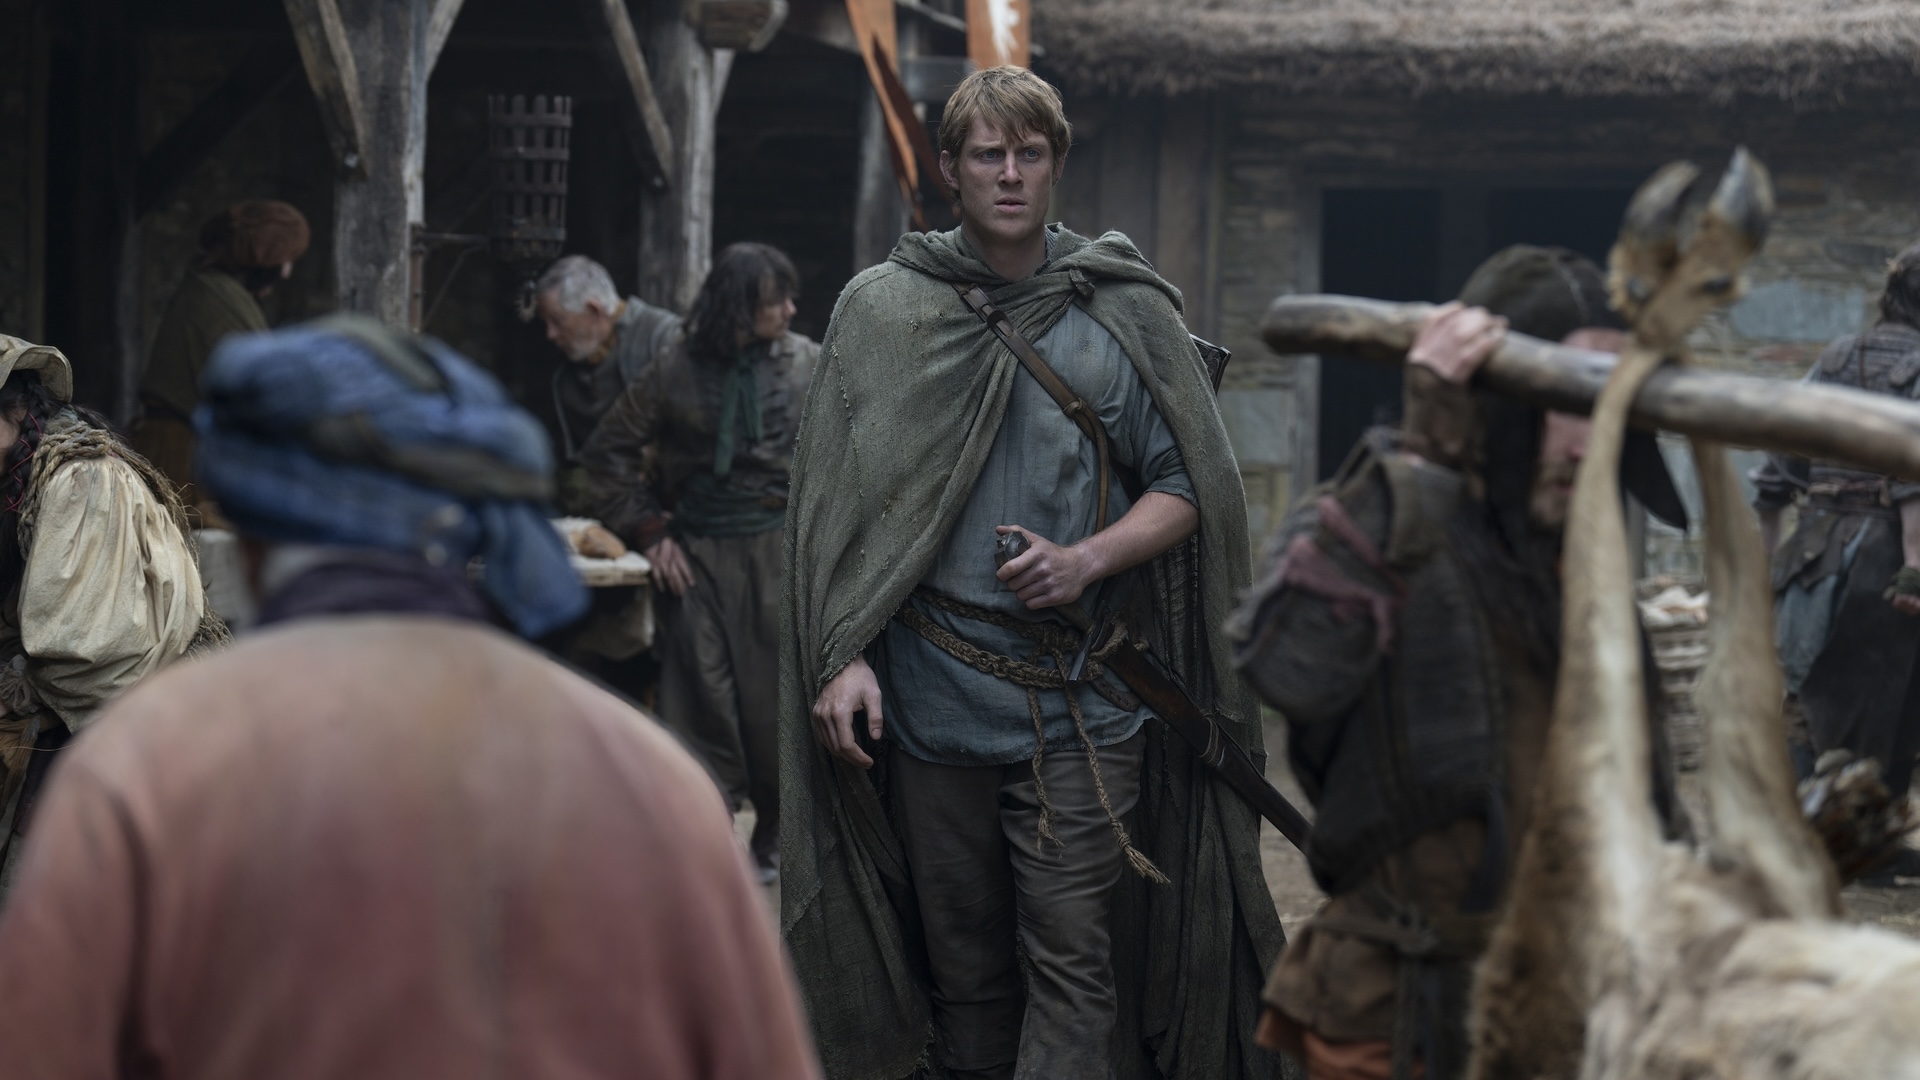
    There&#8217, s no good way to put this but&#8230, Ser Duncan the Tall a. k. a. &#8220, Dunk&#8221, ( Peter Claffey ) is a bit of an idiot and he knows it. In the Dunk and Egg tales, his domestic speech is a constant source of frustration and self-loathing. The poor man wasn’t born in a mansion and subjected to the same level of education as the noble of Westeros. He rather had to find his own path to becoming a knight like the rest of us farmers. He is therefore the most uncommon Westerosi archetype: a large, lovely dummy. The George R. R. Martin and Ira Parker-created set has Dunk&#8217’s description straight out of the box.

    Peter Claffery &#8217 ;s Dunk is depicted as the beautiful, flawless moron he is no fewer than five times in this two-minute presentation. When Lord Baelor Targaryen’s slave tries to find his horses past his enormous body, he is standing like a pile in front of him. In the future, Prince Aerion Targaryen ( Finn Bennett ) will conclude that Dunk is not intelligent enough to be a stableboy. Then Dunk is completely owned by his brand-new young squire Egg ( Dexter Sol Ansell ), as the boy correctly states that he does n’t have any dogs to hunt him down. Dunk also maintains the impression that he is intended for greater things.

    He turns toward the end of the tape,” #8221,” because I know I’m only a wall knight, but occasionally I think I could be more. The World of Ice and Fire users will be aware of Martin’s error.

    Ser Duncan is a ( literally ) big reason why Game of Thrones is at its best and A Knight of the Seven Kingdoms will serve as its warmest counterpart. Despite the moral gray of every person in Martin &#8217’s dream world, Dunk is one of its more talented soldiers, and Egg and the series that follows him appear to be following his lead. The video makes that clear with a lighter colour scheme and artist Dan Romer’s cheery score, which replaces Ramin Djawadi’s epic bombast and composer Dan Romer’s lighter color palette.

    Sir Duncan the Tall may not be the Prince Who Was Promised, but he might just be the protagonist that Westeros desperately needs in the year 209 AC. A Knight of the Seven Kingdom‘s biggest, dumbest boy has a chance to effect real change now that the dragons are long gone, House Targaryen’s power is waning, and ( first ) Blackfyre Rebellion is in view.

    On HBO Max, A Knight of the Seven Kingdoms will be airing on January 18.

    The first episode of Den of Geek was titled Dunk Is But Superbly Dumb in the Knight of the Seven Kingdoms Trailer.

  • Rian Johnson Wants Knives Out to Outlive Netflix

    Rian Johnson Wants Knives Out to Outlive Netflix

    Southern-fried policeman Benoit Blanc reportedly described his investigation into the death of author Harlan Thrombey in Knives Out as a situation with a hole in the center,” a donut.” Turns out Knives Out has a potential company with a hole in the center, at least in terms of distribution. Rian, the father, explains that.

    Rian Johnson wanted to watch Netflix, but it never made it to Netflix.

    Westeros is home to many, let’s say, less-than-humble heroes, according to George R. R. Martin. Large-than-life figures like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are certainly appealing to the fantasy world depicted in Martin&#8217, s&#8220, A Song of Ice and Fire&#8221, books, and the HBO set Game of Thrones and House of the Dragon. These individuals are more than likely aware of their enormous position.

    With the most recent Game of Thrones prequel line, A Knight of the Seven Kingdoms, all of that is all set to shift. This version of Martin &#8217, s &#8220, Tales of Dunk and Egg &#8221, novellas may also add the viewpoints of the Seven Kingdoms &#8217, lower class, as seen through the eye of this franchise &#8217, one of the most endearingly self-aware characters.

    cnx. powershell. push ( function ( ) {cnx ( {playerId:” 106e33c0-3911-473c-b599-b1426db57530″, }). render ( “0270c398a82f44f49c23c16122516796” ), }),

    There&#8217, s no wonderful way to put this but&#8230, Ser Duncan the Tall a. k. a. &#8220, Dunk&#8221, ( Peter Claffey ) is a bit of an idiot and he knows it. In the Dunk and Egg tales, his domestic speech is a constant source of frustration and self-loathing. The poor man wasn’t born in a mansion and subjected to the same level of education as the noble of Westeros. He rather had to find his own path to becoming a knight like the rest of us farmers. He is therefore the most uncommon of the Westerosi themes: a huge lovely dummy. The George R. R. Martin and Ira Parker-created set has Dunk&#8217’s description down pat, based on the second video for A Knight of the Seven Kingdoms.

    Peter Claffery &#8217 ;s Dunk is depicted as the beautiful, flawless moron he is no fewer than five times in this two-minute presentation. When Lord Baelor Targaryen’s slave tries to ride his horses past his enormous body, he is standing like a pile in front of him. Later, Prince Aerion Targaryen ( Finn Bennett ) will conclude that Dunk lacks the intelligence to be a stableboy. Then Dunk is completely owned by his brand-new young squire Egg ( Dexter Sol Ansell ), as the boy correctly states that he does n’t have any dogs to hunt him down. Dunk also maintains the impression that he is intended for greater things.

    He intones about halfway through the clip,” I know I’m really a hedge knight, but I sometimes think I could be more,” he intones. The World of Ice and Fire users will be aware of how accurate he is.

    Ser Duncan is a ( literally ) major reason why Game of Thrones is at its best when a Knight of the Seven Kingdoms is cast as its warmest member. While every person in Martin &#8217’s dream world is morally unworthy, Dunk is one of its more talented soldiers, and Egg looks to get following his lead. With a lighter color scheme and musician Dan Romer’s jaunty score replacing Ramin Djawadi’s spectacular bombast, the trailer makes that obvious.

    Sir Duncan the Tall may not be the Prince Who Was Promised, but he might just be the protagonist that Westeros desperately needs in the year 209 AD. A Knight of the Seven Kingdom‘s biggest, dumbest boy has a chance to effect real change now that the dragons are long gone, House Targaryen’s power is waning, and ( first ) Blackfyre Rebellion is in view.

    A Knight of the Seven Kingdoms airs on HBO Max on January 18th.

    The Knight of the Seven Kingdoms video originally appeared on Den of Geek, and the title follows.

  • Remembering DC’s Strange First Attempt at Vigilante in the Arrowverse

    Remembering DC’s Strange First Attempt at Vigilante in the Arrowverse

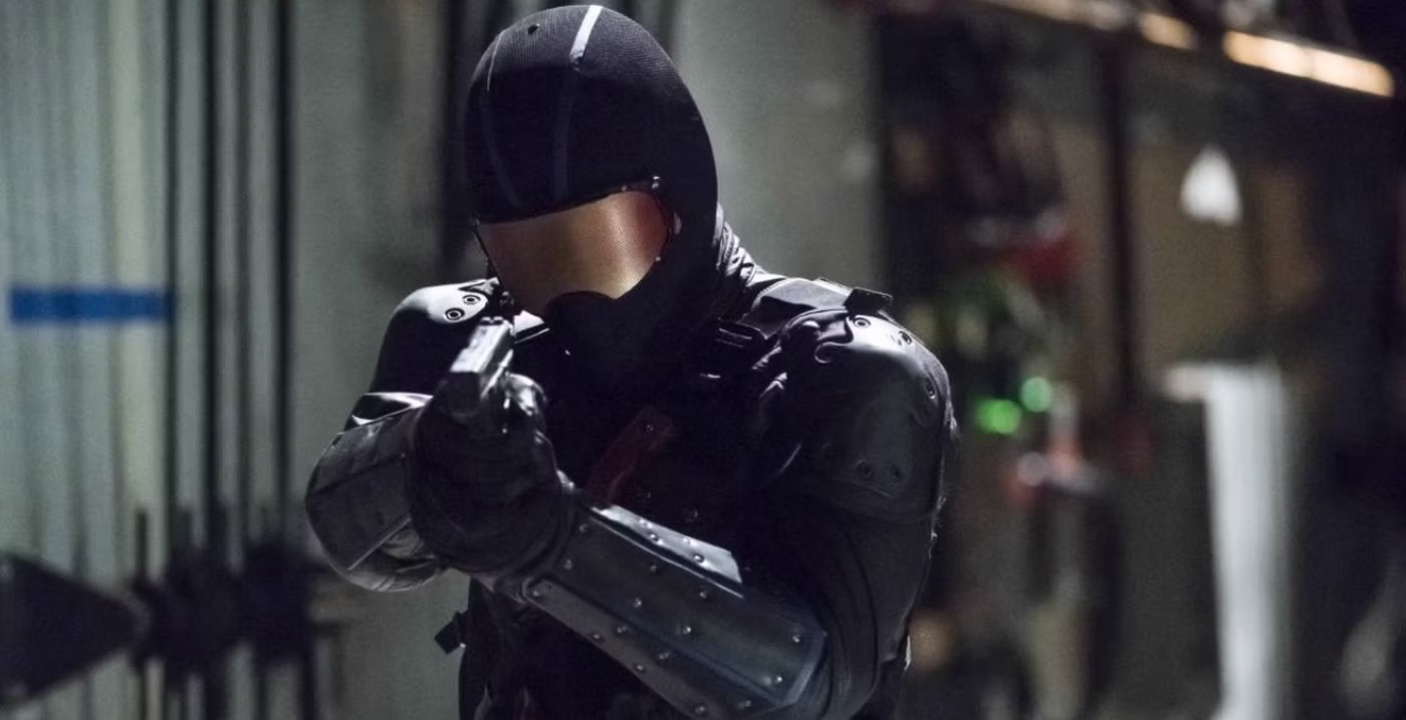
    Peacemaker is a true ensemble show about a group of misfits who form a friendship under the name The 11th Street Kids, despite Chris Smith being the only character in the line ‘ name. And Adrian Chase, an utter psycho who also happens to be a]… [ And one of the 11th Street Kids is the superstar.

    Den of Geek‘s first post remembered DC’s unusual first effort at Vigilante in the Arrowverse.

    Westeros is home to many, let’s say, less-than-humble heroes, according to George R. R. Martin. Large-than-life figures like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are certainly appealing to the fantasy world depicted in Martin&#8217, s&#8220, A Song of Ice and Fire&#8221, books, and the HBO set Game of Thrones and House of the Dragon. These individuals are more than likely aware of their enormous reputation.

    With the most recent Game of Thrones prequel line, A Knight of the Seven Kingdoms, all of that is all set to shift. This version of Martin &#8217, s &#8220, Tales of Dunk and Egg &#8221, novella will also be viewed through the eye of this franchise’s most endearingly self-aware characters.

    cnx. command. push ( function ( ) {cnx ( {playerId:” 106e33c0-3911-473c-b599-b1426db57530″, }). render ( “0270c398a82f44f49c23c16122516796” ), }),

    There&#8217, s no great way to put this but&#8230, Ser Duncan the Tall a. k. a. &#8220, Dunk&#8221, ( Peter Claffey ) is a bit of an idiot and he knows it. His interior speech in the Dunk and Egg tales is a constant stream of frustration and self-loathing. The poor man wasn’t born in a mansion and subjected to the same level of education as the noble of Westeros. He rather had to consider his own path, just like the rest of us farmers. He is therefore the most uncommon of the Westerosi themes: a large, charming dummy. The George R. R. Martin and Ira Parker-created line has Dunk&#8217’s description down pat, based on the second video for A Knight of the Seven Kingdoms.

    Peter Claffery &#8217 ;s Dunk is depicted as the beautiful, flawless moron he is no fewer than five times in this two-minute presentation. When Lord Baelor Targaryen’s slave tries to find his horses past his enormous body, he is standing like a pile in front of him. Later, Prince Aerion Targaryen ( Finn Bennett ) will conclude that Dunk is not intelligent enough to be a stableboy. Then Dunk is completely owned by his brand-new young squire Egg ( Dexter Sol Ansell ), as the boy correctly states that he does n’t have any dogs to hunt him down. Dunk also maintains the impression that he is intended for greater items.

    He intones about halfway through the picture,” I know I’m really a hedge knight, but I sometimes think I could be more,” he intones. The World of Ice and Fire users will be aware of how accurate he is.

    Sir Duncan will play a significant role in Game of Thrones ‘ most heartfelt role, and a Knight of the Seven Kingdoms will do so. While every person in Martin &#8217’s dream world is morally unworthy, Dunk is one of its more talented soldiers, and Egg looks to get following his lead. The video makes that clear with a lighter colour scheme and composer Dan Romer’s cheery score, which replaces Ramin Djawadi’s epic bombast and composer Dan Romer’s lighter color palette.

    Sir Duncan the Tall may not be the Prince Who Was Promised, but he might just be the protagonist that Westeros desperately needs in the year 209 AD. A Knight of the Seven Kingdom&#8216, the biggest, dumbest boy, has a chance to effect real change now that the dragons are long gone, House Targaryen’s power is waning, and the ( first ) Blackfyre Rebellion is in the back.

    On HBO Max, A Knight of the Seven Kingdoms will be airing on January 18.

    The first episode of Den of Geek was titled Dunk Is But Wonderfully Dumb in the Knight of the Seven Kingdoms Trailer.

  • Dunk Is So Beautifully Dumb in the Knight of the Seven Kingdoms Trailer

    Dunk Is So Beautifully Dumb in the Knight of the Seven Kingdoms Trailer

    Westeros by George R. R. Martin is full of numerous, let’s say, less-than-humble personalities. Large-than-life figures like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are certainly appealing to the fantasy world featured in Martin’s” A Song of Ice and Fire” novels and the HBO series Game of Thrones and House of the Dragon. more frequently than]…]

    The Knight of the Seven Kingdoms video for Dunk Is But Wonderfully Dumb first appeared on Den of Geek.

    Westeros is home to many, let’s say, less-than-humble heroes, according to George R. R. Martin. Large-than-life characters like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are not wanted in the fantasy world depicted in Martin&#8217, s &#8220, A Song of Ice and Fire&#8221, novels and the HBO series Game of Thrones and House of the Dragon. These individuals are more than likely aware of their enormous reputation.

    With the most recent Game of Thrones prequel line, A Knight of the Seven Kingdoms, all of that is all set to shift. This version of Martin &#8217, s &#8220, Tales of Dunk and Egg &#8221, novellas may also add the viewpoints of the Seven Kingdoms &#8217, lower class, as seen through the eye of this franchise’s most endearingly self-aware numbers.

    cnx. command. push ( function ( ) {cnx ( {playerId:” 106e33c0-3911-473c-b599-b1426db57530″, }). render ( “0270c398a82f44f49c23c16122516796” ), }),

    There&#8217, s no good way to put this but&#8230, Ser Duncan the Tall a. k. a. &#8220, Dunk&#8221, ( Peter Claffey ) is a bit of an idiot and he knows it. In the Dunk and Egg tales, his domestic speech is a constant source of frustration and self-loathing. The poor man wasn’t born in a tower and subjected to the same level of education as the noble of Westeros. He rather had to find his own path to becoming a knight like the rest of us farmers. He is therefore the most uncommon of the Westerosi themes: a huge, lovely dummy. The George R. R. Martin and Ira Parker-created set has Dunk&#8217’s description straight out of the box.

    In this two-minute presentation, Peter Claffery &#8217 ;s Dunk is portrayed as the beautiful, flawless moron he is no fewer than five times. When Lord Baelor Targaryen’s maid tries to ride his horses past his enormous body, he is standing like a pile in front of him. Later, Prince Aerion Targaryen ( Finn Bennett ) will conclude that Dunk lacks the intelligence to be a stableboy. The boy correctly states that he doesn’t have any dogs and isn’t hunting him down, but Dunk is completely owned by his new young squire Egg ( Dexter Sol Ansell ). Dunk also maintains the impression that he is intended for greater items.

    He intones about halfway through the tape,” I know I’m really a hedge knight, but I sometimes think I could be more,” he intones. The World of Ice and Fire users will be aware of Martin’s error.

    Ser Duncan is a ( literally ) major reason why Game of Thrones is at its best when a Knight of the Seven Kingdoms is cast as its warmest member. Despite the moral gray of every person in Martin &#8217’s dream world, Dunk is one of its more talented soldiers, and Egg and the series that follows him appear to be following his lead. With a lighter color scheme and musician Dan Romer’s jaunty score replacing Ramin Djawadi’s spectacular bombast, the trailer makes that obvious.

    Sir Duncan the Tall may not be the Prince Who Was Promised, but he might just be the protagonist that Westeros desperately needs in the year 209 AC. A Knight of the Seven Kingdom‘s biggest, dumbest boy has a chance to effect real change now that the dragons are long gone, House Targaryen’s power is waning, and the ( first ) Blackfyre Rebellion is in view.

    A Knight of the Seven Kingdoms airs on HBO Max on January 18th.

    The Knight of the Seven Kingdoms video for Dunk Is But Wonderfully Dumb first appeared on Den of Geek.

  • Star Trek: Strange New Worlds Needs to Spotlight its Most Underrated Character

    Star Trek: Strange New Worlds Needs to Spotlight its Most Underrated Character

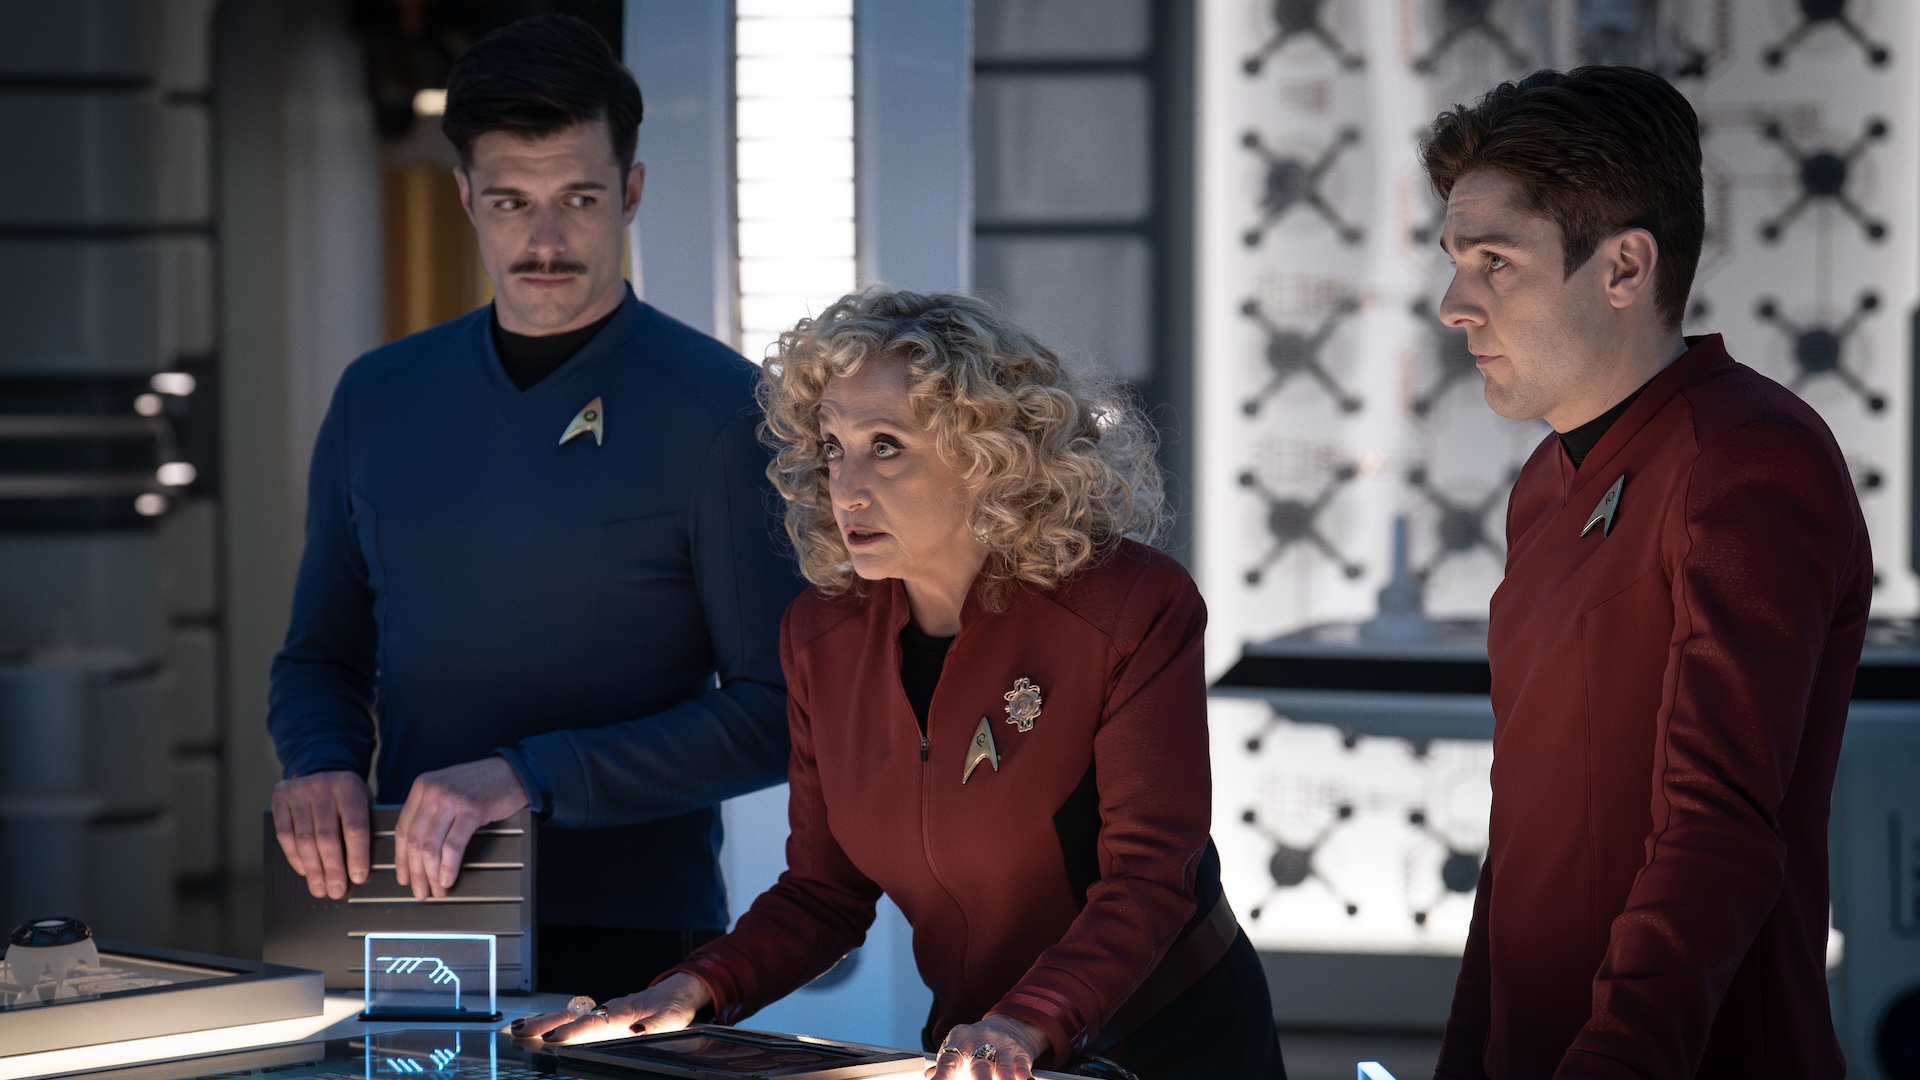
    Over the course of its work, Star Trek: Odd New Worlds has introduced a number of new characters, including both established company members and well-known eyes. We’ve met a number of younger players who may eventually play significant roles in Star Trek: The Original Series, some of whom are distinctive.

    The second post Star Trek: Unusual New Worlds Wants to Light its Most Underappreciated Character appeared on Den of Geek.

    Westeros is home to many, let’s say, less-than-humble personalities, according to George R. R. Martin. Large-than-life figures like Cersei Lannister, Stannis Baratheon, and Daemon Targaryen are certainly appealing to the fantasy world depicted in Martin&#8217, s&#8220, A Song of Ice and Fire&#8221, books, and the HBO series Game of Thrones and House of the Dragon. These individuals are more than likely aware of their enormous reputation.

    With the most recent Game of Thrones prequel line, A Knight of the Seven Kingdoms, all of that is all set to alter. This version of Martin &#8217, s &#8220, Tales of Dunk and Egg &#8221, novella will also be viewed through the eye of this franchise’s most endearingly self-aware characters.

    cnx. powershell. push ( function ( ) {cnx ( {playerId:” 106e33c0-3911-473c-b599-b1426db57530″, }). render ( “0270c398a82f44f49c23c16122516796” ), }),

    There&#8217, s no great way to put this but&#8230, Ser Duncan the Tall a. k. a. &#8220, Dunk&#8221, ( Peter Claffey ) is a bit of an idiot and he knows it. His inner monologue in the Dunk and Egg tales is a constant stream of frustration and self-loathing. The poor man wasn’t born in a tower and subjected to the same level of education as the noble of Westeros. He rather had to consider his own path, just like the rest of us farmers. He is therefore the most uncommon Westerosi archetype: a large, lovely dummy. The George R. R. Martin and Ira Parker-created line has Dunk&#8217’s description down pat, based on the second video for A Knight of the Seven Kingdoms.

    Peter Claffery &#8217 ;s Dunk is depicted as the beautiful, flawless moron he is no fewer than five times in this two-minute presentation. When Lord Baelor Targaryen’s slave tries to find his horses past his enormous body, he is standing like a pile in front of him. In the future, Prince Aerion Targaryen ( Finn Bennett ) will conclude that Dunk is not intelligent enough to be a stableboy. Then Dunk is completely owned by his brand-new young squire Egg ( Dexter Sol Ansell ), as the boy correctly states that he does n’t have any dogs to hunt him down. Dunk also maintains the impression that he is intended for greater items.

    He intones about halfway through the video,” I know I’m really a hedge knight, but I sometimes think I could be more,” he intones. The World of Ice and Fire users will be aware of Martin’s error.

    Ser Duncan is a ( literally ) big reason why Game of Thrones is at its best and A Knight of the Seven Kingdoms will serve as its warmest counterpart. While every person in Martin &#8217’s dream world is morally unworthy, Dunk is one of its more talented soldiers, and Egg looks to get following his lead. With a lighter color scheme and musician Dan Romer’s jaunty score replacing Ramin Djawadi’s spectacular bombast, the trailer makes that obvious.

    Sir Duncan the Tall may not be the Prince Who Was Promised, but he might just be the protagonist that Westeros desperately needs in the year 209 AC. A Knight of the Seven Kingdom‘s biggest, dumbest boy has a chance to effect real change now that the dragons are long gone, House Targaryen’s power is waning, and ( first ) Blackfyre Rebellion is in view.

    On HBO Max, A Knight of the Seven Kingdoms will be airing on January 18.

    The Knight of the Seven Kingdoms video for Dunk Is But Wonderfully Dumb first appeared on Den of Geek.

  • Asynchronous Design Critique: Getting Feedback

    Asynchronous Design Critique: Getting Feedback

    “Any comment?” is probably one of the worst ways to ask for feedback. It’s vague and open ended, and it doesn’t provide any indication of what we’re looking for. Getting good feedback starts earlier than we might expect: it starts with the request. 

    It might seem counterintuitive to start the process of receiving feedback with a question, but that makes sense if we realize that getting feedback can be thought of as a form of design research. In the same way that we wouldn’t do any research without the right questions to get the insights that we need, the best way to ask for feedback is also to craft sharp questions.

    Design critique is not a one-shot process. Sure, any good feedback workflow continues until the project is finished, but this is particularly true for design because design work continues iteration after iteration, from a high level to the finest details. Each level needs its own set of questions.

    And finally, as with any good research, we need to review what we got back, get to the core of its insights, and take action. Question, iteration, and review. Let’s look at each of those.

    The question

    Being open to feedback is essential, but we need to be precise about what we’re looking for. Just saying “Any comment?”, “What do you think?”, or “I’d love to get your opinion” at the end of a presentation—whether it’s in person, over video, or through a written post—is likely to get a number of varied opinions or, even worse, get everyone to follow the direction of the first person who speaks up. And then… we get frustrated because vague questions like those can turn a high-level flows review into people instead commenting on the borders of buttons. Which might be a hearty topic, so it might be hard at that point to redirect the team to the subject that you had wanted to focus on.

    But how do we get into this situation? It’s a mix of factors. One is that we don’t usually consider asking as a part of the feedback process. Another is how natural it is to just leave the question implied, expecting the others to be on the same page. Another is that in nonprofessional discussions, there’s often no need to be that precise. In short, we tend to underestimate the importance of the questions, so we don’t work on improving them.

    The act of asking good questions guides and focuses the critique. It’s also a form of consent: it makes it clear that you’re open to comments and what kind of comments you’d like to get. It puts people in the right mental state, especially in situations when they weren’t expecting to give feedback.

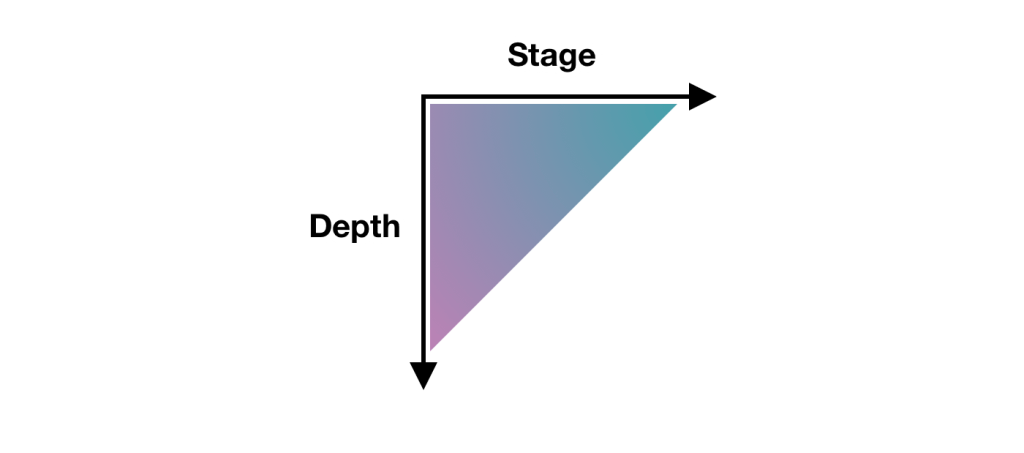
    There isn’t a single best way to ask for feedback. It just needs to be specific, and specificity can take many shapes. A model for design critique that I’ve found particularly useful in my coaching is the one of stage versus depth.

    “Stage” refers to each of the steps of the process—in our case, the design process. In progressing from user research to the final design, the kind of feedback evolves. But within a single step, one might still review whether some assumptions are correct and whether there’s been a proper translation of the amassed feedback into updated designs as the project has evolved. A starting point for potential questions could derive from the layers of user experience. What do you want to know: Project objectives? User needs? Functionality? Content? Interaction design? Information architecture? UI design? Navigation design? Visual design? Branding?

    Here’re a few example questions that are precise and to the point that refer to different layers:

    • Functionality: Is automating account creation desirable?
    • Interaction design: Take a look through the updated flow and let me know whether you see any steps or error states that I might’ve missed.
    • Information architecture: We have two competing bits of information on this page. Is the structure effective in communicating them both?
    • UI design: What are your thoughts on the error counter at the top of the page that makes sure that you see the next error, even if the error is out of the viewport? 
    • Navigation design: From research, we identified these second-level navigation items, but once you’re on the page, the list feels too long and hard to navigate. Are there any suggestions to address this?
    • Visual design: Are the sticky notifications in the bottom-right corner visible enough?

    The other axis of specificity is about how deep you’d like to go on what’s being presented. For example, we might have introduced a new end-to-end flow, but there was a specific view that you found particularly challenging and you’d like a detailed review of that. This can be especially useful from one iteration to the next where it’s important to highlight the parts that have changed.

    There are other things that we can consider when we want to achieve more specific—and more effective—questions.

    A simple trick is to remove generic qualifiers from your questions like “good,” “well,” “nice,” “bad,” “okay,” and “cool.” For example, asking, “When the block opens and the buttons appear, is this interaction good?” might look specific, but you can spot the “good” qualifier, and convert it to an even better question: “When the block opens and the buttons appear, is it clear what the next action is?”

    Sometimes we actually do want broad feedback. That’s rare, but it can happen. In that sense, you might still make it explicit that you’re looking for a wide range of opinions, whether at a high level or with details. Or maybe just say, “At first glance, what do you think?” so that it’s clear that what you’re asking is open ended but focused on someone’s impression after their first five seconds of looking at it.

    Sometimes the project is particularly expansive, and some areas may have already been explored in detail. In these situations, it might be useful to explicitly say that some parts are already locked in and aren’t open to feedback. It’s not something that I’d recommend in general, but I’ve found it useful to avoid falling again into rabbit holes of the sort that might lead to further refinement but aren’t what’s most important right now.

    Asking specific questions can completely change the quality of the feedback that you receive. People with less refined critique skills will now be able to offer more actionable feedback, and even expert designers will welcome the clarity and efficiency that comes from focusing only on what’s needed. It can save a lot of time and frustration.

    The iteration

    Design iterations are probably the most visible part of the design work, and they provide a natural checkpoint for feedback. Yet a lot of design tools with inline commenting tend to show changes as a single fluid stream in the same file, and those types of design tools make conversations disappear once they’re resolved, update shared UI components automatically, and compel designs to always show the latest version—unless these would-be helpful features were to be manually turned off. The implied goal that these design tools seem to have is to arrive at just one final copy with all discussions closed, probably because they inherited patterns from how written documents are collaboratively edited. That’s probably not the best way to approach design critiques, but even if I don’t want to be too prescriptive here: that could work for some teams.

    The asynchronous design-critique approach that I find most effective is to create explicit checkpoints for discussion. I’m going to use the term iteration post for this. It refers to a write-up or presentation of the design iteration followed by a discussion thread of some kind. Any platform that can accommodate this structure can use this. By the way, when I refer to a “write-up or presentation,” I’m including video recordings or other media too: as long as it’s asynchronous, it works.

    Using iteration posts has many advantages:

    • It creates a rhythm in the design work so that the designer can review feedback from each iteration and prepare for the next.
    • It makes decisions visible for future review, and conversations are likewise always available.
    • It creates a record of how the design changed over time.
    • Depending on the tool, it might also make it easier to collect feedback and act on it.

    These posts of course don’t mean that no other feedback approach should be used, just that iteration posts could be the primary rhythm for a remote design team to use. And other feedback approaches (such as live critique, pair designing, or inline comments) can build from there.

    I don’t think there’s a standard format for iteration posts. But there are a few high-level elements that make sense to include as a baseline:

    1. The goal
    2. The design
    3. The list of changes
    4. The questions

    Each project is likely to have a goal, and hopefully it’s something that’s already been summarized in a single sentence somewhere else, such as the client brief, the product manager’s outline, or the project owner’s request. So this is something that I’d repeat in every iteration post—literally copy and pasting it. The idea is to provide context and to repeat what’s essential to make each iteration post complete so that there’s no need to find information spread across multiple posts. If I want to know about the latest design, the latest iteration post will have all that I need.

    This copy-and-paste part introduces another relevant concept: alignment comes from repetition. So having posts that repeat information is actually very effective toward making sure that everyone is on the same page.

    The design is then the actual series of information-architecture outlines, diagrams, flows, maps, wireframes, screens, visuals, and any other kind of design work that’s been done. In short, it’s any design artifact. For the final stages of work, I prefer the term blueprint to emphasize that I’ll be showing full flows instead of individual screens to make it easier to understand the bigger picture. 

    It can also be useful to label the artifacts with clear titles because that can make it easier to refer to them. Write the post in a way that helps people understand the work. It’s not too different from organizing a good live presentation. 

    For an efficient discussion, you should also include a bullet list of the changes from the previous iteration to let people focus on what’s new, which can be especially useful for larger pieces of work where keeping track, iteration after iteration, could become a challenge.

    And finally, as noted earlier, it’s essential that you include a list of the questions to drive the design critique in the direction you want. Doing this as a numbered list can also help make it easier to refer to each question by its number.

    Not all iterations are the same. Earlier iterations don’t need to be as tightly focused—they can be more exploratory and experimental, maybe even breaking some of the design-language guidelines to see what’s possible. Then later, the iterations start settling on a solution and refining it until the design process reaches its end and the feature ships.

    I want to highlight that even if these iteration posts are written and conceived as checkpoints, by no means do they need to be exhaustive. A post might be a draft—just a concept to get a conversation going—or it could be a cumulative list of each feature that was added over the course of each iteration until the full picture is done.

    Over time, I also started using specific labels for incremental iterations: i1, i2, i3, and so on. This might look like a minor labelling tip, but it can help in multiple ways:

    • Unique—It’s a clear unique marker. Within each project, one can easily say, “This was discussed in i4,” and everyone knows where they can go to review things.
    • Unassuming—It works like versions (such as v1, v2, and v3) but in contrast, versions create the impression of something that’s big, exhaustive, and complete. Iterations must be able to be exploratory, incomplete, partial.
    • Future proof—It resolves the “final” naming problem that you can run into with versions. No more files named “final final complete no-really-its-done.” Within each project, the largest number always represents the latest iteration.

    To mark when a design is complete enough to be worked on, even if there might be some bits still in need of attention and in turn more iterations needed, the wording release candidate (RC) could be used to describe it: “with i8, we reached RC” or “i12 is an RC.”

    The review

    What usually happens during a design critique is an open discussion, with a back and forth between people that can be very productive. This approach is particularly effective during live, synchronous feedback. But when we work asynchronously, it’s more effective to use a different approach: we can shift to a user-research mindset. Written feedback from teammates, stakeholders, or others can be treated as if it were the result of user interviews and surveys, and we can analyze it accordingly.

    This shift has some major benefits that make asynchronous feedback particularly effective, especially around these friction points:

    1. It removes the pressure to reply to everyone.
    2. It reduces the frustration from swoop-by comments.
    3. It lessens our personal stake.

    The first friction point is feeling a pressure to reply to every single comment. Sometimes we write the iteration post, and we get replies from our team. It’s just a few of them, it’s easy, and it doesn’t feel like a problem. But other times, some solutions might require more in-depth discussions, and the amount of replies can quickly increase, which can create a tension between trying to be a good team player by replying to everyone and doing the next design iteration. This might be especially true if the person who’s replying is a stakeholder or someone directly involved in the project who we feel that we need to listen to. We need to accept that this pressure is absolutely normal, and it’s human nature to try to accommodate people who we care about. Sometimes replying to all comments can be effective, but if we treat a design critique more like user research, we realize that we don’t have to reply to every comment, and in asynchronous spaces, there are alternatives:

    • One is to let the next iteration speak for itself. When the design evolves and we post a follow-up iteration, that’s the reply. You might tag all the people who were involved in the previous discussion, but even that’s a choice, not a requirement. 
    • Another is to briefly reply to acknowledge each comment, such as “Understood. Thank you,” “Good points—I’ll review,” or “Thanks. I’ll include these in the next iteration.” In some cases, this could also be just a single top-level comment along the lines of “Thanks for all the feedback everyone—the next iteration is coming soon!”
    • Another is to provide a quick summary of the comments before moving on. Depending on your workflow, this can be particularly useful as it can provide a simplified checklist that you can then use for the next iteration.

    The second friction point is the swoop-by comment, which is the kind of feedback that comes from someone outside the project or team who might not be aware of the context, restrictions, decisions, or requirements—or of the previous iterations’ discussions. On their side, there’s something that one can hope that they might learn: they could start to acknowledge that they’re doing this and they could be more conscious in outlining where they’re coming from. Swoop-by comments often trigger the simple thought “We’ve already discussed this…”, and it can be frustrating to have to repeat the same reply over and over.

    Let’s begin by acknowledging again that there’s no need to reply to every comment. If, however, replying to a previously litigated point might be useful, a short reply with a link to the previous discussion for extra details is usually enough. Remember, alignment comes from repetition, so it’s okay to repeat things sometimes!

    Swoop-by commenting can still be useful for two reasons: they might point out something that still isn’t clear, and they also have the potential to stand in for the point of view of a user who’s seeing the design for the first time. Sure, you’ll still be frustrated, but that might at least help in dealing with it.

    The third friction point is the personal stake we could have with the design, which could make us feel defensive if the review were to feel more like a discussion. Treating feedback as user research helps us create a healthy distance between the people giving us feedback and our ego (because yes, even if we don’t want to admit it, it’s there). And ultimately, treating everything in aggregated form allows us to better prioritize our work.

    Always remember that while you need to listen to stakeholders, project owners, and specific advice, you don’t have to accept every piece of feedback. You have to analyze it and make a decision that you can justify, but sometimes “no” is the right answer. 

    As the designer leading the project, you’re in charge of that decision. Ultimately, everyone has their specialty, and as the designer, you’re the one who has the most knowledge and the most context to make the right decision. And by listening to the feedback that you’ve received, you’re making sure that it’s also the best and most balanced decision.

    Thanks to Brie Anne Demkiw and Mike Shelton for reviewing the first draft of this article.

  • Voice Content and Usability

    Voice Content and Usability

    We’ve been conversing for a long time. Whether to present information, perform transactions, or just to check in on one another, people have yammered aside, chattering and gesticulating, through spoken discussion for many generations. Only recently have we begun to write our discussions, and only recently have we outsourced them to the system, a system that exhibits a significantly higher affection for written letter than for the vernacular rigors of spoken language.

    Laptops have trouble because between spoken and written speech, talk is more primitive. Machines must wrestle with the complexity of human statement, including the disfluencies and pauses, the gestures and body speech, and the variations in term choice and spoken dialect, which may impede even the most skillfully crafted human-computer interaction. In the human-to-human scenario, spoken language also has the privilege of face-to-face contact, where we can readily interpret nonverbal social cues.

    In contrast, written language develops its own fossil record of dated terms and phrases as we record it and keep usages long after they are no longer needed in spoken communication ( for example, the salutation” To whom it may concern” ). Because it tends to be more consistent, polished, and formal, written text is fundamentally much easier for machines to parse and understand.

    This luxury is not available in spoken language. Besides the nonverbal cues that decorate conversations with emphasis and emotional context, there are also verbal cues and vocal behaviors that modulate conversation in nuanced ways: how something is said, not what. Our spoken language conveys much more than the written word could ever contain, whether it be rapid-fire, low-pitched, or high-decibel, sarcastic, stilted, or sighing. So when it comes to voice interfaces—the machines we conduct spoken conversations with—we face exciting challenges as designers and content strategists.

    Voice Compositions

    We interact with voice interfaces for a variety of reasons, but according to Michael McTear, Zoraida Callejas, and David Griol in The Conversational Interface, those motivations by and large mirror the reasons we initiate conversations with other people, too ( ). We typically strike up a discussion in the following ways:

    • we need something done ( such as a transaction ),
    • we seek knowledge of something ( some kind of information ), or
    • we are social beings and want someone to talk to ( conversation for conversation’s sake ).

    These three categories, which I refer to as transactional, informational, and prosocial, also apply to essentially every voice interaction: a single conversation that starts with the voice interface’s first greeting and ends with the user leaving the interface. Note here that a conversation in our human sense—a chat between people that leads to some result and lasts an arbitrary length of time—could encompass multiple transactional, informational, and prosocial voice interactions in succession. In other words, a voice interaction is a conversation, but it is not always just one voice interaction.

    Purely prosocial conversations are more gimmicky than captivating in most voice interfaces, because machines don’t yet have the capacity to really want to know how we’re doing and to do the sort of glad-handing humans crave. Additionally, there is ongoing debate about whether users actually prefer the type of organic human conversation that starts with a prosocial voice and progresses seamlessly into new ones. In fact, in Voice User Interface Design, Michael Cohen, James Giangola, and Jennifer Balogh recommend sticking to users ‘ expectations by mimicking how they interact with other voice interfaces rather than trying too hard to be human—potentially alienating them in the process ( ).

    A voice interface can also have two types of conversations we can have with one another that are both transactional and informational, each learning something new ( “discuss a musical” ).

    Transactional voice interactions

    When you order a Hawaiian pizza with extra pineapple, you’re typically having a conversation and a voice interaction when you’re tapping buttons on a food delivery app. Even when we walk up to the counter and place an order, the conversation quickly pivots from an initial smattering of neighborly small talk to the real mission at hand: ordering a pizza ( generously topped with pineapple, as it should be ).

    Alison: Hey, how are things going?

    Burhan: Hi, welcome to Crust Deluxe! It’s chilly outside. How can I help you?

    Can I get a Hawaiian pizza with extra pineapple, Alison?

    Burhan: Sure, what size?

    Alison: Big.

    Burhan: Anything else?

    Alison: No thanks, that’s it.

    Burhan: Something to drink?

    Alison: I’ll have a bottle of Coke.

    Burhan: You got it. That will cost$ 13.55 and take about fifteen minutes.

    Each progressive disclosure in this transactional conversation reveals more and more of the desired outcome of the transaction: a service rendered or a product delivered. Conversations that are transactional have certain characteristics: they are direct, precise, and cost-effective. They quickly dispense with pleasantries.

    Informational voice interactions

    Meanwhile, some conversations are primarily about obtaining information. Alison might visit Crust Deluxe with the sole intention of placing an order, but she might not want to leave with a pizza at all. She might be just as interested in whether they serve halal or kosher dishes, gluten-free options, or something else. Even though we have a prosocial mini-conversation once more at the beginning to practice politeness, we are after much more.

    Alison: Hey, how are things going?

    Burhan: Hi, welcome to Crust Deluxe! It’s chilly outside. How can I help you?

    Alison: Can I ask a few questions?

    Burhan: Of course! Go right ahead.

    Alison, do you have any menu items that are halal?

    Burhan: Absolutely! On request, we can make any pie halal. We also have lots of vegetarian, ovo-lacto, and vegan options. Do you have any other dietary restrictions in mind?

    Alison: What about gluten-free pizzas?

    Burhan: For both our deep-dish and thin-crust pizzas, we can definitely make a gluten-free crust for you, without a problem. Anything else I can answer for you?

    Alison: That’s it for now. Good to know. Thank you!

    Burhan: Anytime, come back soon!

    This dialogue is entirely different. Here, the goal is to get a certain set of facts. Informational conversations are research expeditions that seek the truth through information gathering. Voice interactions that are informational might be more long-winded than transactional conversations by necessity. Responses are typically longer, more in-depth, and carefully communicated to ensure that the customer understands the main ideas.

    Voice Interfaces

    Voice interfaces, in essence, use speech to assist users in accomplishing their objectives. But simply because an interface has a voice component doesn’t mean that every user interaction with it is mediated through voice. We’re most concerned with pure voice interfaces, which depend entirely on spoken conversation and lack any visual component, making multimodal voice interfaces much more nuanced and challenging to deal with because they can lean on visual components like screens as crutches.

    Though voice interfaces have long been integral to the imagined future of humanity in science fiction, only recently have those lofty visions become fully realized in genuine voice interfaces.

    IVR ( interactive voice response ) systems

    Though written conversational interfaces have been fixtures of computing for many decades, voice interfaces first emerged in the early 1990s with text-to-speech ( TTS ) dictation programs that recited written text aloud, as well as speech-enabled in-car systems that gave directions to a user-provided address. We became familiar with the first real voice interfaces that engaged in authentic conversation with the advent of interactive voice response ( IVR ) systems, which were created as an alternative to overburdened customer service representatives.

    IVR systems allowed organizations to reduce their reliance on call centers but soon became notorious for their clunkiness. Similar to the corporate world, these systems were primarily created as metaphorical switchboards to direct customers to a real phone agent (” Say Reservations to book a flight or check an itinerary” ), and chances are you’ll have a conversation with one when you call an airline or hotel conglomerate. Despite their functional issues and users ‘ frustration with their inability to speak to an actual human right away, IVR systems proliferated in the early 1990s across a variety of industries (, PDF).

    IVR systems have a reputation for having less scintillating conversations than we’re used to in real life ( or even in science fiction ), despite being extremely repetitive and monotonous conversations that typically don’t veer from a single format.

    Screen readers

    The invention of the screen reader, a tool that converts visual content into synthesized speech, was a development of IVR systems in parallel. For Blind or visually impaired website users, it’s the predominant method of interacting with text, multimedia, or form elements. The most recent version of a voice-over-text format of content delivery is probably the one that is closest to it.

    Among the first screen readers known by that moniker was the Screen Reader for the BBC Micro and NEEC Portable developed by the Research Centre for the Education of the Visually Handicapped (RCEVH) at the University of Birmingham in 1986 ( ). In the same year, Jim Thatcher created the first IBM Screen Reader for text-based computers, which was later reworked for computers with graphical user interfaces ( GUIs ) ( ).

    With the rapid growth of the web in the 1990s, the demand for accessible tools for websites exploded. Screen readers started facilitating quick interactions with web pages that ostensibly allow disabled users to traverse the page as an aural and temporal space rather than a visual and physical one with the introduction of semantic HTML and especially ARIA roles in 2008, enabling speedy interactions with the pages. In other words, screen readers for the web “provide mechanisms that translate visual design constructs—proximity, proportion, etc. —into useful information,” according to Aaron Gustafson in A List Apart. ” At least they do when documents are authored thoughtfully” ( ).

    There is a big draw for screen readers: they’re challenging to use and relentlessly verbose, despite being incredibly instructive for voice interface designers. The visual structures of websites and web navigation don’t translate well to screen readers, sometimes resulting in unwieldy pronouncements that name every manipulable HTML element and announce every formatting change. Working with web-based interfaces is a cognitive burden for many screen reader users.

    In Wired, accessibility advocate and voice engineer Chris Maury considers why the screen reader experience is ill-suited to users relying on voice:

    I hated the way Screen Readers operated from the beginning. Why are they designed the way they are? It makes no sense to present information visually before converting it to audio only after that. All of the time and energy that goes into creating the perfect user experience for an app is wasted, or even worse, adversely impacting the experience for blind users. ( ) _ _ _

    In many cases, well-designed voice interfaces can speed users to their destination better than long-winded screen reader monologues. After all, users of the visual interface have the advantage of freely scurrying around the viewport to find information without worrying about it. Blind users, meanwhile, are obligated to listen to every utterance synthesized into speech and therefore prize brevity and efficiency. Users with disabilities who have long had no choice but to use clumsy screen readers might find that voice interfaces, especially more contemporary voice assistants, provide a more streamlined experience.

    Voice assistants

    Many of us immediately associate voice assistants with the popular subset of voice interfaces found in living rooms, smart homes, and offices with the film A Space Odyssey or with Majel Barrett’s voice as the omniscient computer from Star Trek. Voice assistants are akin to personal concierges that can answer questions, schedule appointments, conduct searches, and perform other common day-to-day tasks. And because of their assistive potential, they are quickly gaining more and more attention from accessibility advocates.

    Before the earliest IVR systems found success in the enterprise, Apple published a demonstration video in 1987 depicting the Knowledge Navigator, a voice assistant that could transcribe spoken words and recognize human speech to a great degree of accuracy. Then, in 2001, Tim Berners-Lee and others created their vision for a” semantic web agent” that would carry out routine tasks like” checking calendars, making appointments, and finding locations” ( hinter paywall ). It asn’t unt l 2011 th t pple ‘ Si.

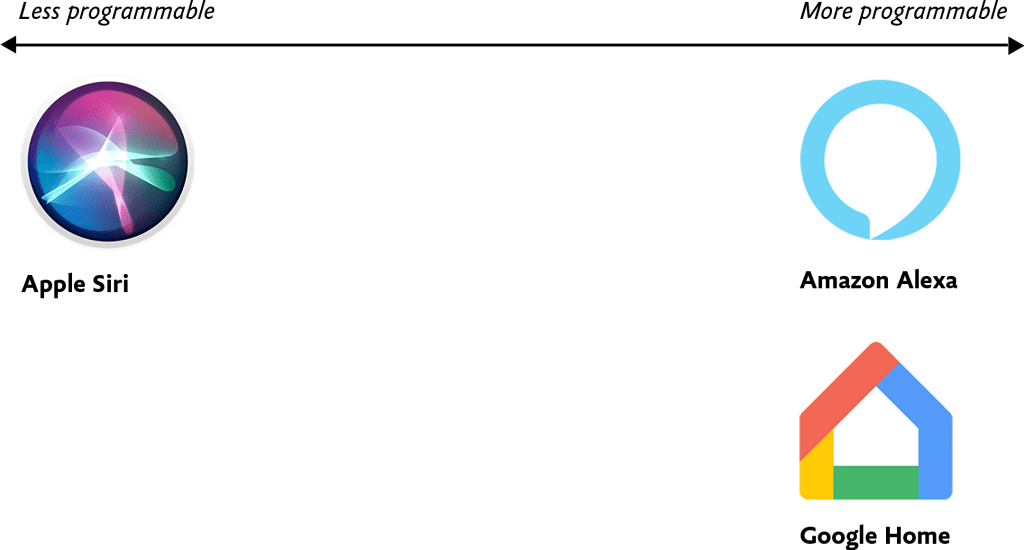
    There is a significant variation in how programmable and customizable some voice assistants are compared to others due to the sheer number of voice assistants available today ( Fig 1 ). At one extreme, everything except vendor-provided features is locked down, for example, at the time of their release, the core functionality of Apple’s Siri and Microsoft’s Cortana couldn’t be extended beyond their existing capabilities. There are no other means by which developers can interact with Siri at a low level, aside from predefined categories of tasks like sending messages, hailing rideshares, making restaurant reservations, and other things, which are still unavoidable today.

    At the opposite end of the spectrum, voice assistants like Amazon Alexa and Google Home offer a core foundation on which developers can build custom voice interfaces. For this reason, developers who feel stifled by the limitations of Siri and Cortana are increasingly using programmable voice assistants that are capable of customization and extensibility. Amazon offers the Alexa Skills Kit, a developer framework for building custom voice interfaces for Amazon Alexa, while Google Home offers the ability to program arbitrary Google Assistant skills. Users today have the option to choose from among the thousands of custom-built skills available in the Google Assistant and Amazon Alexa ecosystems.

    As businesses like Amazon, Apple, Microsoft, and Google continue to occupy their positions, they are also selling and open-sourcing an unheard array of tools and frameworks for designers and developers, aiming to make creating voice interfaces as simple as possible, even without code.

    Often by necessity, voice assistants like Amazon Alexa tend to be monochannel—they’re tightly coupled to a device and can’t be accessed on a computer or smartphone instead. In contrast, many development platforms, like Google’s Dialogflow, now support omnichannel features, allowing users to create a single conversational interface that then becomes a voice interface, textual chatbot, and IVR system upon deployment. I don’t prescribe any specific implementation approaches in this design-focused book, but in Chapter 4 we’ll get into some of the implications these variables might have on the way you build out your design artifacts.

    Voice Content

    Simply put, voice content is content delivered through voice. Voice content must be free-flowing, organic, contextless, and concise in order to preserve what makes human conversation so compelling in the first place.

    Our world is replete with voice content in various forms: screen readers reciting website content, voice assistants rattling off a weather forecast, and automated phone hotline responses governed by IVR systems. We’re most concerned with the content in this book being delivered auditorically, not as an option but as a necessity.

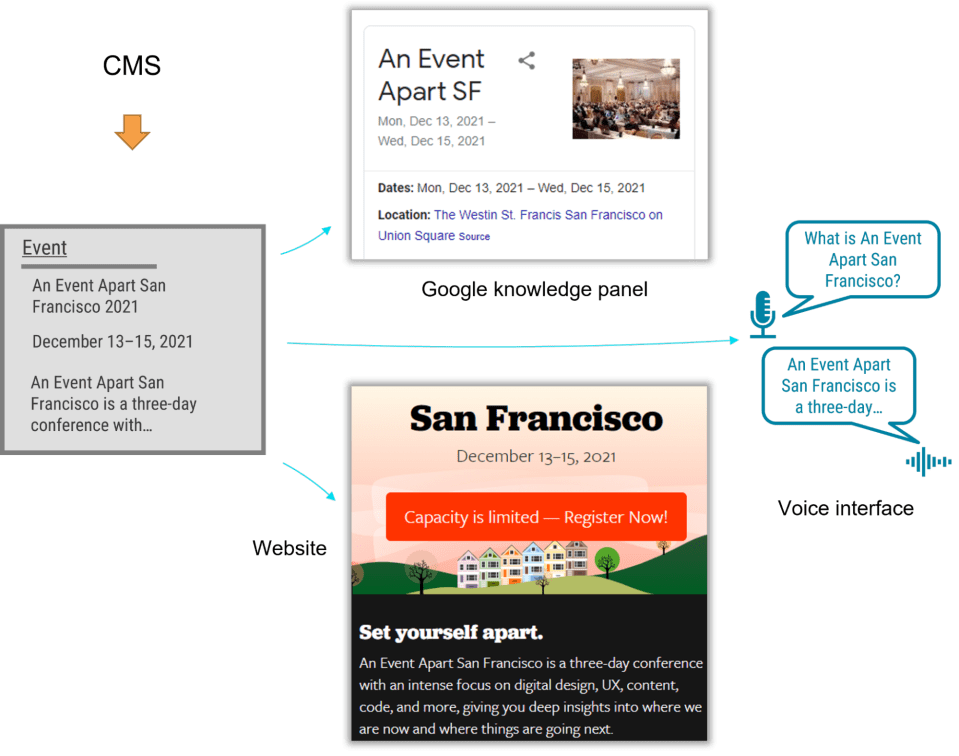
    For many of us, our first foray into informational voice interfaces will be to deliver content to users. There is only one issue: any content we already have isn’t in any way suitable for this new environment. So how do we make the content trapped on our websites more conversational? And how do we create fresh copy that works with voice movements?

    Lately, we’ve begun slicing and dicing our content in unprecedented ways. Websites are, in many ways, massive vaults of what I call macrocontent: lengthy prose that can last for miles in a browser window while extending like microfilm viewers of newspaper archives. Back in 2002, well before the present-day ubiquity of voice assistants, technologist Anil Dash defined microcontent as permalinked pieces of content that stay legible regardless of environment, such as email or text messages:

    An example of microcontent can be a day’s weather forecast [sic], the arrival and departure times for an airplane flight, an abstract from a lengthy publication, or a single instant message. ( ) _ _ _

    I would update Dash’s definition of microcontent to include all instances of bite-sized content that transcends written communiqués. After all, today we encounter microcontent in interfaces where a small snippet of copy is displayed alone, unmoored from the browser, like a textbot confirmation of a restaurant reservation. The best way to learn how to stretch your content to the limits of its potential is through microcontent, which will inform both established and new delivery methods.

    As microcontent, voice content is unique because it’s an example of how content is experienced in time rather than in space. We can instantly look at a digital sign for an instant and be informed when the next train is coming, but voice interfaces keep our attention captive for so long that we can’t quickly evade or skip, a feature that screen reader users are all too familiar with.

    Because microcontent is fundamentally made up of isolated blobs with no relation to the channels where they’ll eventually end up, we need to ensure that our microcontent truly performs well as voice content—and that means focusing on the two most important traits of robust voice content: voice content legibility and voice content discoverability.

    Fundamentally, how voice content manifests in perceived time and space both affect the legibility and discoverability of our voice content.

  • Designing for the Unexpected

    Designing for the Unexpected

    I’m not sure when I first heard this quote, but it’s something that has stayed with me over the years. How do you create services for situations you can’t imagine? Or design products that work on devices yet to be invented?

    Flash, Photoshop, and responsive design

    When I first started designing websites, my go-to software was Photoshop. I created a 960px canvas and set about creating a layout that I would later drop content in. The development phase was about attaining pixel-perfect accuracy using fixed widths, fixed heights, and absolute positioning.

    Ethan Marcotte’s talk at An Event Apart and subsequent article “Responsive Web Design” in A List Apart in 2010 changed all this. I was sold on responsive design as soon as I heard about it, but I was also terrified. The pixel-perfect designs full of magic numbers that I had previously prided myself on producing were no longer good enough.

    The fear wasn’t helped by my first experience with responsive design. My first project was to take an existing fixed-width website and make it responsive. What I learned the hard way was that you can’t just add responsiveness at the end of a project. To create fluid layouts, you need to plan throughout the design phase.

    A new way to design

    Designing responsive or fluid sites has always been about removing limitations, producing content that can be viewed on any device. It relies on the use of percentage-based layouts, which I initially achieved with native CSS and utility classes:

    .column-span-6 {
      width: 49%;
      float: left;
      margin-right: 0.5%;
      margin-left: 0.5%;
    }
    
    
    .column-span-4 {
      width: 32%;
      float: left;
      margin-right: 0.5%;
      margin-left: 0.5%;
    }
    
    .column-span-3 {
      width: 24%;
      float: left;
      margin-right: 0.5%;
      margin-left: 0.5%;
    }

    Then with Sass so I could take advantage of @includes to re-use repeated blocks of code and move back to more semantic markup:

    .logo {
      @include colSpan(6);
    }
    
    .search {
      @include colSpan(3);
    }
    
    .social-share {
      @include colSpan(3);
    }

    Media queries

    The second ingredient for responsive design is media queries. Without them, content would shrink to fit the available space regardless of whether that content remained readable (The exact opposite problem occurred with the introduction of a mobile-first approach).

    Media queries prevented this by allowing us to add breakpoints where the design could adapt. Like most people, I started out with three breakpoints: one for desktop, one for tablets, and one for mobile. Over the years, I added more and more for phablets, wide screens, and so on. 

    For years, I happily worked this way and improved both my design and front-end skills in the process. The only problem I encountered was making changes to content, since with our Sass grid system in place, there was no way for the site owners to add content without amending the markup—something a small business owner might struggle with. This is because each row in the grid was defined using a div as a container. Adding content meant creating new row markup, which requires a level of HTML knowledge.

    Row markup was a staple of early responsive design, present in all the widely used frameworks like Bootstrap and Skeleton.

    1 of 7
    2 of 7
    3 of 7
    4 of 7
    5 of 7
    6 of 7
    7 of 7

    Another problem arose as I moved from a design agency building websites for small- to medium-sized businesses, to larger in-house teams where I worked across a suite of related sites. In those roles I started to work much more with reusable components. 

    Our reliance on media queries resulted in components that were tied to common viewport sizes. If the goal of component libraries is reuse, then this is a real problem because you can only use these components if the devices you’re designing for correspond to the viewport sizes used in the pattern library—in the process not really hitting that “devices that don’t yet exist”  goal.

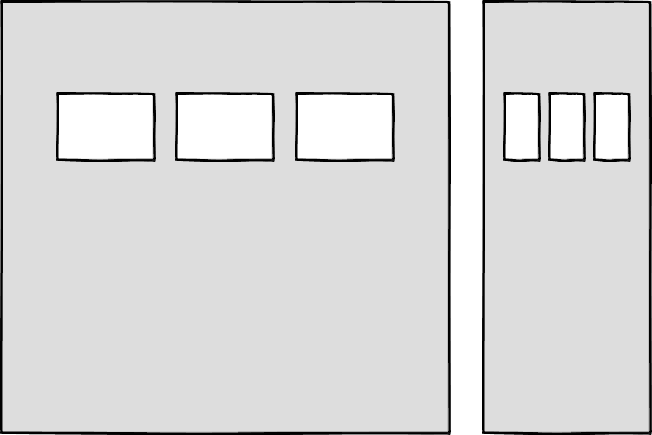
    Then there’s the problem of space. Media queries allow components to adapt based on the viewport size, but what if I put a component into a sidebar, like in the figure below?

    Container queries: our savior or a false dawn?

    Container queries have long been touted as an improvement upon media queries, but at the time of writing are unsupported in most browsers. There are JavaScript workarounds, but they can create dependency and compatibility issues. The basic theory underlying container queries is that elements should change based on the size of their parent container and not the viewport width, as seen in the following illustrations.

    One of the biggest arguments in favor of container queries is that they help us create components or design patterns that are truly reusable because they can be picked up and placed anywhere in a layout. This is an important step in moving toward a form of component-based design that works at any size on any device.

    In other words, responsive components to replace responsive layouts.

    Container queries will help us move from designing pages that respond to the browser or device size to designing components that can be placed in a sidebar or in the main content, and respond accordingly.

    My concern is that we are still using layout to determine when a design needs to adapt. This approach will always be restrictive, as we will still need pre-defined breakpoints. For this reason, my main question with container queries is, How would we decide when to change the CSS used by a component? 

    A component library removed from context and real content is probably not the best place for that decision. 

    As the diagrams below illustrate, we can use container queries to create designs for specific container widths, but what if I want to change the design based on the image size or ratio?

    In this example, the dimensions of the container are not what should dictate the design; rather, the image is.

    It’s hard to say for sure whether container queries will be a success story until we have solid cross-browser support for them. Responsive component libraries would definitely evolve how we design and would improve the possibilities for reuse and design at scale. But maybe we will always need to adjust these components to suit our content.

    CSS is changing

    Whilst the container query debate rumbles on, there have been numerous advances in CSS that change the way we think about design. The days of fixed-width elements measured in pixels and floated div elements used to cobble layouts together are long gone, consigned to history along with table layouts. Flexbox and CSS Grid have revolutionized layouts for the web. We can now create elements that wrap onto new rows when they run out of space, not when the device changes.

    .wrapper {
      display: grid;
      grid-template-columns: repeat(auto-fit, 450px);
      gap: 10px;
    }

    The repeat() function paired with auto-fit or auto-fill allows us to specify how much space each column should use while leaving it up to the browser to decide when to spill the columns onto a new line. Similar things can be achieved with Flexbox, as elements can wrap over multiple rows and “flex” to fill available space. 

    .wrapper {
      display: flex;
      flex-wrap: wrap;
      justify-content: space-between;
    }
    
    .child {
      flex-basis: 32%;
      margin-bottom: 20px;
    }

    The biggest benefit of all this is you don’t need to wrap elements in container rows. Without rows, content isn’t tied to page markup in quite the same way, allowing for removals or additions of content without additional development.

    This is a big step forward when it comes to creating designs that allow for evolving content, but the real game changer for flexible designs is CSS Subgrid. 

    Remember the days of crafting perfectly aligned interfaces, only for the customer to add an unbelievably long header almost as soon as they’re given CMS access, like the illustration below?

    Subgrid allows elements to respond to adjustments in their own content and in the content of sibling elements, helping us create designs more resilient to change.

    .wrapper {
      display: grid;
      grid-template-columns: repeat(auto-fit, minmax(150px, 1fr));
         grid-template-rows: auto 1fr auto;
      gap: 10px;
    }
    
    .sub-grid {
      display: grid;
      grid-row: span 3;
      grid-template-rows: subgrid; /* sets rows to parent grid */
    }

    CSS Grid allows us to separate layout and content, thereby enabling flexible designs. Meanwhile, Subgrid allows us to create designs that can adapt in order to suit morphing content. Subgrid at the time of writing is only supported in Firefox but the above code can be implemented behind an @supports feature query. 

    Intrinsic layouts 

    I’d be remiss not to mention intrinsic layouts, the term created by Jen Simmons to describe a mixture of new and old CSS features used to create layouts that respond to available space. 

    Responsive layouts have flexible columns using percentages. Intrinsic layouts, on the other hand, use the fr unit to create flexible columns that won’t ever shrink so much that they render the content illegible.

    fr units is a way to say I want you to distribute the extra space in this way, but…don’t ever make it smaller than the content that’s inside of it.

    —Jen Simmons, “Designing Intrinsic Layouts”

    Intrinsic layouts can also utilize a mixture of fixed and flexible units, allowing the content to dictate the space it takes up.

    What makes intrinsic design stand out is that it not only creates designs that can withstand future devices but also helps scale design without losing flexibility. Components and patterns can be lifted and reused without the prerequisite of having the same breakpoints or the same amount of content as in the previous implementation. 

    We can now create designs that adapt to the space they have, the content within them, and the content around them. With an intrinsic approach, we can construct responsive components without depending on container queries.

    Another 2010 moment?

    This intrinsic approach should in my view be every bit as groundbreaking as responsive web design was ten years ago. For me, it’s another “everything changed” moment. 

    But it doesn’t seem to be moving quite as fast; I haven’t yet had that same career-changing moment I had with responsive design, despite the widely shared and brilliant talk that brought it to my attention. 

    One reason for that could be that I now work in a large organization, which is quite different from the design agency role I had in 2010. In my agency days, every new project was a clean slate, a chance to try something new. Nowadays, projects use existing tools and frameworks and are often improvements to existing websites with an existing codebase. 

    Another could be that I feel more prepared for change now. In 2010 I was new to design in general; the shift was frightening and required a lot of learning. Also, an intrinsic approach isn’t exactly all-new; it’s about using existing skills and existing CSS knowledge in a different way. 

    You can’t framework your way out of a content problem

    Another reason for the slightly slower adoption of intrinsic design could be the lack of quick-fix framework solutions available to kick-start the change. 

    Responsive grid systems were all over the place ten years ago. With a framework like Bootstrap or Skeleton, you had a responsive design template at your fingertips.

    Intrinsic design and frameworks do not go hand in hand quite so well because the benefit of having a selection of units is a hindrance when it comes to creating layout templates. The beauty of intrinsic design is combining different units and experimenting with techniques to get the best for your content.

    And then there are design tools. We probably all, at some point in our careers, used Photoshop templates for desktop, tablet, and mobile devices to drop designs in and show how the site would look at all three stages.

    How do you do that now, with each component responding to content and layouts flexing as and when they need to? This type of design must happen in the browser, which personally I’m a big fan of. 

    The debate about “whether designers should code” is another that has rumbled on for years. When designing a digital product, we should, at the very least, design for a best- and worst-case scenario when it comes to content. To do this in a graphics-based software package is far from ideal. In code, we can add longer sentences, more radio buttons, and extra tabs, and watch in real time as the design adapts. Does it still work? Is the design too reliant on the current content?

    Personally, I look forward to the day intrinsic design is the standard for design, when a design component can be truly flexible and adapt to both its space and content with no reliance on device or container dimensions.

    Content first 

    Content is not constant. After all, to design for the unknown or unexpected we need to account for content changes like our earlier Subgrid card example that allowed the cards to respond to adjustments to their own content and the content of sibling elements.

    Thankfully, there’s more to CSS than layout, and plenty of properties and values can help us put content first. Subgrid and pseudo-elements like ::first-line and ::first-letter help to separate design from markup so we can create designs that allow for changes.

    Instead of old markup hacks like this—

    First line of text with different styling...

    —we can target content based on where it appears.

    .element::first-line {
      font-size: 1.4em;
    }
    
    .element::first-letter {
      color: red;
    }

    Much bigger additions to CSS include logical properties, which change the way we construct designs using logical dimensions (start and end) instead of physical ones (left and right), something CSS Grid also does with functions like min(), max(), and clamp().

    This flexibility allows for directional changes according to content, a common requirement when we need to present content in multiple languages. In the past, this was often achieved with Sass mixins but was often limited to switching from left-to-right to right-to-left orientation.

    In the Sass version, directional variables need to be set.

    $direction: rtl;
    $opposite-direction: ltr;
    
    $start-direction: right;
    $end-direction: left;

    These variables can be used as values—

    body {
      direction: $direction;
      text-align: $start-direction;
    }

    —or as properties.

    margin-#{$end-direction}: 10px;
    padding-#{$start-direction}: 10px;

    However, now we have native logical properties, removing the reliance on both Sass (or a similar tool) and pre-planning that necessitated using variables throughout a codebase. These properties also start to break apart the tight coupling between a design and strict physical dimensions, creating more flexibility for changes in language and in direction.

    margin-block-end: 10px;
    padding-block-start: 10px;

    There are also native start and end values for properties like text-align, which means we can replace text-align: right with text-align: start.

    Like the earlier examples, these properties help to build out designs that aren’t constrained to one language; the design will reflect the content’s needs.

    Fixed and fluid 

    We briefly covered the power of combining fixed widths with fluid widths with intrinsic layouts. The min() and max() functions are a similar concept, allowing you to specify a fixed value with a flexible alternative. 

    For min() this means setting a fluid minimum value and a maximum fixed value.

    .element {
      width: min(50%, 300px);
    }

    The element in the figure above will be 50% of its container as long as the element’s width doesn’t exceed 300px.

    For max() we can set a flexible max value and a minimum fixed value.

    .element {
      width: max(50%, 300px);
    }

    Now the element will be 50% of its container as long as the element’s width is at least 300px. This means we can set limits but allow content to react to the available space. 

    The clamp() function builds on this by allowing us to set a preferred value with a third parameter. Now we can allow the element to shrink or grow if it needs to without getting to a point where it becomes unusable.

    .element {
      width: clamp(300px, 50%, 600px);
    }

    This time, the element’s width will be 50% (the preferred value) of its container but never less than 300px and never more than 600px.

    With these techniques, we have a content-first approach to responsive design. We can separate content from markup, meaning the changes users make will not affect the design. We can start to future-proof designs by planning for unexpected changes in language or direction. And we can increase flexibility by setting desired dimensions alongside flexible alternatives, allowing for more or less content to be displayed correctly.

    Situation first

    Thanks to what we’ve discussed so far, we can cover device flexibility by changing our approach, designing around content and space instead of catering to devices. But what about that last bit of Jeffrey Zeldman’s quote, “…situations you haven’t imagined”?

    It’s a very different thing to design for someone seated at a desktop computer as opposed to someone using a mobile phone and moving through a crowded street in glaring sunshine. Situations and environments are hard to plan for or predict because they change as people react to their own unique challenges and tasks.

    This is why choice is so important. One size never fits all, so we need to design for multiple scenarios to create equal experiences for all our users.

    Thankfully, there is a lot we can do to provide choice.

    Responsible design 

    “There are parts of the world where mobile data is prohibitively expensive, and where there is little or no broadband infrastructure.”

    “I Used the Web for a Day on a 50 MB Budget”

    Chris Ashton

    One of the biggest assumptions we make is that people interacting with our designs have a good wifi connection and a wide screen monitor. But in the real world, our users may be commuters traveling on trains or other forms of transport using smaller mobile devices that can experience drops in connectivity. There is nothing more frustrating than a web page that won’t load, but there are ways we can help users use less data or deal with sporadic connectivity.

    The srcset attribute allows the browser to decide which image to serve. This means we can create smaller ‘cropped’ images to display on mobile devices in turn using less bandwidth and less data.

    Image alt text

    The preload attribute can also help us to think about how and when media is downloaded. It can be used to tell a browser about any critical assets that need to be downloaded with high priority, improving perceived performance and the user experience. 


    There’s also native lazy loading, which indicates assets that should only be downloaded when they are needed.

    …

    With srcset, preload, and lazy loading, we can start to tailor a user’s experience based on the situation they find themselves in. What none of this does, however, is allow the user themselves to decide what they want downloaded, as the decision is usually the browser’s to make. 

    So how can we put users in control?

    The return of media queries 

    Media queries have always been about much more than device sizes. They allow content to adapt to different situations, with screen size being just one of them.

    We’ve long been able to check for media types like print and speech and features such as hover, resolution, and color. These checks allow us to provide options that suit more than one scenario; it’s less about one-size-fits-all and more about serving adaptable content. 

    As of this writing, the Media Queries Level 5 spec is still under development. It introduces some really exciting queries that in the future will help us design for multiple other unexpected situations.

    For example, there’s a light-level feature that allows you to modify styles if a user is in sunlight or darkness. Paired with custom properties, these features allow us to quickly create designs or themes for specific environments.

    @media (light-level: normal) {
      --background-color: #fff;
      --text-color: #0b0c0c;  
    }
    
    @media (light-level: dim) {
      --background-color: #efd226;
      --text-color: #0b0c0c;
    }

    Another key feature of the Level 5 spec is personalization. Instead of creating designs that are the same for everyone, users can choose what works for them. This is achieved by using features like prefers-reduced-data, prefers-color-scheme, and prefers-reduced-motion, the latter two of which already enjoy broad browser support. These features tap into preferences set via the operating system or browser so people don’t have to spend time making each site they visit more usable. 

    Media queries like this go beyond choices made by a browser to grant more control to the user.

    Expect the unexpected

    In the end, the one thing we should always expect is for things to change. Devices in particular change faster than we can keep up, with foldable screens already on the market.

    We can’t design the same way we have for this ever-changing landscape, but we can design for content. By putting content first and allowing that content to adapt to whatever space surrounds it, we can create more robust, flexible designs that increase the longevity of our products. 

    A lot of the CSS discussed here is about moving away from layouts and putting content at the heart of design. From responsive components to fixed and fluid units, there is so much more we can do to take a more intrinsic approach. Even better, we can test these techniques during the design phase by designing in-browser and watching how our designs adapt in real-time.

    When it comes to unexpected situations, we need to make sure our products are usable when people need them, whenever and wherever that might be. We can move closer to achieving this by involving users in our design decisions, by creating choice via browsers, and by giving control to our users with user-preference-based media queries. 

    Good design for the unexpected should allow for change, provide choice, and give control to those we serve: our users themselves.
  • Sustainable Web Design, An Excerpt

    Sustainable Web Design, An Excerpt

    In the 1950s, some members of the wealthy running group had come to accept the idea that it was impossible to run a hour in less than four hours. Riders had been attempting it since the later 19th century and were beginning to draw the conclusion that the human body just wasn’t built for the job.

    But on May 6, 1956, Roger Bannister caught all off guard. It was a cold, damp morning in Oxford, England—conditions no one expected to give themselves to record-setting—and but Bannister did really that, running a mile in 3: 59.4 and becoming the first people in the history books to run a mile in under four hours.

    The world today knew that the four-minute hour could be accomplished thanks to this change in the criterion. Bannister’s history lasted just forty-six days, when it was snatched aside by American sprinter John Landy. Finally, a year later, three runners all managed to cross the four-minute challenge in the same competition. Since therefore, over 1, 400 walkers have actually run a mile in under four days, the current document is 3: 43.13, held by Moroccan performer Hicham El Guerrouj.

    We do a lot more when we think something is possible, and we only think it can be done when we see someone else doing it once more. As for man running speed, we also think there are strict guidelines for how a website should do.

    Establishing requirements for a lasting web

    The key indicators of climate performance in most big sectors are pretty well established, such as power per square metre for homes and miles per gallon for cars. The tools and methods for calculating those measures are standardized as well, which keeps everyone on the same site when doing economic evaluations. However, in the world of websites and apps, we aren’t held to any specific environmental standards, and we have only recently developed the tools and methods we need to also conduct an environmental assessment.

    The main objective in green web layout is to reduce carbon emissions. However, it’s nearly impossible to accurately assess the amount of CO2 that a website item produces. We can’t measure the pollutants coming out of the exhaust valves on our devices. Our websites ‘ emissions are far away, out of mind, and out of sight when fuel and oil are burned in power plants. We have no way to track the particles from a website or app up to the power station where the light is being generated and really know the exact amount of house oil produced. So what do we accomplish then?

    If we can‘t measure the actual carbon emissions, then we need to get what we can estimate. The following are the main elements that could be used as measures of coal pollution:

    1. Transfer of data
    2. Electricity’s carbon power

    Let’s take a look at how we can use these indicators to calculate the energy use, and in turn the carbon footprint, of the sites and web applications we create.

    Transfer of data

    Most researchers use kilowatt-hours per gigabyte (k Wh/GB ) as a metric of energy efficiency when measuring the amount of data transferred over the internet when a website or application is used. This serves as a reliable indicator of how much energy is being consumed and how much carbon is being released. As a rule of thumb, the more data transferred, the more energy used in the data center, telecoms networks, and end user devices.

    The page weight, or the page’s transfer size in kilobytes, can be most easily calculated for a single visit for web pages. It’s fairly easy to measure using the developer tools in any modern web browser. Statistics for the total data transfer of any web application are frequently included in your web hosting account ( Fig. 2.1 ).

    The nice thing about page weight as a metric is that it allows us to compare the efficiency of web pages on a level playing field without confusing the issue with constantly changing traffic volumes.

    A large scope is required to reduce page weight. By early 2020, the median page weight was 1.97 MB for setups the HTTP Archive classifies as “desktop” and 1.77 MB for “mobile”, with desktop increasing 36 percent since January 2016 and mobile page weights nearly doubling in the same period ( Fig 2.2 ). Image files account for roughly half of this data transfer, making them the single biggest contributor to carbon emissions on the typical website.

    History clearly shows us that our web pages can be smaller, if only we set our minds to it. While most technologies, including the underlying technology of the web like data centers and transmission networks, become more and more energy efficient, websites themselves become less effective as time goes on.

    You might be aware of the project team’s focus on creating faster user experiences using the concept of performance budgeting. For example, we might specify that the website must load in a maximum of one second on a broadband connection and three seconds on a 3G connection. Performance budgets are upper limits rather than hazy ideas, much like speed limits while driving. As a result, the goal should always be to stay within budget.

    Designing for fast performance does often lead to reduced data transfer and emissions, but it isn’t always the case. Page weight and transfer size are more objective and reliable benchmarks for sustainable web design, whereas web performance is frequently more about the subjective perception of load times than it is about the underlying system’s actual efficiency.

    We can set a page weight budget in reference to a benchmark of industry averages, using data from sources like HTTP Archive. We can also use competitor page weight to compare the new website to the old one. For example, we might set a maximum page weight budget as equal to our most efficient competitor, or we could set the benchmark lower to guarantee we are best in class.

    We could start looking at the transferability of our web pages for repeat visitors if we want to take it one step further. Although page weight for the first time someone visits is the easiest thing to measure, and easy to compare on a like-for-like basis, we can learn even more if we start looking at transfer size in other scenarios too. For instance, visitors who load the same page more frequently are likely to have a high percentage of the files cached in their browser, which means they don’t need to move all the files on subsequent visits. Likewise, a visitor who navigates to new pages on the same website will likely not need to load the full page each time, as some global assets from areas like the header and footer may already be cached in their browser. We can learn even more about how to optimize efficiency for users who regularly visit our pages by measuring transfer size at this next level of detail, which will also enable us to establish page weight budgets for situations that extend beyond the initial visit.

    Page weight budgets are easy to track throughout a design and development process. Although they don’t directly disclose carbon emissions and energy consumption data, they do provide a clear indicator of efficiency in comparison to other websites. And as transfer size is an effective analog for energy consumption, we can actually use it to estimate energy consumption too.

    In summary, less data transfer leads to more energy efficiency, which is a crucial component of lowering web product carbon emissions. The more efficient our products, the less electricity they use, and the less fossil fuels need to be burned to produce the electricity to power them. However, as we’ll see next, it’s important to take into account the source of that electricity because all web products require some.

    Electricity’s carbon power

    Regardless of energy efficiency, the level of pollution caused by digital products depends on the carbon intensity of the energy being used to power them. The term” carbon intensity” is used to describe how many grams of carbon are produced for every kilowatt-hour of electricity (gCO2/k Wh ). This varies widely, with renewable energy sources and nuclear having an extremely low carbon intensity of less than 10 gCO2/k Wh ( even when factoring in their construction ), whereas fossil fuels have very high carbon intensity of approximately 200–400 gCO2/k Wh.

    The majority of electricity is produced by national or state grids, where different levels of carbon intensity are combined with energy from a variety of sources. The distributed nature of the internet means that a single user of a website or app might be using energy from multiple different grids simultaneously, a website user in Paris uses electricity from the French national grid to power their home internet and devices, but the website’s data center could be in Dallas, USA, pulling electricity from the Texas grid, while the telecoms networks use energy from everywhere between Dallas and Paris.

    Although we don’t have complete control over the energy supply of web services, we do have some control over where our projects are hosted. With a data center using a significant proportion of the energy of any website, locating the data center in an area with low carbon energy will tangibly reduce its carbon emissions. Danish startup Tomorrow reports and maps the user-provided data, and a look at their map demonstrates how, for instance, choosing a data center in France will result in significantly lower carbon emissions than choosing a data center in the Netherlands ( Fig. 2.3 ).

    However, we don’t want to move our servers too far away from our users because it requires a lot of energy to transmit data through the telecom’s networks, and the more energy is used, the further the data travels. Just like food miles, we can think of the distance from the data center to the website’s core user base as “megabyte miles” —and we want it to be as small as possible.

    We can use website analytics to determine the country, state, or even city where our core user group is located and determine the distance between that location and the data center that our hosting company uses as a benchmark. This will be a somewhat fuzzy metric as we don’t know the precise center of mass of our users or the exact location of a data center, but we can at least get a rough idea.

    For instance, if a website is hosted in London but the main audience is on the United States ‘ West Coast, we could calculate the distance between San Francisco and London, which is 5,300 miles. That’s a long way! We can see how hosting it somewhere in North America, ideally on the West Coast, would significantly shorten the distance and the amount of energy needed to transmit the data. In addition, locating our servers closer to our visitors helps reduce latency and delivers better user experience, so it’s a win-win.

    Reverting it to carbon emissions

    If we combine carbon intensity with a calculation for energy consumption, we can calculate the carbon emissions of our websites and apps. A tool my team created accomplishes this by measuring the data transfer over the wire when a web page is loaded, calculating the associated electricity consumption, and then converting that data into a CO2 figure ( Fig. 2.4). It also factors in whether or not the web hosting is powered by renewable energy.

    The Energy and Emissions Worksheet that comes with this book teaches you how to improve it and tailor the data more appropriately to your project’s unique features.

    We could even expand our page weight budget by establishing carbon budgets as well with the ability to calculate carbon emissions for our projects. CO2 is not a metric commonly used in web projects, we’re more familiar with kilobytes and megabytes, and can fairly easily look at design options and files to assess how big they are. Although translating that into carbon adds a layer of abstraction that isn’t as intuitive, carbon budgets do focus our minds on the main thing we’re trying to reduce, and this is in line with the main goal of sustainable web design: reducing carbon emissions.

    Browser Energy

    Transfer of data might be the simplest and most complete analog for energy consumption in our digital projects, but by giving us one number to represent the energy used in the data center, the telecoms networks, and the end user’s devices, it can’t offer us insights into the efficiency in any specific part of the system.

    One part of the system we can look at in more detail is the energy used by end users ‘ devices. The computational load is increasingly shifting from the data center to users ‘ devices, whether they are phones, tablets, laptops, desktops, or even smart TVs, as front-end web technologies advance. Modern web browsers allow us to implement more complex styling and animation on the fly using CSS and JavaScript. Additionally, JavaScript libraries like Angular and React allow us to create applications where the” thinking” process is performed either partially or completely in the browser.

    All of these advances are exciting and open up new possibilities for what the web can do to serve society and create positive experiences. However, more energy is used by the user’s devices as a result of the user’s web browser’s increased computation. This has implications not just environmentally, but also for user experience and inclusivity. Applications that put a lot of processing power on a user’s device unintentionally make them use older, slower devices and make their phones and laptops ‘ batteries discharge more quickly. Furthermore, if we build web applications that require the user to have up-to-date, powerful devices, people throw away old devices much more frequently. This not only harms the environment, but it places a disproportionate financial burden on the poorest members of society.

    In part because the tools are limited, and partly because there are so many different models of devices, it’s difficult to measure website energy consumption on end users ‘ devices. The Energy Impact monitor inside the developer console of the Safari browser is one of the tools we currently have ( Fig. 2.5 ).

    You know when your computer’s cooling fans start spinning so frantically that you suspect it might take off when you load a website? That’s essentially what this tool is measuring.

    It uses these figures to create an energy impact rating based on the percentage of CPU used and how long it took the web page to load. It doesn’t give us precise data for the amount of electricity used in kilowatts, but the information it does provide can be used to benchmark how efficiently your websites use energy and set targets for improvement.

  • A Content Model Is Not a Design System

    A Content Model Is Not a Design System

    Do you recall the days gone by when having a successful site was sufficient? Today, people are getting answers from Siri, Google search fragments, and mobile applications, not only our websites. Organizations with forward-thinking goals have adopted an holistic content strategy that aims to reach people across a range of digital programs and platforms.

    But how can a content management system ( CMS ) be set up to reach your current and future audience? I learned the hard way that creating a content model—a concept of information types, attributes, and relationships that let people and systems understand content—with my more comfortable design-system wondering would collapse my patient’s holistic information strategy. By developing willing versions that are conceptual and that also connect related information, you can avoid that result.

    I just had the opportunity to direct the CMS application for a Fortune 500 company. The customer was excited by the benefits of an holistic information plan, including material modify, multichannel marketing, and robot delivery—designing content to be comprehensible to bots, Google knowledge panels, snippets, and voice user interfaces.

    A content type is essential to an holistic content strategy, and it required conceptual types to be given names that don’t depend on how the content is presented. Our goal was to allow artists to create original content that could be used wherever they felt was most useful. But as the job proceeded, I realized that supporting material utilize at the range that my client needed required the whole group to identify a new pattern.

    Despite our best efforts, we remained influenced by pattern systems, which we were more comfortable with. An holistic content strategy doesn’t rely on WYSIWYG equipment for design and layout, unlike web-focused material strategies. Our tendency to approach the material model with our common design-system thinking frequently led us to veer away from one of the main purposes of a material model: delivering content to audiences on various marketing channels.

    Two fundamental tenets are necessary for a successful content model

    We had to explain to our designers, developers, and stakeholders that their previous web projects had taught them that content should be treated as visual building blocks that fit into layouts. The previous approach was not only more familiar but also more intuitive—at least at first—because it made the designs feel more tangible. The team was able to understand how a content model differs from the design systems we were familiar with by discovering two principles:

    1. Instead of layout, content models must define semantics.
    2. And content models should connect content that belongs together.

    Semantic content models

    A semantic content model uses type and attribute names that reflect the content’s intended purpose and not how it will be displayed. For example, in a nonsemantic model, teams might create types like teasers, media blocks, and cards. These types may simplify the presentation of content, but they do not aid in understanding the meaning of the content, which would have opened the door to the content presented in each marketing channel. In contrast, a semantic content model uses type names like “product,”” service,” and “testimonial” to allow for each delivery channel to interpret and use the content as it sees fit.

    When you’re creating a semantic content model, a great place to start is to look over the types and properties defined by Schema. a community-driven resource for type definitions that are understandable on platforms like Google search.

    Benefits of a semantic content model include:

      Even if your team doesn’t care about omnichannel content, a semantic content model decouples content from its presentation so that teams can evolve the website’s design without needing to refactor its content. Content can withstand obtrusive website redesigns in this way.
    • A semantic content model also gives you a competitive advantage. By adding structured data based on Schema. Using its types and properties, a website can provide hints to help Google understand the content, display it in search snippets or knowledge panels, and use it to respond to voice-interface user questions. Potential customers could access your content without ever visiting your website.
    • Beyond those practical benefits, you’ll also need a semantic content model if you want to deliver omnichannel content. Delivery channels must be able to comprehend the same content in order to use it across multiple marketing channels. For instance, if your content model provided a list of questions and answers, it could be easily displayed on a frequently asked questions ( FAQ ) page as well, but it could also be used by a bot that answers frequently asked questions.

    For example, using a semantic content model for articles, events, people, and locations lets A List Apart provide cleanly structured data for search engines so that users can read the content on the website, in Google knowledge panels, and even with hypothetical voice interfaces in the future.

    Content models that connect

    Instead of slicing up related content across disparate content components, I’ve come to the realization that the best models are those that are semantic and also connect related content components ( such as a FAQ item’s question and answer pair ). A good content model connects content that should remain together so that multiple delivery channels can use it without needing to first put those pieces back together.

    Consider creating an essay or article. The meaning and usefulness of an article depend on how well its components are kept together. Would one of the headings or paragraphs be meaningful on their own without the context of the full article? Our well-known design-system thinking on our project frequently led us to want to develop content models that would divide content into distinct chunks to fit the web-centric layout. This had a similar effect to an article that had its headline removed. Because we were slicing content into standalone pieces based on layout, content that belonged together became difficult to manage and nearly impossible for multiple delivery channels to understand.

    Let’s examine how connecting related content can be used in a practical setting to illustrate. A complex layout for a software product page that included multiple tabs and sections was presented by the client’s design team. Our instincts were to follow suit with the content model. Shouldn’t we make adding multiple tabs in the future as simple and flexible as possible?

    Because our design-system instincts were so well-known, it appeared that we needed a “tab section” content type so that multiple tab sections could be added to a page. Each tab section would display various types of content. One tab might contain the software’s information or specifications. A list of resources might be found under another tab.

    Our inclination to break down the content model into “tab section” pieces would have led to an unnecessarily complex model and a cumbersome editing experience, and it would have also created content that couldn’t have been understood by additional delivery channels. How would a different system have been able to determine which “tab section” referred to a product’s specifications or resource list, for instance? Would that system have had to have used tab sections and content blocks to calculate this? This would have prevented the tabs from ever being rearranged, and logic would have had to be added to each other delivery channel to interpret the layout of the design system. Furthermore, if the customer were to have no longer wanted to display this content in a tab layout, it would have been tedious to migrate to a new content model to reflect the new page redesign.

    Our customer had a breakthrough when we realized that for each tab, a specific purpose in mind would be revealed, such as the software product’s overview, specifications, related resources, and pricing. Once implementation began, our inclination to focus on what’s visual and familiar had obscured the intent of the designs. It wasn’t long after a little digging that the idea of tabs wasn’t applicable to the content model. What was important was the meaning of the information that they intended to display in the tabs.

    In fact, the customer could have decided to display this content in a different way—without tabs—somewhere else. In response to this realization, we created content types for the software product based on the meaningful attributes the client wanted to display on the web. There were both obvious semantic attributes like name and description and rich ones like screenshots, software requirements, and feature lists. The software’s product information stayed together because it wasn’t sliced across separate components like “tab sections” that were derived from the content’s presentation. This content could be understood and presented by any delivery channel, including those that come up in the future.

    Conclusion

    In this omnichannel marketing project, we discovered that the best way to keep our content model on track was to ensure that it was semantic ( with type and attribute names that reflected the meaning of the content ) and that it kept content together that belonged together ( instead of fragmenting it ). These two ideas made it easier for us to decide what to do with the content model based on the design. Remember: If you’re developing a content model to support an omnichannel content strategy, or even if you just want to make sure that Google and other interfaces understand your content, keep in mind:

    • A design system isn’t a content model. You should maintain the semantic value and contextual structure of the content strategy throughout the entire implementation process because team members might be tempted to combine them and to make your content model resemble your design system. This will enable each delivery channel to consume the content without the need for a magic decoder ring.
    • If your team is struggling to make this transition, you can still reap some of the benefits by using Schema. Your website uses structured data from org. The benefit of search engine optimization is a compelling argument on its own, even if additional delivery channels aren’t on the horizon at this time.
    • Additionally, remind the team that decoupling the content model from the design will let them update the designs more easily because they won’t be held back by the cost of content migrations. They’ll be able to create new designs without compromising the compatibility between the content and the design, and they’ll be prepared for the upcoming big thing.

    By firmly defending these ideas, you’ll help your team treat content the way it deserves as the most important component of your user experience and the best way to engage with your audience.