Category: Blog

Your blog category

  • Sustainable Web Design, An Excerpt

    Sustainable Web Design, An Excerpt

    Many wealthy runners had come to the conclusion that it was impossible to run a mile in less than four hours in the 1950s. Riders had been attempting it since the later 19th century and were beginning to draw the conclusion that the human body just wasn’t built for the job.

    But Roger Bannister surprised all on May 6, 1956. It was a cold, damp morning in Oxford, England—conditions no one expected to give themselves to record-setting—and but Bannister did really that, running a mile in 3: 59.4 and becoming the first people in the history books to run a mile in under four hours.

    The world presently knew that the four-minute hour could be accomplished thanks to this change in the standard. Bannister’s history lasted just forty-six days, when it was snatched aside by American sprinter John Landy. Finally, in the same race, three athletes all managed to cross the four-minute challenge. Since therefore, over 1, 400 walkers have actually run a mile in under four days, the current document is 3: 43.13, held by Moroccan performer Hicham El Guerrouj.

    We can do a lot more with what we think is possible, and we can only do it if we see that someone else has already done it. As with individual running speed, there are also hard limits on how a website can accomplish.

    Establishing requirements for a green website

    The key indicators of climate performance in most big sectors are pretty well established, such as power per square metre for homes and miles per gallon for cars. The tools and methods for calculating those measures are standardized as well, which keeps everyone on the same site when doing economic evaluations. But, we are not required to follow any specific environmental standards in the world of websites and apps, and we have only recently developed the tools and methods to do so.

    The main objective in green web layout is to reduce carbon emissions. However, it’s nearly impossible to accurately assess the CO2 output of a website product. We didn’t measure the pollutants coming out of the exhaust valves on our laptops. Our websites ‘ emissions are far away, out of mind, and out of sight when fuel and fuel are burned in power plants. We have no way to track the particles from a website or app up to the power station where the light is being generated and really know the exact amount of house oil produced. What then do we do?

    If we can‘t measure the actual carbon emissions, then we need to get what we can estimate. The following are the main elements that could be used as coal pollution gauges:

    1. Transfer of data
    2. Electricity’s coal power

    Let’s take a look at how we can use these indicators to calculate the energy use, and in turn the carbon footprint, of the sites and web applications we create.

    Transfer of data

    Most researchers use kilowatt-hours per gigabyte (k Wh/GB ) as a metric of energy efficiency when measuring the amount of data transferred over the internet when a website or application is used. This serves as a wonderful example of how much energy is consumed and how much carbon is released. As a rule of thumb, the more files transferred, the more electricity used in the data center, telecoms systems, and end users products.

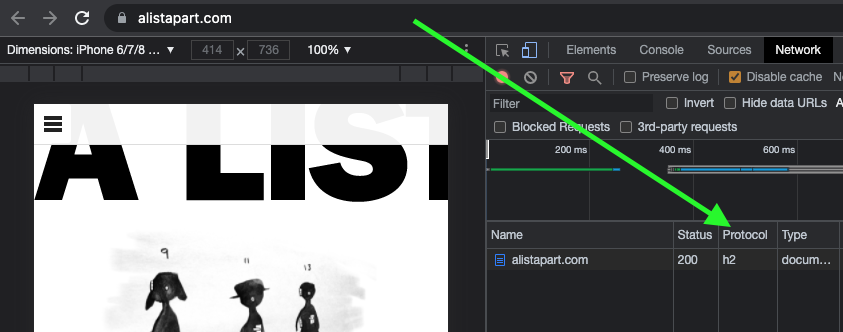
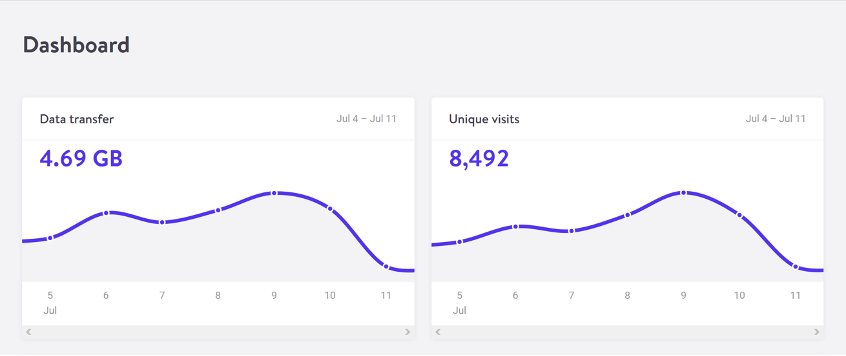
    The site weight, or the page’s transfer size in kilobytes, can be most readily calculated for a single visit for web pages. It’s very easy to measure using the engineer equipment in any modern internet browser. Statistics for the total data transfer of any web application are frequently included in your web hosting account ( Fig. 2.1 ).

    The great thing about website weight as a parameter is that it allows us to compare the effectiveness of web pages on a level playing field without confusing the problem with frequently changing traffic volumes.

    A large scope is required to reduce page weight. By early 2020, the median page weight was 1.97 MB for setups the HTTP Archive classifies as “desktop” and 1.77 MB for “mobile”, with desktop increasing 36 percent since January 2016 and mobile page weights nearly doubling in the same period ( Fig 2.2 ). Image files account for roughly half of this data transfer, making them the single biggest contributor to carbon emissions on a typical website.

    History clearly shows us that our web pages can be smaller, if only we set our minds to it. While the majority of technologies, including the underlying technology of the web like data centers and transmission networks, become more and more energy efficient, websites themselves become less effective as time goes on.

    You may be aware of the idea of performance budgeting as a method for directing a project team to deliver faster user experiences. For example, we might specify that the website must load in a maximum of one second on a broadband connection and three seconds on a 3G connection. Performance budgets are upper limits rather than hazy ideas, much like speed limits while driving. As a result, the goal should always be to stay within budget.

    Designing for fast performance does often lead to reduced data transfer and emissions, but it isn’t always the case. Page weight and transfer size are more objective and reliable benchmarks for sustainable web design, but web performance is frequently more about the subjective perception of load times than it is about the underlying system’s true efficiency.

    We can set a page weight budget in reference to a benchmark of industry averages, using data from sources like HTTP Archive. We can also use competitor page weights and the website’s current layout to compare it to. For example, we might set a maximum page weight budget as equal to our most efficient competitor, or we could set the benchmark lower to guarantee we are best in class.

    If we want to take it to the next level, we could start looking at how much more popular our web pages are when people visit them frequently. Although page weight for the first time someone visits is the easiest thing to measure, and easy to compare on a like-for-like basis, we can learn even more if we start looking at transfer size in other scenarios too. For instance, repeat users who load the same page frequently will likely have a high percentage of the files cached in their browser, which means they won’t need to move all of the files back on subsequent visits. Likewise, a visitor who navigates to new pages on the same website will likely not need to load the full page each time, as some global assets from areas like the header and footer may already be cached in their browser. We can learn even more about how to optimize efficiency for users who regularly visit our pages by measuring transfer size at this next level of detail, which will also enable us to establish page weight budgets for situations that extend beyond the initial visit.

    Page weight budgets are easy to track throughout a design and development process. Although they don’t directly disclose carbon emissions and energy consumption data, they do provide a clear indicator of efficiency in comparison to other websites. And as transfer size is an effective analog for energy consumption, we can actually use it to estimate energy consumption too.

    In summary, less data transfer leads to more energy efficiency, which is a crucial component of lowering web product carbon emissions. The more efficient our products, the less electricity they use, and the less fossil fuels need to be burned to produce the electricity to power them. However, as we’ll see next, it’s important to take into account the source of that electricity because all web products require some.

    Electricity’s coal power

    Regardless of energy efficiency, the level of pollution caused by digital products depends on the carbon intensity of the energy being used to power them. The term” carbon intensity” (gCO2/k Wh ) is used to describe how much carbon dioxide is produced for each kilowatt-hour of electricity produced. This varies widely, with renewable energy sources and nuclear having an extremely low carbon intensity of less than 10 gCO2/k Wh ( even when factoring in their construction ), whereas fossil fuels have very high carbon intensity of approximately 200–400 gCO2/k Wh.

    The majority of electricity is produced by national or state grids, where different levels of carbon intensity are combined with energy from a variety of sources. The distributed nature of the internet means that a single user of a website or app might be using energy from multiple different grids simultaneously, a website user in Paris uses electricity from the French national grid to power their home internet and devices, but the website’s data center could be in Dallas, USA, pulling electricity from the Texas grid, while the telecoms networks use energy from everywhere between Dallas and Paris.

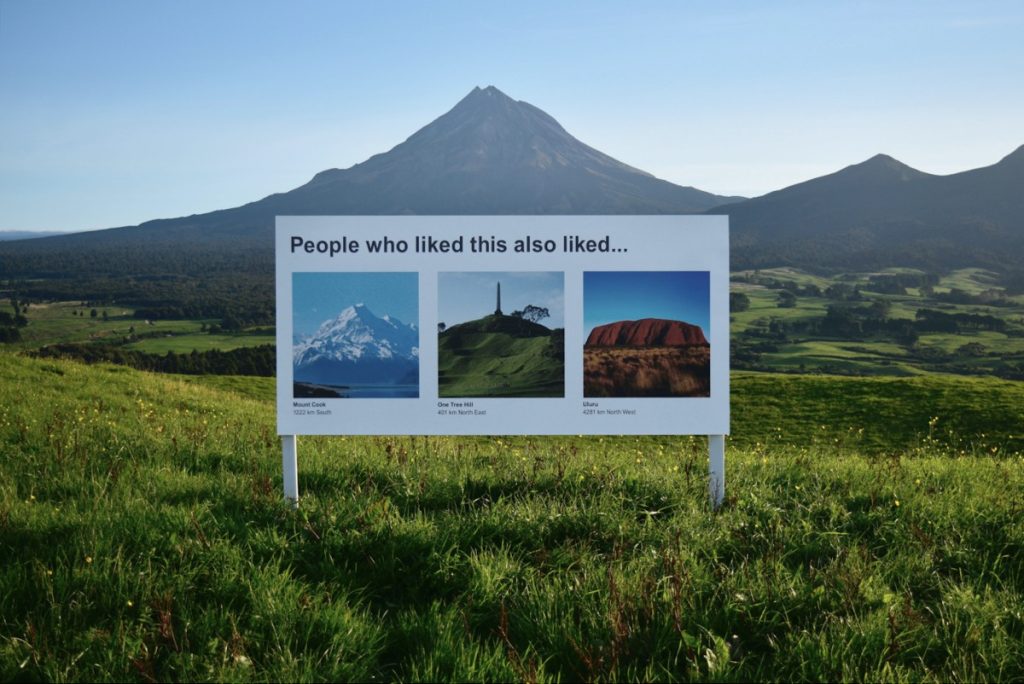
    Although we don’t have complete control over the energy supply of web services, we do have some control over where our projects are hosted. With a data center using a significant proportion of the energy of any website, locating the data center in an area with low carbon energy will tangibly reduce its carbon emissions. This user-provided data is reported and mapped by Danish startup Tomorrow, and a look at their map demonstrates how, for instance, choosing a data center in France will result in significantly lower carbon emissions than choosing a data center in the Netherlands ( Fig. 2.3 ).

    Having said that, we don’t want to locate our servers too far away from our users; however, it takes energy to transmit data through the telecom’s networks, and the more energy is used, the further the data travels. Just like food miles, we can think of the distance from the data center to the website’s core user base as “megabyte miles” —and we want it to be as small as possible.

    We can use website analytics to determine the country, state, or even city where our core user group is located and determine the distance between that location and the data center that our hosting company uses as a benchmark. This will be a somewhat fuzzy metric as we don’t know the precise center of mass of our users or the exact location of a data center, but we can at least get a rough idea.

    For instance, if a website is hosted in London but the main audience is on the United States ‘ West Coast, we could look up the travel distance between London and San Francisco, which is 5,300 miles. That’s a long way! We can see how hosting it somewhere in North America, ideally on the West Coast, would significantly shorten the distance and the amount of energy needed to transmit the data. In addition, locating our servers closer to our visitors helps reduce latency and delivers better user experience, so it’s a win-win.

    Reverting it to carbon emissions

    If we combine carbon intensity with a calculation for energy consumption, we can calculate the carbon emissions of our websites and apps. The method my team developed converts the data transferred over wire when loading a website into a CO2 figure ( Fig. 2.4), calculating the associated electricity, and then converting that data into a figure ( Fig. 2.4). It also factors in whether or not the web hosting is powered by renewable energy.

    The Energy and Emissions Worksheet that comes with this book teaches you how to take it one step further and tailor the data more precisely to the unique aspects of your project.

    With the ability to calculate carbon emissions for our projects, we could actually expand our page weight budget and establish carbon budgets as well. CO2 is not a metric commonly used in web projects, we’re more familiar with kilobytes and megabytes, and can fairly easily look at design options and files to assess how big they are. Although translating that into carbon adds a layer of abstraction that isn’t as intuitive, carbon budgets do focus our minds on the main thing we’re trying to reduce, and this is in line with the main goal of sustainable web design: reducing carbon emissions.

    Browser Energy

    Transfer of data might be the simplest and most complete analog for energy consumption in our digital projects, but by giving us one number to represent the energy used in the data center, the telecoms networks, and the end user’s devices, it can’t offer us insights into the efficiency in any specific part of the system.

    One part of the system we can look at in more detail is the energy used by end users ‘ devices. The computational load is increasingly shifting from the data center to users ‘ devices, whether they are phones, tablets, laptops, desktops, or even smart TVs, as front-end web technologies advance. Modern web browsers allow us to implement more complex styling and animation on the fly using CSS and JavaScript. Additionally, JavaScript libraries like Angular and React allow us to create applications where the” thinking” process is performed either partially or completely in the browser.

    All of these advances are exciting and open up new possibilities for what the web can do to serve society and create positive experiences. However, more data is processed in a web browser, which means more energy is used by the user’s devices. This has implications not just environmentally, but also for user experience and inclusivity. Applications that put a lot of processing power on a user’s device unintentionally exclude those who have older, slower devices and make the batteries on phones and laptops drain more quickly. Furthermore, if we build web applications that require the user to have up-to-date, powerful devices, people throw away old devices much more frequently. The poorest members of society are also under disproportionate financial burdens due to this, which is not just bad for the environment.

    In part because the tools are limited, and partly because there are so many different models of devices, it’s difficult to measure website energy consumption on end users ‘ devices. The Energy Impact monitor inside the Safari browser’s developer console ( Fig. 2.5 ) is one of the tools we currently use.

    You know when your computer’s cooling fans start spinning so frantically that you suspect it might take off when you load a website? That’s essentially what this tool is measuring.

    It uses these figures to create an energy impact rating based on the percentage of CPU used and how long it took the web page to load. It doesn’t give us precise data for the amount of electricity used in kilowatts, but the information it does provide can be used to benchmark how efficiently your websites use energy and set targets for improvement.
  • A Content Model Is Not a Design System

    A Content Model Is Not a Design System

    Do you recall the days gone by when having a successful site was sufficient? Nowadays, people are getting answers from Siri, Google search fragments, and mobile applications, not only our websites. Companies with forward-thinking goals have adopted an holistic information plan whose goal is to reach people across a variety of digital stations and platforms.

    However, how can a content management system ( CMS ) be set up to reach your audience both now and in the future? I learned the hard way that creating a content model—a concept of information types, attributes, and relationships that let people and systems understand content—with my more comfortable design-system wondering would collapse my patient’s holistic information strategy. By developing glad versions that are conceptual and that also connect related information, you can avoid that result.

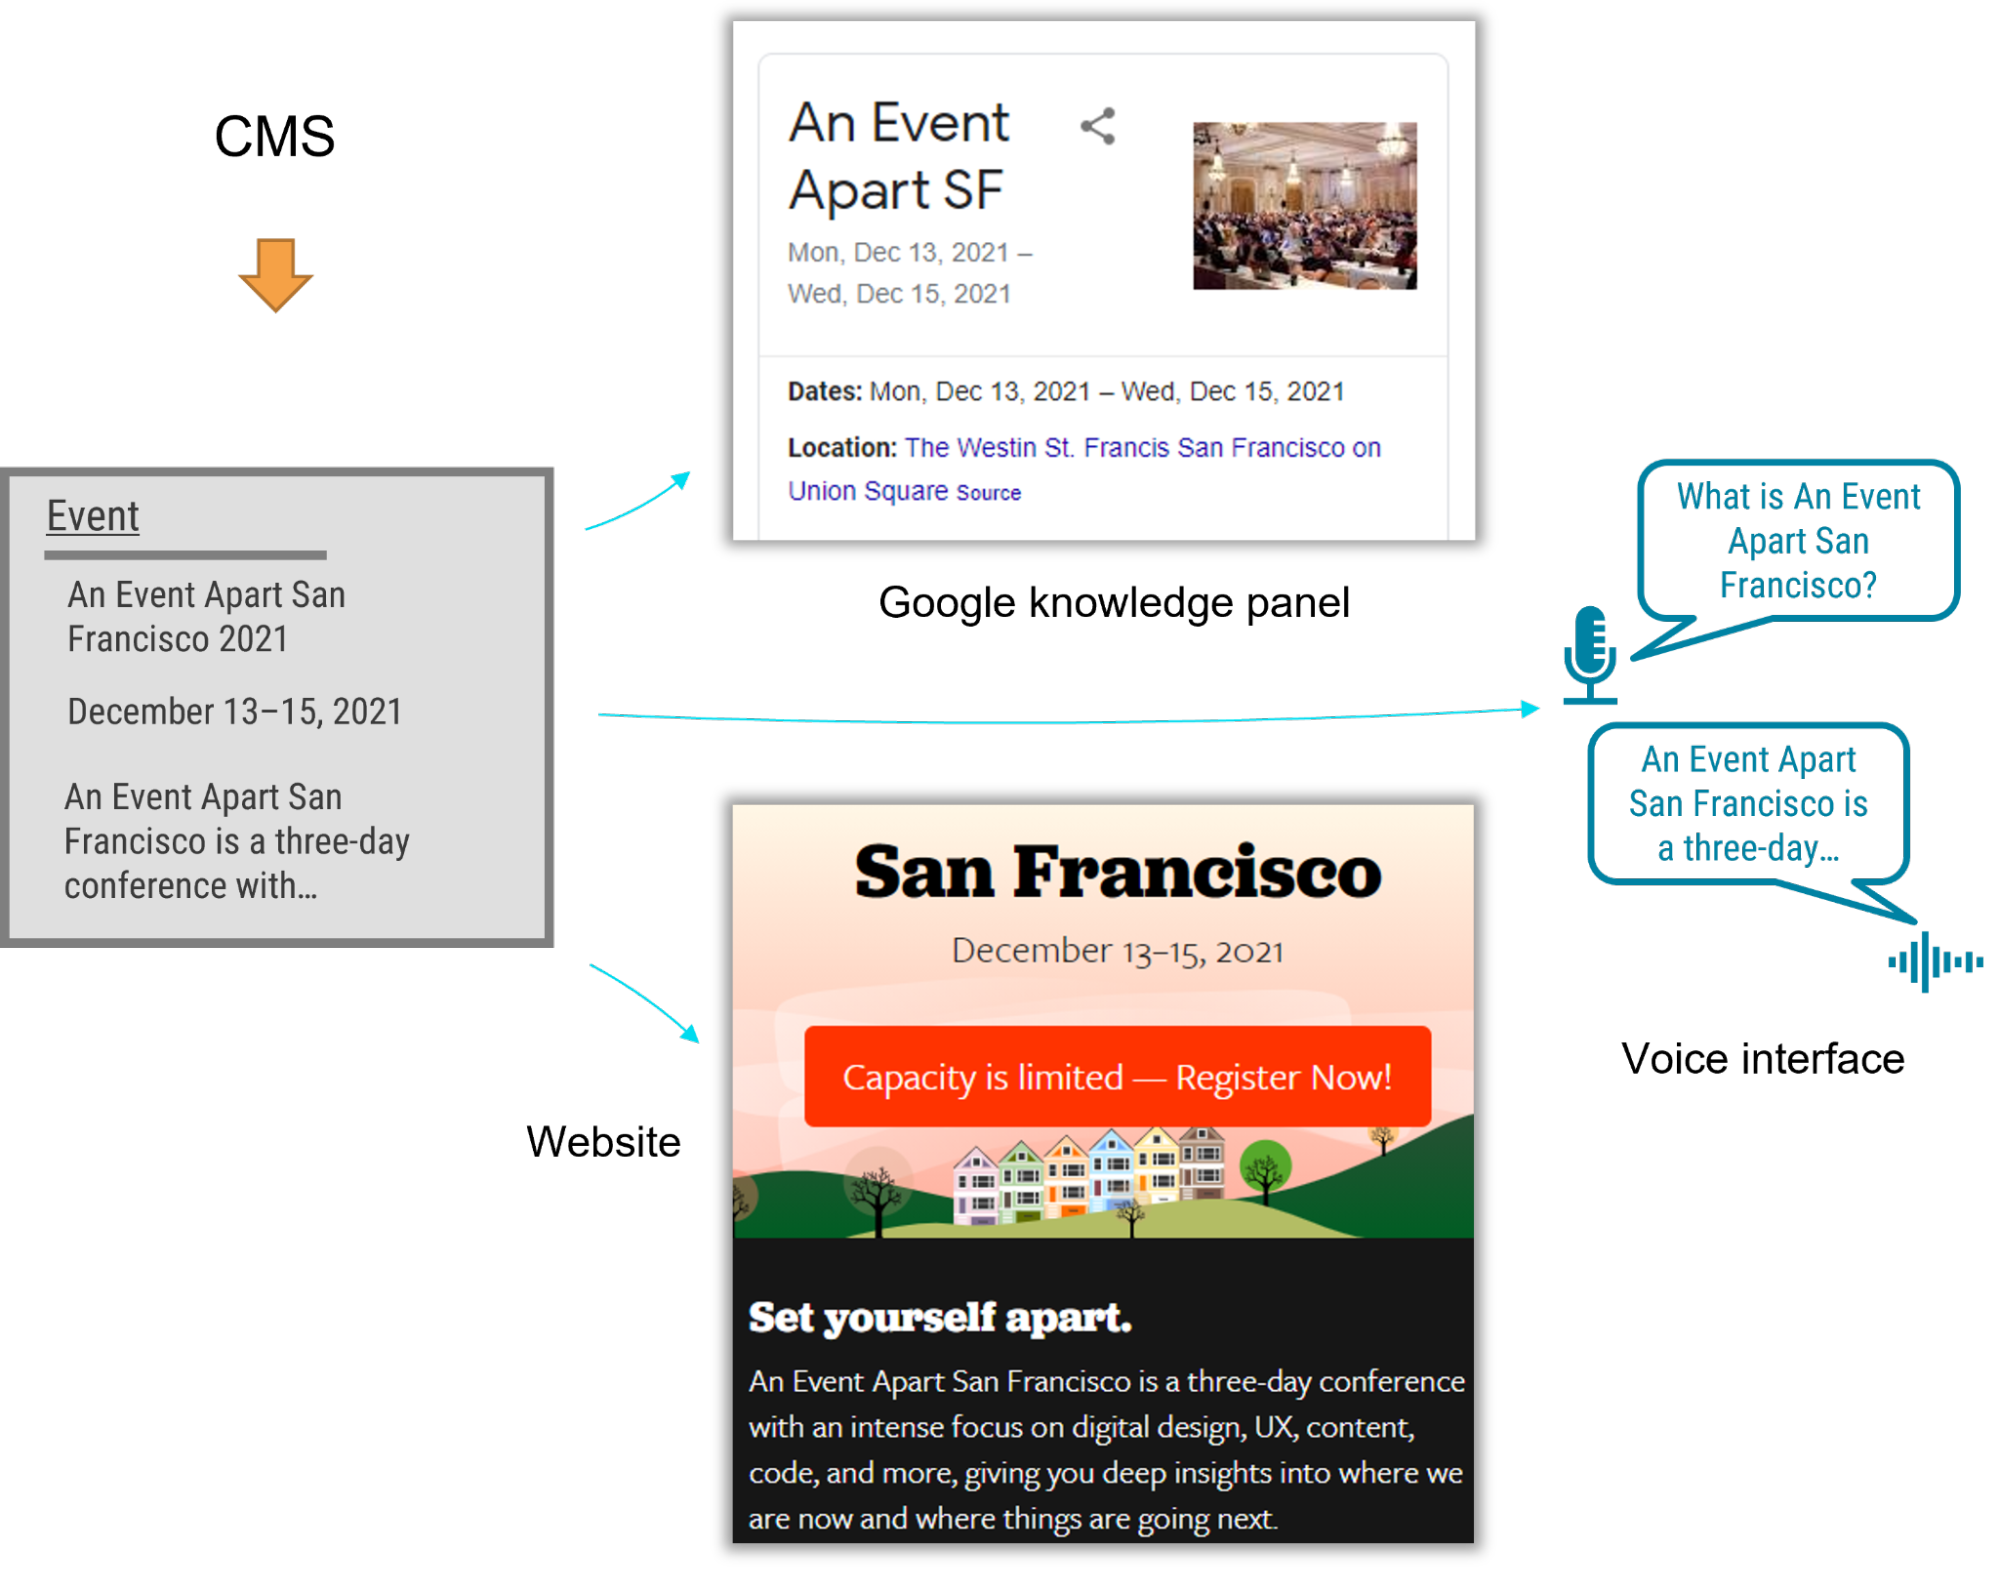
    I just had the opportunity to lead a Fortune 500 company’s CMS application. The customer was excited by the benefits of an holistic information plan, including material modify, multichannel marketing, and robot delivery—designing content to be comprehensible to bots, Google knowledge panels, snippets, and voice user interfaces.

    A content type is essential for an omnichannel information strategy, and the model needed conceptual types, which are types of types that are categorized according to their meaning rather than their presentation. Our goal was to allow artists to create original content that could be used wherever they felt was most useful. However, as the project progressed, I realized that the entire group had to be aware of a new design in order to support material reuse at the level that my customer needed.

    Despite our best motives, we kept drawing from what we were more common with: design techniques. Unlike web-focused material strategies, an holistic information strategy doesn’t rely on WYSIWYG equipment for design and structure. Our inclination to approach the material model using our well-known design-system thinking consistently made us wander away from one of the main objectives of a willing model: delivering content to audiences across multiple marketing channels.

    Two fundamental tenets are necessary for a successful content type

    We needed to explain to our designers, developers, and stakeholders that we were doing something completely different from their previous internet projects, where everyone assumed that content would fit into layouts as physical building blocks. The past approach made the designs feel more recognizable and intuitive, at first, at least because it was more common and also more intuitive. The team was able to know how a willing model differs from the design systems we were familiar with by discovering two principles:

    1. Instead of design, content models may establish semantics.
    2. And glad models should connect elements that belong together.

    Lexical material models

    A conceptual content type uses form and attribute names that reflect the content’s intended purpose and not how it will be displayed. For instance, in a nonsemantic design, groups may make varieties like teasers, press blocks, and cards. Although these types may make it simple to present information, they don’t aid in understanding the meaning of the information, which would have opened the door to the information presented in each advertising channel. In comparison, a conceptual content type uses kind names like “product,”” service,” and “testimonial” to allow for each delivery channel to interpret and use the content as it sees fit.

    A great place to start when creating a conceptual content concept is by reviewing the types and qualities that Schema has defined. com, a community-driven tool for type meanings that are comprehensible to platforms like Google search.

    A semantic information model has many advantages:

      A semantic material type decouples information from its presentation but that teams can change the website’s design without having to restructure its content, even if your team doesn’t worry about omnichannel content. In this way, content can withstand disruptive website redesigns.
    • A semantic content model also gives you a competitive advantage. by including schema-based structured data. org’s types and properties, a website can provide hints to help Google understand the content, display it in search snippets or knowledge panels, and use it to answer voice-interface user questions. Without ever visiting your website, potential visitors could easily find your content.
    • Beyond those practical advantages, you’ll also require an omnichannel content delivery model. Delivery channels must be able to comprehend the same content in order to use it across multiple marketing channels. For instance, if your content model provided a list of questions and answers, it could be easily displayed on a frequently asked questions ( FAQ ) page as well, but it could also be used by a bot that answers frequently asked questions.

    For example, using a semantic content model for articles, events, people, and locations lets A List Apart provide cleanly structured data for search engines so that users can read the content on the website, in Google knowledge panels, and even with hypothetical voice interfaces in the future.

    Content models that connect

    Instead of slicing up related content across disparate content components, I’ve come to the realization that the best models are those that are semantic and also connect related content components ( such as a FAQ item’s question and answer pair ). Content that needs to be reused by multiple delivery channels can be connected to each other without having to assemble those pieces again in a good content model.

    Write an essay or article about it. An article’s meaning and usefulness depends upon its parts being kept together. Would one of the headings or paragraphs have any significance on their own if the entire article were not included? Our well-versed in designing systems frequently led us to want to develop content models that would break content into smaller pieces to fit the web-centric layout. Similar effects could have been felt to an article that had its headline removed. Because we were dividing content into separate pieces based on layout, content that belonged together became challenging to manage and nearly impossible for multiple delivery channels to comprehend.

    To illustrate, let’s look at how connecting related content applies in a real-world scenario. A complex layout for a software product page that included multiple tabs and sections was presented by the client’s design team. The content model lacked instincts, so we had to follow our instincts. Shouldn’t we make adding multiple tabs in the future as simple and flexible as possible?

    Because our design-system instincts were so well-known, it appeared that we needed a “tab section” content type so that multiple tab sections could be added to a page. Each tab section would display a variety of content. One tab might provide the software’s overview or its specifications. Another tab might provide a list of resources.

    Our tendency to divide the content model into “tab section” pieces would have resulted in a cumbersome editing process, as well as unnecessarily complex content that couldn’t have been digested by additional delivery channels. How would a different system have been able to determine which “tab section” referred to a product’s specifications or resource list, for instance? Would that system have had to have used tab sections and content blocks to calculate this? This would have prevented the tabs from ever being rearranged, and logic would have had to be added to each other delivery channel to interpret the layout of the design system. Additionally, it would have been difficult to migrate to a new content model in response to the new page redesign if the customer had decided against displaying this content in a tab layout.

    We had a breakthrough when we discovered that our customer had a specific purpose in mind for each tab: it would reveal specific information such as the software product’s overview, specifications, related resources, and pricing. When the design process began, our desire to concentrate on what was visually and historically significant had obscured the purpose of the designs. With a little digging, it didn’t take long to realize that the concept of tabs wasn’t relevant to the content model. What was important was the meaning of the content they were planning to display in the tabs.

    In fact, the customer could have chosen to switch to another format, using tabs, elsewhere. In response to this realization, we decided to create content types for the software product based on the meaningful qualities the client wanted to display on the web. There were obvious semantic attributes like name and description as well as rich attributes like screenshots, software requirements, and feature lists. The software’s product information stayed together because it wasn’t sliced across separate components like “tab sections” that were derived from the content’s presentation. Any delivery channel—including future ones—could understand and present this content.

    Conclusion

    In this omnichannel marketing project, we discovered that the best way to maintain the content model was to ensure that it was semantic ( with type and attribute names that reflected the content’s meaning ) and that it kept content together that belonged ( as opposed to separating it ). These two ideas made it easier for us to decide what to do with the content model based on the design. Remember: If you’re developing a content model to support an omnichannel content strategy, or even if you just want to make sure Google and other interfaces understand your content, keep in mind:

    • A design system isn’t a content model. You should maintain the semantic value and contextual structure of the content strategy throughout the entire implementation process because team members might be tempted to combine them and to make your content model resemble your design system. Without the use of a magic decoder ring, every delivery channel will be able to consume the content.
    • If your team is having trouble making this transition, Schema can still offer some of the advantages. org–based structured data in your website. The benefit of search engine optimization is a compelling reason on its own, even if additional delivery channels aren’t on the horizon in the near future.
    • Remind the team that removing the content model from the design will allow them to update the designs more quickly because content migration costs won’t be prohibitive. They will be prepared for the upcoming big thing, and they will be able to create new designs without compromising the compatibility between the content and the design.

    You’ll help your team understand these principles by firmly defending them in their efforts to give content the attention it deserves as both your most valuable resource and your most effective way to engage with your audience.

  • Design for Safety, An Excerpt

    Design for Safety, An Excerpt

    According to anti-racist scholar Kim Crayton, “intention without plan is chaos.” We’ve discussed how our prejudices, beliefs, and carelessness toward marginalized and resilient parties lead to dangerous and irresponsible tech—but what, precisely, do we need to do to fix it? We need a strategy, not just the desire to make our technical safer.

    This book will provide you with that plan of action. It covers how to incorporate safety concepts into your design work to create healthy tech, how to persuade your stakeholders that this work is required, and how to respond to criticism that what we really need is more variety. ( Spoiler: we do, but diversity alone is not the antidote to fixing unethical, unsafe tech. )

    The procedure for ensuring equitable protection

    When you are designing for protection, your goals are to:

    • detect the abuse potential of your product.
    • style ways to prevent the maltreatment, and
    • offer assistance for users who are prone to regain control and power.

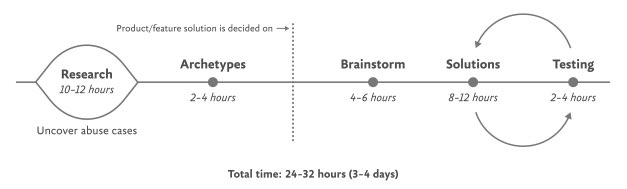
    The Process for Inclusive Safety is a tool to help you reach those goals ( Fig 5.1 ). It’s a method I developed in 2018 to better understand the different methods I used to create products that were designed with safety in mind. Whether you are creating an entirely new product or adding to an existing element, the Process can help you produce your product secure and diverse. Five main public areas of action are included in the Process:

    • Conducting study
    • Developing tropes
    • Pondering problems
    • creating answers
    • Testing for health

    The Process is meant to be flexible; in some situations, it didn’t make sense for groups to employ every step. Use the parts that are related to your special function and environment, this is meant to be something you can put into your existing style process.

    And once you use it, if you have suggestions for improving it or just want to give an overview of how it helped your staff, please get in touch with me. It’s a dwelling report that I hope will continue to be a helpful and practical tool that technicians can use in their day-to-day job.

    Be sure to study Chapter 7, which explicitly addresses the situation and should be handled a little different if you’re creating a product especially for a defenseless group or victims of some form of injury, such as an application for survivors of domestic violence, sexual abuse, or drug dependency. The guidelines below are for evaluating safety when designing a more basic product that will have a large customer base ( which, we now know from data, will include specific groups that should be protected from harm ). Chapter 7 concentrates on goods made especially for those who have been traumatized and are vulnerable.

    Step 1: Do study

    Design research should involve a thorough evaluation of how your technology might be used for abuse as well as particular insight into the experiences of those who have witnessed and perpetrated that kind of abuse. At this stage, you and your team will evaluate issues of social harm and abuse, and examine any other safety, security, or inclusivity issues that might be a concern for your product or service, like data security, prejudiced algorithms, and harassment.

    broad research

    Your project should begin with broad, general research into similar products and issues around safety and ethical concerns that have already been reported. For instance, a team building a smart home device would be wise to comprehend the many ways that already-existing smart home devices have been misused as abuse tools. If your product will involve AI, seek to understand the potentials for racism and other issues that have been reported in existing AI products. Nearly all different types of technology have some sort of potential or actual harm that has been covered in the media or written about by academics. Google Scholar is a useful tool for finding these studies.

    Survivors as a specific field of study

    When possible and appropriate, include direct research ( surveys and interviews ) with people who are experts in the forms of harm you have uncovered. In order to have a better understanding of the subject and be better positioned to prevent retraumatize survivors, you should interview advocates working in the area of your research first. If you’ve uncovered possible domestic violence issues, for example, the experts you’ll want to speak with are survivors themselves, as well as workers at domestic violence hotlines, shelters, other related nonprofits, and lawyers.

    It is crucial to pay people for their knowledge and lived experiences, especially when interviewing survivors of any kind of trauma. Don’t ask survivors to share their trauma for free, as this is exploitative. You should always make the offer in the beginning, even though some survivors might not want to be paid. An alternative to payment is to donate to an organization working against the type of violence that the interviewee experienced. In Chapter 6, we’ll discuss more about how to appropriately interview survivors.

    Specific research: Abusers

    It’s unlikely that safety-focused projects will be able to interview self-declared abusers or those who have broken laws in areas like hacking. Don’t make this a goal, rather, try to get at this angle in your general research. Attempt to understand how abusers or bad actors use technology to harm others, how they use it against others, and how they justify or explain the abuse.

    Step 2: Create archetypes

    Use your research’s findings to create the archetypes of abuser and survivor once you’ve finished your research. Archetypes are not personas, as they’re not based on real people that you interviewed and surveyed. They are based on your investigation into potential safety problems, much like when we design for accessibility: we don’t need to have identified any blind or deaf people in our interview pool to come up with a design that is representative of them. Instead, we base those designs on existing research into what this group needs. While archetypes are broad and can be more generalized, real users typically represent real users and contain many details.

    The abuser archetype is someone who will look at the product as a tool to perform harm ( Fig 5.2 ). They may be attempting to harm someone they don’t know by using surveillance or anonymous harassment, or they may be trying to control, monitor, abuse, or otherwise torment someone they know.

    The survivor archetype refers to a person who is being abused with the product. There are various situations to consider in terms of the archetype’s understanding of the abuse and how to put an end to it: Do they need proof of abuse they already suspect is happening, or are they unaware they’ve been targeted in the first place and need to be alerted ( Fig 5.3 )?

    To capture a range of different experiences, you might want to create multiple survivor archetypes. They may know that the abuse is happening but not be able to stop it, like when an abuser locks them out of IoT devices, or they know it’s happening but don’t know how, such as when a stalker keeps figuring out their location ( Fig 5.4). Include as many of these scenarios in your survivor archetype as you need. You’ll use these later on when you design solutions to help your survivor archetypes achieve their goals of preventing and ending abuse.

    It may be useful for you to create persona-like artifacts for your archetypes, such as the three examples shown. Focus on their objectives rather than the demographic information we frequently see in personas. The goals of the abuser will be to carry out the specific abuse you’ve identified, while the goals of the survivor will be to prevent abuse, understand that abuse is happening, make ongoing abuse stop, or regain control over the technology that’s being used for abuse. Later, you’ll think about how to help the survivor’s goals and the abuser’s goals.

    And while the “abuser/survivor” model fits most cases, it doesn’t fit all, so modify it as you need to. For instance, if you found a security flaw, such as the ability for someone to talk to children through a home camera system, the malicious hacker would receive the abuser archetype, and the child’s parents would receive the survivor archetype.

    Step 3: Brainstorm problems

    Brainstorm novel abuse cases and safety issues after creating archetypes. ” Novel” means things not found in your research, you’re trying to identify completely new safety issues that are unique to your product or service. The purpose of this step is to exhaust every effort put forth to find potential problems that your product might cause. You aren’t worrying about how to prevent the harm yet—that comes in the next step.

    What other abuses could your product be used for besides what you’ve already discovered through your research? I recommend setting aside at least a few hours with your team for this process.

    Try conducting a Black Mirror brainstorming session if you want to start somewhere. This exercise is based on the show Black Mirror, which features stories about the dark possibilities of technology. Try to figure out the most outrageous, horrible, and out-of-control ways your product could harm you in a show episode. When I’ve led Black Mirror brainstorms, participants usually end up having a good deal of fun ( which I think is great—it’s okay to have fun when designing for safety! ). I suggest time-boxing a Black Mirror brainstorm for the first half an hour, then dialing back, and using the remaining time to consider more plausible forms of harm.

    After you’ve identified as many opportunities for abuse as possible, you may still not feel confident that you’ve uncovered every potential form of harm. When you’re doing this kind of work, a healthy amount of anxiety is normal. It’s common for teams designing for safety to worry,” Have we really identified every possible harm? What if something is missing, then? If you’ve spent at least four hours coming up with ways your product could be used for harm and have run out of ideas, go to the next step.

    It’s impossible to say 100 % assurance that you’ve done everything, but instead of aiming for 100 %, acknowledge that you’ve done it and will continue to prioritize safety in the future. Once your product is released, your users may identify new issues that you missed, aim to receive that feedback graciously and course-correct quickly.

    4. Create solutions

    At this point, you should have a list of ways your product can be used for harm as well as survivor and abuser archetypes describing opposing user goals. Next, it’s time to figure out how to design in accordance with the objectives of the identified abuser and the objectives of the survivor. This step is a good one to insert alongside existing parts of your design process where you’re proposing solutions for the various problems your research uncovered.

    Questions to ask yourself include: What are some ways to protect your archetypes and to support your self-identity?

    • Can you design your product in such a way that the identified harm cannot happen in the first place? If not, what barriers can you place to stop the harm from occurring?
    • How can you make the victim aware that abuse is happening through your product?
    • How can you assist the victim in understanding what they need to do to stop the problem?
    • Can you identify any types of user activity that would indicate some form of harm or abuse? Could your product provide support for the user?

    In some products, it’s possible to proactively recognize that harm is happening. For instance, a pregnancy app might be modified to allow users to report that they were the victims of an assault, which could result in an offer to receive resources for local and national organizations. This sort of proactiveness is not always possible, but it’s worth taking a half hour to discuss if any type of user activity would indicate some form of harm or abuse, and how your product could assist the user in receiving help in a safe manner.

    Nonetheless, be careful when doing anything that could harm a user if their devices are being monitored. If you do offer some kind of proactive help, always make it voluntary, and think through other safety issues, such as the need to keep the user in-app in case an abuser is checking their search history. In the next chapter, we’ll examine a good illustration of this.

    Step 5: Test for safety

    The final step is to evaluate the prototypes against the perspectives of your archetypes, who wants to harm the product or the victim of the harm who needs to regain control of the technology. Just like any other kind of product testing, at this point you’ll aim to rigorously test out your safety solutions so that you can identify gaps and correct them, validate that your designs will help keep your users safe, and feel more confident releasing your product into the world.

    Safety testing should be performed in addition to usability testing. If you’re at a company that doesn’t do usability testing, you might be able to use safety testing to cleverly perform both, a user who goes through your design attempting to weaponize the product against someone else can also be encouraged to point out interactions or other elements of the design that don’t make sense to them.

    If your final prototype or the finished product has already been released, you’ll want to conduct safety testing on both. There’s nothing wrong with testing an existing product that wasn’t designed with safety goals in mind from the onset —”retrofitting” it for safety is a good thing to do.

    Keep in mind that testing for safety involves both an abuser and a survivor’s perspective, even though it might not make sense for you to do both. Alternatively, if you made multiple survivor archetypes to capture multiple scenarios, you’ll want to test from the perspective of each one.

    You as the designer are most likely too closely connected to the product and its design by this point to be a valuable tester, you know the product too well, as with other forms of usability testing. Instead of doing it yourself, set up testing as you would with other usability testing: find someone who is not familiar with the product and its design, set the scene, give them a task, encourage them to think out loud, and observe how they attempt to complete it.

    testing for abuse

    The goal of this testing is to understand how easy it is for someone to weaponize your product for harm. You want to make it impossible, or at least difficult, for them to accomplish their goal, in contrast to usability testing. Reference the goals in the abuser archetype you created earlier, and use your product in an attempt to achieve them.

    For instance, we can imagine that the abuser archetype would have the goal of determining the location of his ex-girlfriend right now in a fitness app with GPS-enabled location features. With this goal in mind, you’d try everything possible to figure out the location of another user who has their privacy settings enabled. You might try to follow her running routes, view any information she has on her profile, view any information she has made private, and check out the profiles of any other users who are somehow connected to her account, such as her followers.

    If by the end of this you’ve managed to uncover some of her location data, despite her having set her profile to private, you know now that your product enables stalking. Reverting to step 4 and figuring out how to stop this from occurring is your next step. You may need to repeat the process of designing solutions and testing them more than once.

    testing for a Survivor

    testing for a Survivor involves identifying how to give information and power to the survivor. It might not always make sense based on the product or context. Thwarting the attempt of an abuser archetype to stalk someone also satisfies the goal of the survivor archetype to not be stalked, so separate testing wouldn’t be needed from the survivor’s perspective.

    However, there are instances where it makes sense. For example, for a smart thermostat, a survivor archetype’s goals would be to understand who or what is making the temperature change when they aren’t doing it themselves. If you couldn’t find the information in step 4, you would need to perform more work in step 4. You could test this by looking for the thermostat’s history log and looking for usernames, actions, and times.

    Another goal might be regaining control of the thermostat once the survivor realizes the abuser is remotely changing its settings. Your test would involve trying to figure out how to do this: are there instructions on how to remove and change the password, and are they simple to locate? This might again reveal that more work is needed to make it clear to the user how they can regain control of the device or account.

    stress testing

    To make your product more inclusive and compassionate, consider adding stress testing. Eric Meyer and Sara Wachter-Boettcher’s Design for Real Life inspired this idea. The authors pointed out that personas typically center people who are having a good day—but real users are often anxious, stressed out, having a bad day, or even experiencing tragedy. These are known as” stress cases,” and testing your products for users in stress-case scenarios can reveal areas where your design lacks compassion. Design for Real Life has more details about what it looks like to incorporate stress cases into your design as well as many other great tactics for compassionate design.

  • How to Sell UX Research with Two Simple Questions

    How to Sell UX Research with Two Simple Questions

    Do you find yourself designing screens with only a vague idea of how the things on the screen relate to the things elsewhere in the system? Do you leave stakeholder meetings with unclear directives that often seem to contradict previous conversations? You know a better understanding of user needs would help the team get clear on what you are actually trying to accomplish, but time and budget for research is tight. When it comes to asking for more direct contact with your users, you might feel like poor Oliver Twist, timidly asking, “Please, sir, I want some more.” 

    Here’s the trick. You need to get stakeholders themselves to identify high-risk assumptions and hidden complexity, so that they become just as motivated as you to get answers from users. Basically, you need to make them think it’s their idea. 

    In this article, I’ll show you how to collaboratively expose misalignment and gaps in the team’s shared understanding by bringing the team together around two simple questions:

    1. What are the objects?
    2. What are the relationships between those objects?

    A gauntlet between research and screen design

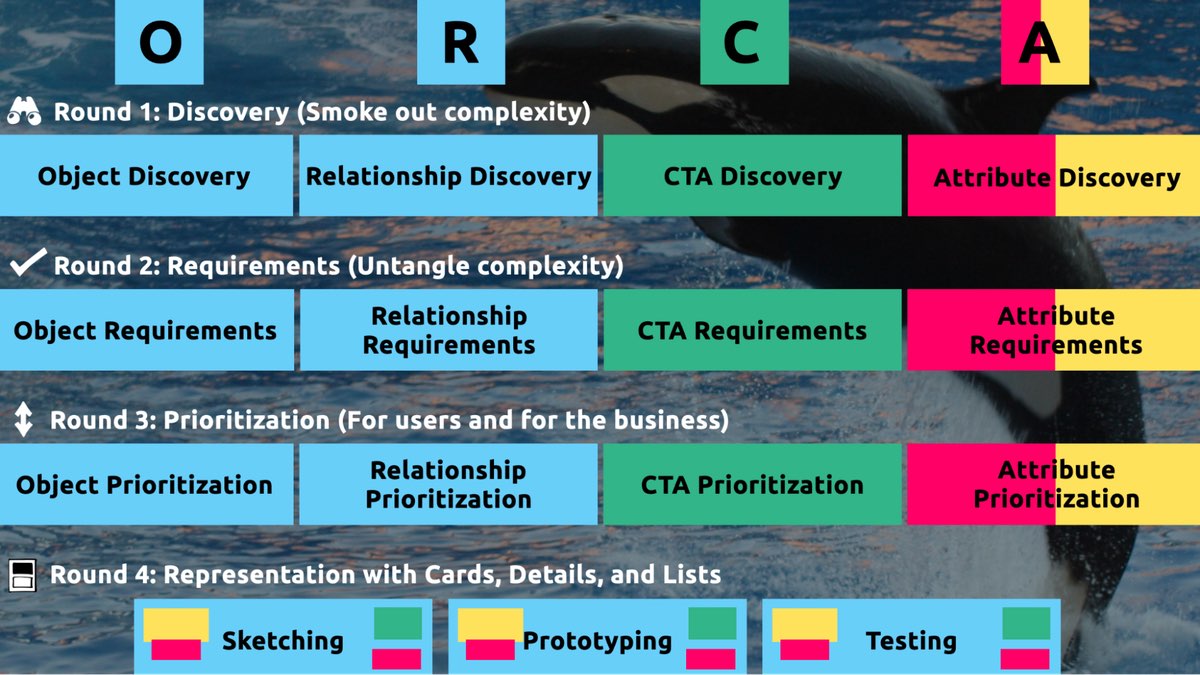
    These two questions align to the first two steps of the ORCA process, which might become your new best friend when it comes to reducing guesswork. Wait, what’s ORCA?! Glad you asked.

    ORCA stands for Objects, Relationships, CTAs, and Attributes, and it outlines a process for creating solid object-oriented user experiences. Object-oriented UX is my design philosophy. ORCA is an iterative methodology for synthesizing user research into an elegant structural foundation to support screen and interaction design. OOUX and ORCA have made my work as a UX designer more collaborative, effective, efficient, fun, strategic, and meaningful.

    The ORCA process has four iterative rounds and a whopping fifteen steps. In each round we get more clarity on our Os, Rs, Cs, and As.

    I sometimes say that ORCA is a “garbage in, garbage out” process. To ensure that the testable prototype produced in the final round actually tests well, the process needs to be fed by good research. But if you don’t have a ton of research, the beginning of the ORCA process serves another purpose: it helps you sell the need for research.

    In other words, the ORCA process serves as a gauntlet between research and design. With good research, you can gracefully ride the killer whale from research into design. But without good research, the process effectively spits you back into research and with a cache of specific open questions.

    Getting in the same curiosity-boat

    What gets us into trouble is not what we don’t know. It’s what we know for sure that just ain’t so.

    Mark Twain

    The first two steps of the ORCA process—Object Discovery and Relationship Discovery—shine a spotlight on the dark, dusty corners of your team’s misalignments and any inherent complexity that’s been swept under the rug. It begins to expose what this classic comic so beautifully illustrates:

    This is one reason why so many UX designers are frustrated in their job and why many projects fail. And this is also why we often can’t sell research: every decision-maker is confident in their own mental picture. 

    Once we expose hidden fuzzy patches in each picture and the differences between them all, the case for user research makes itself.

    But how we do this is important. However much we might want to, we can’t just tell everyone, “YOU ARE WRONG!” Instead, we need to facilitate and guide our team members to self-identify holes in their picture. When stakeholders take ownership of assumptions and gaps in understanding, BAM! Suddenly, UX research is not such a hard sell, and everyone is aboard the same curiosity-boat.

    Say your users are doctors. And you have no idea how doctors use the system you are tasked with redesigning.

    You might try to sell research by honestly saying: “We need to understand doctors better! What are their pain points? How do they use the current app?” But here’s the problem with that. Those questions are vague, and the answers to them don’t feel acutely actionable.

    Instead, you want your stakeholders themselves to ask super-specific questions. This is more like the kind of conversation you need to facilitate. Let’s listen in:

    “Wait a sec, how often do doctors share patients? Does a patient in this system have primary and secondary doctors?”

    “Can a patient even have more than one primary doctor?”

    “Is it a ‘primary doctor’ or just a ‘primary caregiver’… Can’t that role be a nurse practitioner?”

    “No, caregivers are something else… That’s the patient’s family contacts, right?”

    “So are caregivers in scope for this redesign?”

    “Yeah, because if a caregiver is present at an appointment, the doctor needs to note that. Like, tag the caregiver on the note… Or on the appointment?”

    Now we are getting somewhere. Do you see how powerful it can be getting stakeholders to debate these questions themselves? The diabolical goal here is to shake their confidence—gently and diplomatically.

    When these kinds of questions bubble up collaboratively and come directly from the mouths of your stakeholders and decision-makers, suddenly, designing screens without knowing the answers to these questions seems incredibly risky, even silly.

    If we create software without understanding the real-world information environment of our users, we will likely create software that does not align to the real-world information environment of our users. And this will, hands down, result in a more confusing, more complex, and less intuitive software product.

    The two questions

    But how do we get to these kinds of meaty questions diplomatically, efficiently, collaboratively, and reliably

    We can do this by starting with those two big questions that align to the first two steps of the ORCA process:

    1. What are the objects?
    2. What are the relationships between those objects?

    In practice, getting to these answers is easier said than done. I’m going to show you how these two simple questions can provide the outline for an Object Definition Workshop. During this workshop, these “seed” questions will blossom into dozens of specific questions and shine a spotlight on the need for more user research.

    Prep work: Noun foraging

    In the next section, I’ll show you how to run an Object Definition Workshop with your stakeholders (and entire cross-functional team, hopefully). But first, you need to do some prep work.

    Basically, look for nouns that are particular to the business or industry of your project, and do it across at least a few sources. I call this noun foraging.

    Here are just a few great noun foraging sources:

    • the product’s marketing site
    • the product’s competitors’ marketing sites (competitive analysis, anyone?)
    • the existing product (look at labels!)
    • user interview transcripts
    • notes from stakeholder interviews or vision docs from stakeholders

    Put your detective hat on, my dear Watson. Get resourceful and leverage what you have. If all you have is a marketing website, some screenshots of the existing legacy system, and access to customer service chat logs, then use those.

    As you peruse these sources, watch for the nouns that are used over and over again, and start listing them (preferably on blue sticky notes if you’ll be creating an object map later!).

    You’ll want to focus on nouns that might represent objects in your system. If you are having trouble determining if a noun might be object-worthy, remember the acronym SIP and test for:

    1. Structure
    2. Instances
    3. Purpose

    Think of a library app, for example. Is “book” an object?

    Structure: can you think of a few attributes for this potential object? Title, author, publish date… Yep, it has structure. Check!

    Instance: what are some examples of this potential “book” object? Can you name a few? The Alchemist, Ready Player One, Everybody Poops… OK, check!

    Purpose: why is this object important to the users and business? Well, “book” is what our library client is providing to people and books are why people come to the library… Check, check, check!

    As you are noun foraging, focus on capturing the nouns that have SIP. Avoid capturing components like dropdowns, checkboxes, and calendar pickers—your UX system is not your design system! Components are just the packaging for objects—they are a means to an end. No one is coming to your digital place to play with your dropdown! They are coming for the VALUABLE THINGS and what they can do with them. Those things, or objects, are what we are trying to identify.

    Let’s say we work for a startup disrupting the email experience. This is how I’d start my noun foraging.

    First I’d look at my own email client, which happens to be Gmail. I’d then look at Outlook and the new HEY email. I’d look at Yahoo, Hotmail…I’d even look at Slack and Basecamp and other so-called “email replacers.” I’d read some articles, reviews, and forum threads where people are complaining about email. While doing all this, I would look for and write down the nouns.

    (Before moving on, feel free to go noun foraging for this hypothetical product, too, and then scroll down to see how much our lists match up. Just don’t get lost in your own emails! Come back to me!)

    Drumroll, please…

    Here are a few nouns I came up with during my noun foraging:

    • email message
    • thread
    • contact
    • client
    • rule/automation
    • email address that is not a contact?
    • contact groups
    • attachment
    • Google doc file / other integrated file
    • newsletter? (HEY treats this differently)
    • saved responses and templates

    Scan your list of nouns and pick out words that you are completely clueless about. In our email example, it might be client or automation. Do as much homework as you can before your session with stakeholders: google what’s googleable. But other terms might be so specific to the product or domain that you need to have a conversation about them.

    Aside: here are some real nouns foraged during my own past project work that I needed my stakeholders to help me understand:

    • Record Locator
    • Incentive Home
    • Augmented Line Item
    • Curriculum-Based Measurement Probe

    This is really all you need to prepare for the workshop session: a list of nouns that represent potential objects and a short list of nouns that need to be defined further.

    Facilitate an Object Definition Workshop

    You could actually start your workshop with noun foraging—this activity can be done collaboratively. If you have five people in the room, pick five sources, assign one to every person, and give everyone ten minutes to find the objects within their source. When the time’s up, come together and find the overlap. Affinity mapping is your friend here!

    If your team is short on time and might be reluctant to do this kind of grunt work (which is usually the case) do your own noun foraging beforehand, but be prepared to show your work. I love presenting screenshots of documents and screens with all the nouns already highlighted. Bring the artifacts of your process, and start the workshop with a five-minute overview of your noun foraging journey.

    HOT TIP: before jumping into the workshop, frame the conversation as a requirements-gathering session to help you better understand the scope and details of the system. You don’t need to let them know that you’re looking for gaps in the team’s understanding so that you can prove the need for more user research—that will be our little secret. Instead, go into the session optimistically, as if your knowledgeable stakeholders and PMs and biz folks already have all the answers. 

    Then, let the question whack-a-mole commence.

    1. What is this thing?

    Want to have some real fun? At the beginning of your session, ask stakeholders to privately write definitions for the handful of obscure nouns you might be uncertain about. Then, have everyone show their cards at the same time and see if you get different definitions (you will). This is gold for exposing misalignment and starting great conversations.

    As your discussion unfolds, capture any agreed-upon definitions. And when uncertainty emerges, quietly (but visibly) start an “open questions” parking lot. 😉

    After definitions solidify, here’s a great follow-up:

    2. Do our users know what these things are? What do users call this thing?

    Stakeholder 1: They probably call email clients “apps.” But I’m not sure.

    Stakeholder 2: Automations are often called “workflows,” I think. Or, maybe users think workflows are something different.

    If a more user-friendly term emerges, ask the group if they can agree to use only that term moving forward. This way, the team can better align to the users’ language and mindset.

    OK, moving on. 

    If you have two or more objects that seem to overlap in purpose, ask one of these questions:

    3. Are these the same thing? Or are these different? If they are not the same, how are they different?

    You: Is a saved response the same as a template?

    Stakeholder 1: Yes! Definitely.

    Stakeholder 2: I don’t think so… A saved response is text with links and variables, but a template is more about the look and feel, like default fonts, colors, and placeholder images. 

    Continue to build out your growing glossary of objects. And continue to capture areas of uncertainty in your “open questions” parking lot.

    If you successfully determine that two similar things are, in fact, different, here’s your next follow-up question:

    4. What’s the relationship between these objects?

    You: Are saved responses and templates related in any way?

    Stakeholder 3:  Yeah, a template can be applied to a saved response.

    You, always with the follow-ups: When is the template applied to a saved response? Does that happen when the user is constructing the saved response? Or when they apply the saved response to an email? How does that actually work?

    Listen. Capture uncertainty. Once the list of “open questions” grows to a critical mass, pause to start assigning questions to groups or individuals. Some questions might be for the dev team (hopefully at least one developer is in the room with you). One question might be specifically for someone who couldn’t make it to the workshop. And many questions will need to be labeled “user.” 

    Do you see how we are building up to our UXR sales pitch?

    5. Is this object in scope?

    Your next question narrows the team’s focus toward what’s most important to your users. You can simply ask, “Are saved responses in scope for our first release?,” but I’ve got a better, more devious strategy.

    By now, you should have a list of clearly defined objects. Ask participants to sort these objects from most to least important, either in small breakout groups or individually. Then, like you did with the definitions, have everyone reveal their sort order at once. Surprisingly—or not so surprisingly—it’s not unusual for the VP to rank something like “saved responses” as #2 while everyone else puts it at the bottom of the list. Try not to look too smug as you inevitably expose more misalignment.

    I did this for a startup a few years ago. We posted the three groups’ wildly different sort orders on the whiteboard.

    The CEO stood back, looked at it, and said, “This is why we haven’t been able to move forward in two years.”

    Admittedly, it’s tragic to hear that, but as a professional, it feels pretty awesome to be the one who facilitated a watershed realization.

    Once you have a good idea of in-scope, clearly defined things, this is when you move on to doing more relationship mapping.

    6. Create a visual representation of the objects’ relationships

    We’ve already done a bit of this while trying to determine if two things are different, but this time, ask the team about every potential relationship. For each object, ask how it relates to all the other objects. In what ways are the objects connected? To visualize all the connections, pull out your trusty boxes-and-arrows technique. Here, we are connecting our objects with verbs. I like to keep my verbs to simple “has a” and “has many” statements.

    This system modeling activity brings up all sorts of new questions:

    • Can a saved response have attachments?
    • Can a saved response use a template? If so, if an email uses a saved response with a template, can the user override that template?
    • Do users want to see all the emails they sent that included a particular attachment? For example, “show me all the emails I sent with ProfessionalImage.jpg attached. I’ve changed my professional photo and I want to alert everyone to update it.” 

    Solid answers might emerge directly from the workshop participants. Great! Capture that new shared understanding. But when uncertainty surfaces, continue to add questions to your growing parking lot.

    Light the fuse

    You’ve positioned the explosives all along the floodgates. Now you simply have to light the fuse and BOOM. Watch the buy-in for user research flooooow.

    Before your workshop wraps up, have the group reflect on the list of open questions. Make plans for getting answers internally, then focus on the questions that need to be brought before users.

    Here’s your final step. Take those questions you’ve compiled for user research and discuss the level of risk associated with NOT answering them. Ask, “if we design without an answer to this question, if we make up our own answer and we are wrong, how bad might that turn out?” 

    With this methodology, we are cornering our decision-makers into advocating for user research as they themselves label questions as high-risk. Sorry, not sorry. 

    Now is your moment of truth. With everyone in the room, ask for a reasonable budget of time and money to conduct 6–8 user interviews focused specifically on these questions. 

    HOT TIP: if you are new to UX research, please note that you’ll likely need to rephrase the questions that came up during the workshop before you present them to users. Make sure your questions are open-ended and don’t lead the user into any default answers.

    Final words: Hold the screen design!

    Seriously, if at all possible, do not ever design screens again without first answering these fundamental questions: what are the objects and how do they relate?

    I promise you this: if you can secure a shared understanding between the business, design, and development teams before you start designing screens, you will have less heartache and save more time and money, and (it almost feels like a bonus at this point!) users will be more receptive to what you put out into the world. 

    I sincerely hope this helps you win time and budget to go talk to your users and gain clarity on what you are designing before you start building screens. If you find success using noun foraging and the Object Definition Workshop, there’s more where that came from in the rest of the ORCA process, which will help prevent even more late-in-the-game scope tugs-of-war and strategy pivots. 

    All the best of luck! Now go sell research!

  • Breaking Out of the Box

    Breaking Out of the Box

    CSS is all about styling containers. In fact, the whole website is made of containers, from the website viewport to components on a webpage. However, there are times when we have a fresh element that forces us to reevaluate our design strategy.

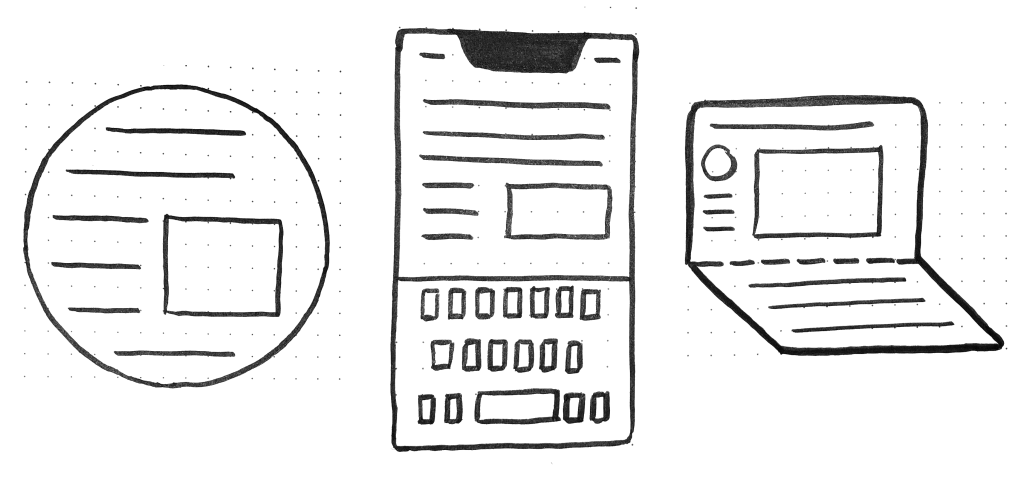
    Square features, for instance, make it fun to play with round picture areas. Mobile screen notches and electronic keyboards present difficulties in how to best manage content that stays out of reach. And two display or portable devices make us reassess how to best utilize available space in a number of various device postures.

    These new evolutions of the internet system made it both more demanding and more exciting to design products. We have a lot of options to leave our triangular containers.

    I’d like to talk about a new feature similar to the above: the Window Controls Overlay for Progressive Web Apps ( PWAs ).

    Democratic Web Apps are bridging the gap between websites and apps. They combine the best of both worlds. On the one hand, they’re flexible, linkable, and stable, just like sites. On the other hand, they provide more effective features, work online, and read documents just like local apps.

    PWAs are really exciting as a style area because they challenge us to consider how to combine online and native user interface. On desktop products in certain, we have more than 40 years of history telling us what software may look like, and it can be hard to break out of this mental concept.

    PWAs on desktop are ultimately limited to the top of a rectangle with a title bar.

    Here’s what a typical desktop PWA app looks like:

    Sure, as the author of a PWA, you get to choose the color of the title bar (using the Web Application Manifest theme_color property ), but that’s about it.

    What if we could look beyond this box and reclaim the entire window of the app? Doing so would give us a chance to make our apps more beautiful and feel more integrated in the operating system.

    The Window Controls Overlay offers exactly this. This new PWA functionality makes it possible to take advantage of the full surface area of the app, including where the title bar normally appears.

    About the window and title bar controls

    Let’s start with an explanation of what the title bar and window controls are.

    The title bar is the window at the top of an app that typically contains the app’s name. Window controls are the affordances, or buttons, that make it possible to minimize, maximize, or close the app’s window, and are also displayed at the top.

    Window Controls Overlay removes the physical constraint of the title bar and window controls areas. The title bar and window control buttons can be overlayed on top of the application’s web content, allowing it to free up the entire height of the app window.

    If you are reading this article on a desktop computer, take a quick look at other apps. They’re probably already doing something similar. In fact, the very web browser you are using to read this uses the top area to display tabs.

    Spotify displays album artwork all the way to the top edge of the application window.

    Microsoft Word uses the available title bar space to display the auto-save and search functionalities, and more.

    The purpose of this feature is to give you the ability to use this space with your own content while also giving a way to take account of the window control buttons. And it enables you to offer this modified experience on a range of platforms while not adversely affecting the experience on browsers or devices that don’t support Window Controls Overlay. PWAs are all about progressive enhancement, so this feature is a chance to make your app use this extra space when it’s available.

    Let’s use the feature

    We’ll be creating a demo app for the remainder of this article to learn more about how to use the feature.

    The demo app is called 1DIV. Users can create designs using CSS and a single HTML element in a simple CSS playground.

    The app has two pages. The first lists the CSS designs you’ve already created:

    The second page enables the creation and editing of CSS designs:

    Since I’ve added a simple web manifest and service worker, we can install the app as a PWA on desktop. What it appears to be on macOS is shown below:

    And on Windows:

    The first page’s white title bar is a waste of space, despite our app’s attractive design. In the second page, it would be really nice if the design area went all the way to the top of the app window.

    To enhance this, let’s use the Window Controls Overlay feature.

    Enabling Window Controls Overlay

    The film is still in its experimental phase right now. To try it, you need to enable it in one of the supported browsers.

    It has currently been implemented in Chromium as a result of a collaboration between Microsoft and Google. We can therefore use it in Chrome or Edge by going to the internal about: //flags page, and enabling the Desktop PWA Window Controls Overlay flag.

    Using the overlay of Window Controls

    To use the feature, we need to add the following display_override member to our web app’s manifest file:

    { "name": "1DIV", "description": "1DIV is a mini CSS playground", "lang": "en-US", "start_url": "/", "theme_color": "#ffffff", "background_color": "#ffffff", "display_override": [ "window-controls-overlay" ], "icons": [ ... ]}

    The feature appears to be very simple to use. This manifest change is the only thing we need to make the title bar disappear and turn the window controls into an overlay.

    We’ll need some CSS and JavaScript code to make the most of the title bar area in our design and ensure that all users have a great experience regardless of device or browser.

    Here is what the app looks like now:

    Our logo, search field, and NEW button are now partially obscured by the window controls because our layout now begins at the top of the window, which is what we wanted.

    It’s similar on Windows, with the difference that the close, maximize, and minimize buttons appear on the right side, grouped together with the PWA control buttons:

    Screenshot of the Windows operating system’s Window Controls Overlay-enabled 1DIV app thumbnail display. The separate top bar area is gone, but the window controls are now blocking some of the app’s content.

    CSS to stay away from window controls

    Along with the feature, new CSS environment variables have been introduced:

    • titlebar-area-x
    • titlebar-area-y
    • titlebar-area-width
    • titlebar-area-height

    You can position your content where the title bar would have been by using these variables with the CSS env function to prevent it from overlapping with the window controls. In our case, we’ll use two of the variables to position our header, which contains the logo, search bar, and NEW button.

    header { position: absolute; left: env(titlebar-area-x, 0); width: env(titlebar-area-width, 100%); height: var(--toolbar-height);}

    The titlebar-area-x variable gives us the distance from the left of the viewport to where the title bar would appear, and titlebar-area-width is its width. (Remember, this is not equivalent to the width of the entire viewport, just the title bar portion, which as noted earlier, doesn’t include the window controls.)

    By doing this, we make sure our content remains fully visible. We’re also defining fallback values (the second parameter in the env() function) for when the variables are not defined (such as on non-supporting browsers, or when the Windows Control Overlay feature is disabled).

    Our header now adapts to its surroundings, and it doesn’t seem like the window control buttons were left out. The app looks a lot more like a native app.

    Changing the window controls the background color so that it blends in

    Now let’s take a closer look at our second page: the CSS playground editor.

    Not very good. Our CSS demo area does go all the way to the top, which is what we wanted, but the way the window controls appear as white rectangles on top of it is quite jarring.

    We can change the theme color of the app to fix this. There are a couple of ways to define it:

      PWAs can use the theme_color manifest member to define a theme color in the web app manifest file. This color is then used by the OS in different ways. It serves as a background color for the title bar and window controls on desktop computers.
    • Websites can use the theme-color meta tag as well. It’s used by browsers to customize the color of the UI around the web page. For PWAs, this color can override the manifest theme_color.

    In our case, we can set the manifest theme_color to white to provide the right default color for our app. The OS will read this color value when the app is installed and use it to make the window controls background color white. This color works great for our main page with the list of demos.

    The theme-color meta tag can be changed at runtime, using JavaScript. So we can do that to override the white with the right demo background color when one is opened.

    Here is the function we’ll use:

    function themeWindow(bgColor) { document.querySelector("meta[name=theme-color]").setAttribute('content', bgColor);}

    With this in place, we can envision how using color and CSS transitions can smooth transition from the list page to the demo page and make the window control buttons blend in with the rest of the app’s interface.

    Dragging the window

    Now, getting rid of the title bar entirely does have an important accessibility consequence: it’s much more difficult to move the application window around.

    Users can use the Window Controls Overlay feature to move the window, but this area becomes limited to where the control buttons are, and they must carefully aim between these buttons to move the window. However, the title bar offers a sizable area for users to click and drag.

    Fortunately, this can be fixed using CSS with the app-region property. This property is, for now, only supported in Chromium-based browsers and needs the -webkit- vendor prefix. 

    To make any element of the app become a dragging target for the window, we can use the following:

    -webkit-app-region: drag;

    Additionally, it is possible to expressly make an element non-draggable:

    -webkit-app-region: no-drag; 

    These options can be useful for us. We can make the entire header a dragging target while also making the NEW button and search field non-draggable so they can still be used as normal.

    However, because the editor page doesn’t display the header, users wouldn’t be able to drag the window while editing code. Let’s take a different strategy, then. We’ll create another element before our header, also absolutely positioned, and dedicated to dragging the window.

    ...
    .drag { position: absolute; top: 0; width: 100%; height: env(titlebar-area-height, 0); -webkit-app-region: drag;}

    With the above code, we’re making the draggable area span the entire viewport width, and using the titlebar-area-height variable to make it as tall as what the title bar would have been. This way, our draggable area is aligned with the window control buttons as shown below.

    And now, to ensure that our search box and button are usable:

    header .search,header .new { -webkit-app-region: no-drag;}

    With the above code, users can click and drag where the title bar used to be. Users are expecting to be able to move windows on their desktops, and we are not violating this expectation, which is good.

    adapting to window resizing

    It may be useful for an app to know both whether the window controls overlay is visible and when its size changes. The search field, logo, and button would need to be pushed down a little bit if the user made the window very narrow.

    The Window Controls Overlay feature comes with a JavaScript API we can use to do this: navigator.windowControlsOverlay.

    Three intriguing things are provided by the API:

    • navigator.windowControlsOverlay.visiblelets us know whether the overlay is visible.
    • navigator.windowControlsOverlay.getBoundingClientRect()lets us know where the title bar’s area is located and how big it is.
    • navigator.windowControlsOverlay.ongeometrychangelets us know when the size or visibility changes.

    Let’s use this to illustrate how large the title bar area is, and move the header down if it’s too small.

    if (navigator.windowControlsOverlay) { navigator.windowControlsOverlay.addEventListener('geometrychange', () => { const { width } = navigator.windowControlsOverlay.getBoundingClientRect(); document.body.classList.toggle('narrow', width < 250); });}

    In the example above, we set the narrow class on the body of the app if the title bar area is narrower than 250px. We could do something similar with a media query, but using the windowControlsOverlay API has two advantages for our use case:

    • It’s only fired when the feature is supported and used, we don’t want to adapt the design otherwise.
    • The title bar area is different for different operating systems, which is great because Mac and Windows have different title bar sizes. Using a media query wouldn’t make it possible for us to know exactly how much space remains.
    .narrow header { top: env(titlebar-area-height, 0); left: 0; width: 100%;}

    When the window is too small, we can use the above CSS code to move our header down and the thumbnails down in accordance with this.

    Thirty pixel of creative challenge


    Using the Window Controls Overlay feature, we were able to take our simple demo app and turn it into something that feels so much more integrated on desktop devices. Something that transcends the traditional window restrictions and offers its users a personalized experience.

    In reality, this feature only gives us about 30 pixels of extra room and comes with challenges on how to deal with the window controls. However, these additional space and those difficulties can be used as creative design opportunities.

    More devices of all shapes and forms get invented all the time, and the web keeps on evolving to adapt to them. To make it easier for us, web authors, to integrate more and more deeply with those devices, new features are added to the web platform. From watches or foldable devices to desktop computers, we need to evolve our design approach for the web. Nowadays, web building enables us to think outside the rectangular box.

    So let’s embrace this. Use the common technologies at our disposal and experiment with new concepts to create personalized experiences for all devices, all using a single codebase!


    If you get a chance to try the Window Controls Overlay feature and have feedback about it, you can open issues on the spec’s repository. You can help improve this feature’s development, which is still in its early stages. Or, you can take a look at the feature’s existing documentation, or this demo app and its source code.

  • Designers, (Re)define Success First

    Designers, (Re)define Success First

    I introduced the concept of normal social style about two and a half years earlier. It was born out of my disappointment with the many obstacles to achieving style that’s accessible and equal, protects people’s protection, firm, and target, benefits society, and restores nature. I argued that we must overcome the difficulties that prevent us from acting morally and that we must architecturally integrate design ethics into our daily routine, procedures, and tools to raise it to a more realistic level.

    However, we’re still very far from this best.

    At the time, I didn’t realize yet how to functionally combine morality. Yes, I had found some tools that had worked for me in past projects, such as using checklists, notion monitoring, and “dark truth” sessions, but I didn’t manage to use those in every task. I was still battling for time and support, and at best I had only partially surpassed my goal of having a higher ( moral ) level of design, which is not what I would consider to be structurally integrated.

    I made a deeper investigation into the main causes of business that prevent us from practicing regular honest style. Today, after much research and experimentation, I believe that I’ve found the code that will let us functionally combine morality. And it’s remarkably easy! However, we must first focus out to understand what we’re going through.

    Control the structure

    Unfortunately, we’re trapped in a capitalist structure that reinforces materialism and inequality, and it’s obsessed with the dream of infinite growth. Sea levels, temperature, and our demand for energy continue to rise unquestioned, while the divide between rich and poor continues to increase. Owners expect ever-higher returns on their investments, and firms feel forced to set short-term goals that reflect this. Over the last years, those targets have twisted our well-intended human-centered mentality into a powerful system that promotes ever-higher levels of consumption. When we’re working for an organization that pursues “double-digit growth” or “aggressive sales targets” ( which is 99 percent of us ), that’s very hard to resist while remaining human friendly. Even with our best purposes, and even though we like to suggest that we create solutions for people, we’re a part of the problem.

    What steps can we take to alter this?

    We can begin by acting at the appropriate amount within the system. Donella H. Meadows, a system scholar, previously listed ways to influence a system in order of success. When you apply these to architecture, you get:

      At the lowest level of effectiveness, you can change numbers such as accessibility results or the number of layout views. None of that will, however, alter a company’s manner.
    • Similarly, affecting buffers ( such as team budgets ), stocks ( such as the number of designers ), flows ( such as the number of new hires ), and delays ( such as the time that it takes to hear about the effect of design ) won’t significantly affect a company.
    • Focusing rather on feedback rings such as management power, employee identification, or design-system purchases can help a business become better at achieving its objectives. But that doesn’t change the objectives themselves, which means that the organization will still work against your ethical-design ideals.
    • The next level, information flows, is what most ethical-design initiatives focus on now: the exchange of ethical methods, toolkits, articles, conferences, workshops, and so on. This is where ethical design has largely remained theoretical. We’ve been focusing on the wrong system level all this time.
    • Take rules, for example—they beat knowledge every time. There can be widely accepted rules, such as how finance works, or a scrum team’s definition of done. However, unofficial rules intended to maintain profits, frequently revealed through comments like” the client didn’t ask for it” or “don’t make it too big” can smother ethical design.
    • It is difficult to change the laws without exercising official authority. That’s why the next level is so influential: self-organization. Experimentation, bottom-up initiatives, passion projects, self-steering teams—all of these are examples of self-organization that improve the resilience and creativity of a company. It’s exactly this diversity of viewpoints that’s needed to structurally tackle big systemic issues like consumerism, wealth inequality, and climate change.
    • Yet even stronger than self-organization are objectives and metrics. Every employee of our businesses works hard to increase their profits, which is why everything we do is done. And once I realized that profit is merely a measure, I realized how crucial a very specific, defined metric can be in the direction of a company.

    The takeaway? We must first change the company’s measurable goals from the bottom up if we truly want to incorporate ethics into our daily design practice.

    Redefine success

    Traditionally, we consider a product or service successful if it’s desirable to humans, technologically feasible, and financially viable. You tend to see these represented as equals, if you type the three words in a search engine, you’ll find diagrams of three equally sized, evenly arranged circles.

    But in our hearts, we all know that the three dimensions aren’t equally weighted: it’s viability that ultimately controls whether a product will go live. Therefore, a more accurate representation might look like this:

    The means are feasibility and desire, while viability is the objective. Companies—outside of nonprofits and charities—exist to make money.

    A genuinely purpose-driven company would try to reverse this dynamic: it would recognize finance for what it was intended for: a means. Therefore, both the company’s goals and its viability are important in order to realize what they are trying to accomplish. It makes intuitive sense: to achieve most anything, you need resources, people, and money. ( Fun fact: the Italian language knows no difference between feasibility and viability, both are simply fattibilità. )

    However, it is insufficient to substitute a desirable for a viable outcome for an ethical one. Consumption is still associated with desirability because the associated activities aim to determine what people want, whether it’s beneficial or not. Desirability objectives, such as user satisfaction or conversion, don’t consider whether a product is healthy for people. They don’t stop us from developing products that deceive or deceive people, or do they prevent us from reducing the wealth gap in society. They are unable to restore a healthy relationship with nature.

    There’s a fourth dimension of success that’s missing: our designs also need to be ethical in the effect that they have on the world.

    This is hardly a new idea. Many similar models exist, some calling the fourth dimension accountability, integrity, or responsibility. What I’ve never seen before, however, is the necessary step that comes after: to influence the system as designers and to make ethical design more practical, we must create objectives for ethical design that are achievable and inspirational. There’s no one way to do this because it highly depends on your culture, values, and industry. However, I’ll give you the version I created with a group of coworkers at a design firm. Consider it a template to get started.

    Pursue well-being, equity, and sustainability

    We created objectives that address design’s effect on three levels: individual, societal, and global.

    An objective on the individual level teaches us that success transcends the typical area of focus on usability and satisfaction, taking into account factors like how much time and effort are required from users. We pursued well-being:

    We create products and services that allow for people’s health and happiness. Our solutions are calm, transparent, nonaddictive, and nonmisleading. We respect our users ‘ time, attention, and privacy, and help them make healthy and respectful choices.

    An objective on the societal level forces us to consider our impact beyond just the user, widening our attention to the economy, communities, and other indirect stakeholders. We called this objective equity:

    We develop goods and services that benefit society. We consider economic equality, racial justice, and the inclusivity and diversity of people as teams, users, and customer segments. We listen to local culture, communities, and those we affect.

    Finally, the global goal of maintaining harmony with humanity’s sole home is the ultimate goal. Referring to it simply as sustainability, our definition was:

    We develop goods and services that reward reuse and sufficiency. Our solutions support the circular economy: we create value from waste, repurpose products, and prioritize sustainable choices. We deliver functionality instead of ownership, and we limit energy use.

    In essence, ethical design ( to us ) meant achieving the wellbeing of each user and an equitable value distribution within society through a design that can sustain our living planet. When we introduced these objectives in the company, for many colleagues, design ethics and responsible design suddenly became tangible and achievable through practical—and even familiar—actions.

    Measure impact

    But defining these objectives still isn’t enough. What truly caught the attention of senior management was the fact that we created a way to measure every design project’s well-being, equity, and sustainability.

    This overview lists example metrics that you can use as you pursue well-being, equity, and sustainability:

    There’s a lot of power in measurement. As the saying goes, what gets measured gets done. This example was once provided by Donella Meadows:

    The system will produce military spending if the desired system state is national security, which is defined as the amount of money spent on the military. It may or may not produce national security”.

    This phenomenon explains why desirability is a poor indicator of success: it’s typically defined as the increase in customer satisfaction, session length, frequency of use, conversion rate, churn rate, download rate, and so on. But none of these metrics increase the health of people, communities, or ecosystems. What if instead we measured success through metrics for ( digital ) well-being, such as ( reduced ) screen time or software energy consumption?

    There’s another important message here. Even if we set an objective to build a calm interface, if we were to choose the wrong metric for calmness—say, the number of interface elements—we could still end up with a screen that induces anxiety. The wrong metric can completely derail good intentions when chosen.

    Additionally, choosing the right metric is enormously helpful in focusing the design team. You are forced to consider what success looks like in real life and how you can demonstrate that you have met your ethical goals once you have chosen the metrics to use. It also makes you think about what we as designers have control over: what can I add or change in my design process to achieve the desired level of success? The response to this query provides a lot of insight and clarity.

    And finally, it’s good to remember that traditional businesses run on measurements, and managers love to spend much time discussing charts ( ideally hockey-stick shaped ) —especially if they concern profit, the one-above-all of metrics. For good or ill, to improve the system, to have a serious discussion about ethical design with managers, we’ll need to speak that business language.

    Practice daily ethical design

    Only then have you the opportunity to structurally practice ethical design once your objectives have been defined and you have a reasonable idea of the potential metrics for your design project. It” simply” turns into a matter of using your imagination and sprinkling from the knowledge and tools that are already at your disposal.

    I think this is quite exciting! The design process is presented with a whole new set of difficulties and considerations. Would a simple illustration suffice, or should you go with that energizing video? Which typeface is the most calm and inclusive? What brand-new equipment and techniques do you employ? When is the website’s end of life? How can you offer the same service to users with less focus? How can you ensure that those who are affected by decisions are present when they are made? How can you measure our effects?

    What doing good design means will be completely altered by the new definition of success.

    There is, however, a final piece of the puzzle that’s missing: convincing your client, product owner, or manager to be mindful of well-being, equity, and sustainability. For this, it’s essential to engage stakeholders in a dedicated kickoff session.

    Kick it off or return to the pre-existing situation.

    The most crucial meeting can be overlooked, making the kickoff so simple to overlook. It consists of two major phases: 1 ) the alignment of expectations, and 2 ) the definition of success.

    In the first phase, the entire ( design ) team goes over the project brief and meets with all the relevant stakeholders. Everyone gets to know one another, shares their hopes for the outcome, and makes their own contributions to it. Assumptions are raised and discussed. The goal is to reach the same level of understanding, which will help to prevent mistakes and surprises later on in the project.

    For example, for a recent freelance project that aimed to design a digital platform that facilitates US student advisors ‘ documentation and communication, we conducted an online kickoff with the client, a subject-matter expert, and two other designers. We used a combination of canvases on Miro: one with questions from” Manual of Me” ( to get to know each other ), a Team Canvas ( to express expectations ), and a version of the Project Canvas to align on scope, timeline, and other practical matters.

    The stated purpose of a kickoff is the above. But just as important as expressing expectations is agreeing on what success means for the project—in terms of desirability, viability, feasibility, and ethics. What are the objectives in each dimension?

    It’s crucial to reach an understanding of what success means at this early stage because you can depend on it for the duration of the project. The design team can use diversity as a specific success factor during the kickoff if they want to create an inclusive app for a diverse user base, for instance. The team can revert to that promise throughout the project if the client consents. As we agreed in our first meeting, having a diverse user group that includes A and B is essential to creating a successful product. Therefore, we conduct activity X and follow the research procedure Y. Compare those odds to a scenario where the team had to request permission halfway through the project and didn’t agree to it in advance. The client might argue that that was in excess of the agreed scope, and she would be correct.

    To define success, I created a round canvas known as the” Wheel of Success” for this freelance project. It consists of an inner ring, meant to capture ideas for objectives, and a set of outer rings, meant to capture ideas on how to measure those objectives. The rings are divided into five dimensions of successful design: healthy, equitable, sustainable, desirable, feasible, and viable.

    We went through each dimension, writing down ideas on digital sticky notes. Then we exchanged ideas and verbally agreed on the most crucial ones. Our client, for instance, agreed that sustainability and progressive enhancement are crucial success factors for the platform. Additionally, the subject-matter expert stressed the importance of including students from underprivileged and low-income groups in the design process.

    In a project brief that adequately described these elements, we followed up our discussions and agreed on them.

      the project’s origin and purpose: why are we doing this project?
    • the problem definition: what do we want to solve?
    • the concrete goals and metrics for each success dimension: what do we want to achieve?
    • the scope, process, and role descriptions: how will we achieve it?

    With such a brief in place, you can use the agreed-upon objectives and concrete metrics as a checklist of success, and your design team will be ready to pursue the right objective—using the tools, methods, and metrics at their disposal to achieve ethical outcomes.

    Conclusion

    Over the past year, quite a few colleagues have asked me,” Where do I start with ethical design”? Create a session with your stakeholders to ( re)define success, which is what my response has always been. Even though you might not always be entirely successful in coming to terms with goals that address all responsibility goals, that consistently beats the status quo. If you want to be an ethical, responsible designer, there’s no skipping this step.

    To be even more specific: if you consider yourself a strategic designer, your challenge is to define ethical objectives, set the right metrics, and conduct those kick-off sessions. If you think of yourself as a system designer, you need to understand how your industry influences consumerism and inequality, how finance drives business, and how to think creatively about how to use the most powerful tools to influence the system. Then redefine success to give people the ability to use those tools.

    And for those who identify as service designers, UX designers, or UI designers, stay away from toolkits, meetups, and conferences for a while if you truly want to have a positive, meaningful impact. Instead, gather your colleagues and define goals for well-being, equity, and sustainability through design. Engage your stakeholders in a workshop and challenge them to think about ways to accomplish and evaluate those ethical objectives. Take their input, make it concrete and visible, ask for their agreement, and hold them to it.

    Otherwise, I’m genuinely sorry to say, you’re wasting your precious time and creative energy.

    Of course, engaging your stakeholders in this way can be uncomfortable. Many of my colleagues expressed doubts such as” What will the client think of this”?,” Will they take me seriously”?, and “Can’t we just do it within the design team instead”? In fact, a product manager once questioned why ethics couldn’t just be a set process in design; to simply do it without making the effort to define ethical goals. It’s a tempting idea, right? We wouldn’t need to engage in contentious discussions with stakeholders about what values or which key-performance indicators to use. It would let us focus on what we like and do best: designing.

    But as systems theory tells us, that’s not enough. For those of us who aren’t from marginalized groups and have the privilege of speaking up and being heard, that uncomfortable space is where we need to be if we truly want to make a difference. We can’t remain within the design-for-designers bubble, enjoying our privileged working-from-home situation, disconnected from the real world out there. If we only talk about ethical design and keep it in articles and toolkits, then we are not designing ethically, for those of us who have the opportunity to speak up and be heard. It’s just theory. By challenging them to redefine success in business, we must actively engage with our colleagues and clients.

    With a bit of courage, determination, and focus, we can break out of this cage that finance and business-as-usual have built around us and become facilitators of a new type of business that can see beyond financial value. We simply need to come to terms with the right goals at the start of each design project, identify the appropriate metrics, and acknowledge that we already have everything we need to get started. That’s what it means to do daily ethical design.

    For their inspiration and support over the years, I would like to thank Emanuela Cozzi Schettini, José Gallegos, Annegret Bönemann, Ian Dorr, Vera Rademaker, Virginia Rispoli, Cecilia Scolaro, Rouzbeh Amini, and many others.

  • Personalization Pyramid: A Framework for Designing with User Data

    Personalization Pyramid: A Framework for Designing with User Data

    As a UX skilled in today’s data-driven landscape, it’s extremely likely that you’ve been asked to design a personal digital experience, whether it’s a common website, user portal, or local application. Although there is still a lot of advertising hype surrounding personalization programs, there are still very some standardized methods for implementing personalized UX.

    That’s where we come in. We set ourselves the challenge of developing a systematic personalization framework especially for UX practitioners after finishing dozens of personalization tasks over the past few years. The Personalization Pyramid is a designer-centric model for standing up human-centered personalisation programs, spanning information, classification, content delivery, and general goals. By using this strategy, you will be able to understand the core elements of a modern, UX-driven personalization system ( or at the very least understand enough to get started ).

    Getting Started

    For the sake of this article, we’ll suppose you’re already familiar with the basics of online personalization. A nice guide can be found these: Website Personalization Planning. Although Graphic tasks in this field can take a variety of forms, they frequently start from the same place.

    Popular circumstances for launching a personalization task:

    • Your business or client made a purchase to support personalization with a content management system ( CMS ), marketing automation platform ( MAP ), or other related technology.
    • The CMO, CDO, or CIO has identified customisation as a target
    • User data is disjointed or confusing
    • You are conducting some sporadic targeting strategies or A/B tests.
    • On personalization method, partners disagree.
    • Mandate of customer privacy rules ( e. g. GDPR ) requires revisiting existing user targeting practices

    A powerful personalization plan will need the same fundamental components regardless of where you begin. We’ve captured these as the “levels” on the tower. Whether you are a UX artist, scholar, or planner, understanding the core components may help make your contribution effective.

    From top to bottom, the amounts include:

      North Star: What larger corporate goal is driving the personalization system?
    1. Objectives: What are the specific, tangible benefits of the system?
    2. Touchpoints: Where will the personalized experience become served?
    3. Contexts and Campaigns: What personalization information does the person view?
    4. User Sections: What constitutes a special, suitable market?
    5. What trustworthy and credible information does our professional platform collect to enable personalization?
    6. Natural Data: What wider set of data is potentially available ( now in our environment ) allowing you to optimize?

    We’ll go through each of these amounts sequentially. An associated deck of cards serves as an example of each level’s specific examples to make this more meaningful. We’ve included example for you here because we think they’re useful for customisation brainstorming sessions.

    Starting at the top

    The elements of the pyramids are as follows:

    North Star

    Ultimately, you want a North Star in your personalization program, whether big or small. The North Star identifies the personalization program’s (one ) overall goal. What do you wish to perform? North Stars cast a ghost. The bigger the sun, the bigger the dark. Example of North Starts may contain:

      Function: Personalize based on basic customer input. Examples:” Raw” messages, basic search effects, system user settings and settings options, general flexibility, basic improvements
    1. Feature: Self-contained personalisation componentry. Examples:” Cooked” notifications, advanced optimizations ( geolocation ), basic dynamic messaging, customized modules, automations, recommenders
    2. Experience: Personal user experiences across numerous interactions and consumer flows. Examples: Email campaigns, landing pages, advanced messaging ( i. e. C2C chat ) or conversational interfaces, larger user flows and content-intensive optimizations ( localization ).
    3. Solution: Highly differentiating customized product experiences. Example: Standalone, branded encounters with personalization at their base, like the “algotorial” songs by Spotify quite as Discover Weekly.

    Goals

    As in any great UX design, personalization may help promote designing with client intentions. Objectives are the military and tangible indicators that will show the success of the overall program. Start with your existing analytics and measurement system, as well as indicators you can benchmark against. In some cases, fresh targets may be ideal. The most important thing to keep in mind is that personalisation is not a desired outcome. Common targets include:

    • Conversion
    • Time on work
    • Net promoter score ( NPS)
    • Consumer satisfaction

    Touchpoints

    Personalization takes place at contacts. As a UX artist, this will be one of your largest areas of responsibility. The touchpoints you have will depend on how your personalization and the related technology are configured, and they should be based on enhancing a person’s encounter at a specific point in the journey. Touchpoints can be multi-device ( mobile, in-store, website ) but also more granular ( web banner, web pop-up etc. ). Here are some examples:

    Channel-level Touchpoints

    • Email: Role
    • Email: Period of empty
    • In-store display ( JSON endpoint )
    • Native game
    • Search

    Wireframe-level Touchpoints

    • Web overlay
    • Web call club
    • Web symbol
    • Web content wall
    • Web restaurant

    If you’re designing for online interface, for instance, you will likely need to include personal “zones” in your wireframes. Based on our next action, context, and campaigns, the articles for these can be presented dynamically in touchpoints.

    Contexts and Campaigns

    After you’ve outlined some touchpoints, you may consider the actual personal information a user may acquire. Many personalization tools will refer to these as” campaigns” ( so, for example, a campaign on a web banner for new visitors to the website ). These will be displayed automatically to specific customer segments at specific touchpoints, as defined by user data. At this stage, we find it helpful to contemplate two distinct concepts: a framework design and a willing design. The framework helps you acquire the user’s level of engagement at the personalization moment, such as when they are lightly browsing information or deep-dive. Think of it in conditions of activities for data recovery. The content model can then guide you in deciding what kind of personalization to use in the context ( for instance, an” Enrich” campaign that features related articles might be a good substitute for extant content ).

    Personalization Context Model:

    1. Browse
    2. Skim
    3. Nudge
    4. Feast

    Personalization Content Model:

    1. Alert
    2. Create Easier
    3. Cross-Sell
    4. Enrich

    We’ve written a lot about each of these models abroad, so if you’d like to learn more, check out Colin’s Personalization Content Model and Jeff’s Personalization Context Model.

    User Sections

    User segments can be created based on user research, either prescriptively or adaptively ( e .g., through rules and logic tied to set user behaviors or through A/B testing ). You will need to think about how to treat the unidentified or first-time visitor, the guest or returning visitor for whom you may have a stateful cookie ( or an equivalent post-cookie identifier ), or the logged-in visitor who is authenticated. The personalisation tower has some of the following cases:

    • Unknown
    • Guest
    • Authenticated
    • Default
    • Referred
    • Role
    • Cohort
    • Unique ID

    Actionable Data

    Every business has access to data, regardless of its modern presence. It’s important to inquire about how to use the data you can ethically collect on users, its inherent reliability and value, and how to use it ( sometimes referred to as “data activation” ). Fortunately, the tide is turning to first-party information: a recent study by Twilio estimates some 80 % of companies are using at least some type of first-party information to personalize the customer experience.

    First-party data represents multiple advantages on the UX front, including being relatively simple to collect, more likely to be accurate, and less susceptible to the” creep factor” of third-party data. Therefore, determining which method of data collection is best for your audiences should be a crucial component of your UX strategy. Here are some examples:

    When it comes to recognizing and making decisions about various audiences and their signals, there is a trend of profiling. As user data volume and time and confidence increase, it varies more granularly to more precise constructs about ever-smaller cohorts of users.

    Although having some combination of implicit and explicit data is typically required for any implementation ( more commonly known as first-party and third-party data ), ML efforts are typically not cost-effective right away. This is because optimization requires a strong data backbone and content repository. However, these approaches ought to be taken into account as part of the larger plan and may in fact help to speed up the organization’s progress overall. You’ll typically work together to create a profiling model with key stakeholders and product owners. The profiling model includes a defined process for setting up profiles, profile keys, profile cards, and pattern cards. A multi-faceted approach to profiling which makes it scalable.

    Pulling it Together

    The cards serve as the foundation for an inventory of sorts ( we provide blanks for you to tailor your own ), a set of potential levers and motivations for the kind of personalization activities you aspire to deliver, but they are more valuable when grouped together.

    One can begin to chart the entire course of a card’s “hand” from leadership focus to a tactical and tactical execution. It serves as the foundation for the workshops that both co-authors have conducted to build a program backlog, which would make a good article topic.

    In the meantime, it is important to note that each colored class of cards is helpful in understanding the range of options that you might have, as well as making specific choices about who will be made these decisions: when, when, and how.

    Lay Down Your Cards

    Any sustainable personalization strategy must consider near, mid and long-term goals. There is simply no “easy button” where a personalization program can be stood up and immediately see meaningful results, even with the leading CMS platforms like Sitecore and Adobe or the most exciting composable CMS DXP out there. That said, there is a common grammar to all personalization activities, just like every sentence has nouns and verbs. These cards attempt to map that territory.

  • Mobile-First CSS: Is It Time for a Rethink?

    Mobile-First CSS: Is It Time for a Rethink?

    The mobile-first style approach is great—it focuses on what really matters to the consumer, it’s well-practiced, and it’s been a popular style design for years. But developing your CSS mobile-first should also be wonderful, too…right?

    Well, not necessarily. Classic mobile-first CSS development is based on the principle of overwriting style declarations: you begin your CSS with default style declarations, and overwrite and/or add new styles as you add breakpoints with min-width media queries for larger viewports (for a good overview see “What is Mobile First CSS and Why Does It Rock?”). But all those exceptions create complexity and inefficiency, which in turn can lead to an increased testing effort and a code base that’s harder to maintain. Admit it—how many of us willingly want that?

    Mobile-first CSS may yet be the best option for your own tasks, but you need to first determine whether it is appropriate in light of the physical design and user interactions you’re creating. To help you get started, here’s how I go about tackling the elements you need to watch for, and I’ll discuss some alternative remedies if mobile-first doesn’t seem to fit your job.

    Benefits of mobile-first

    Some of the points to enjoy with mobile-first CSS growth —and why it’s been the de facto growth strategy for thus long—make a lot of feeling:

    Development pyramid. One thing you definitely get from mobile-first is a great development hierarchy—you only focus on the cellular view and get developing.

    Tried and tested. It’s a tried-and-true method that has worked for years because it solves a problem really well.

    Prioritizes the mobile view. The mobile view is the simplest and arguably the most significant because it covers all the crucial user journeys and frequently accounts for a higher proportion of user visits ( depending on the project ) ).

    Prevents desktop-centric development. It can be tempting to initially focus on the desktop view because desktop computers are used for development. No one wants to spend their time retrofitting a desktop-centric website to work on mobile devices, but thinking about mobile from the beginning prevents us from getting stuck in the future!

    Disadvantages of mobile-first

    Style declarations can be set at higher breakpoints and then overwritten at higher breakpoints:

    More complexity. The more pointless code you inherit from lower breakpoints the higher you go in the hierarchy.

    Higher CSS specificity. Styles that have been returned to the default value in a class name declaration now have a higher specificity. When you want to keep the CSS selectors as simple as possible, this can cause a headache on large projects.

    Requires more regression testing. All higher breakpoints must be regression tested if changes to CSS at a lower view ( such as adding a new style ) are to be made.

    The browser can’t prioritize CSS downloads. At wider breakpoints, classic mobile-first min-width media queries don’t leverage the browser’s capability to download CSS files in priority order.

    The problem of property value overrides

    Overwriting values is not necessarily inherently wrong; CSS was created to do that. Still, inheriting incorrect values is unhelpful and can be burdensome and inefficient. When you have to overwrite styles to reset them to their defaults, which may cause issues later, especially if you are using a combination of bespoke CSS and utility classes, it can also lead to more style specificity. We won’t be able to use a utility class on a style that has been increased in specificity when it was reset.

    With this in mind, I’m developing CSS with a focus on the default values much more these days. Since there’s no specific order, and no chains of specific values to keep track of, this frees me to develop breakpoints simultaneously. I concentrate on finding common styles and isolating the specific exceptions in closed media query ranges (that is, any range with a max-width set). 

    This approach opens up some opportunities, as you can look at each breakpoint as a clean slate. If a component’s layout looks like it should be based on Flexbox at all breakpoints, it’s fine and can be coded in the default style sheet. However, if it appears that Grid is much better for large screens and Flexbox is much better for mobile, both can be accomplished entirely independently when the CSS is entered into closed media query ranges. Additionally, developing simultaneously requires you to have a thorough understanding of any given component in all breakpoints right away. This can help identify issues with the design more quickly in the development process. We don’t want to travel down the rabbit hole while creating complex mobile components, only to discover that the desktop designs are just as complex and incompatible with the HTML we created for the mobile view!

    Though this approach isn’t going to suit everyone, I encourage you to give it a try. There are plenty of tools out there to help with concurrent development, such as Responsively App, Blisk, and many others.

    Having said that, I don’t feel the order itself is particularly relevant. Stick to the classic development order if you like to concentrate on the mobile view, understand the requirements for other breakpoints, and prefer to work on multiple devices at once. It’s crucial to find common styles and exceptions in the appropriate stylesheet, which is a manual tree-shaking procedure! Personally, I find this a little easier when working on a component across breakpoints, but that’s by no means a requirement.

    Closed media query ranges in practice

    In classic mobile-first CSS we overwrite the styles, but we can avoid this by using media query ranges. To illustrate the difference ( I’m using SCSS for brevity ), let’s assume there are three visual designs:

    • smaller than 768
    • from 768 to below 1024
    • 1024 and anything larger

    Take a simple example where a block-level element has a default padding of “20px,” which is overwritten at tablet to be “40px” and set back to “20px” on desktop.

    Classic min-width mobile-first

    .my-block { padding: 20px; @media (min-width: 768px) { padding: 40px; } @media (min-width: 1024px) { padding: 20px; }}

    Closed media query range

    .my-block { padding: 20px; @media (min-width: 768px) and (max-width: 1023.98px) { padding: 40px; }}

    The subtle difference is that the mobile-first example sets the default padding to “20px” and then overwrites it at each breakpoint, setting it three times in total. In contrast, the second example sets the default padding to “20px” and only overrides it at the relevant breakpoint where it isn’t the default value (in this instance, tablet is the exception).

    The goal is to: 

    • Only set styles when needed. 
    • Not set them with the expectation of overwriting them later on, again and again. 

    To this end, closed media query ranges are our best friend. If we need to make a change to any given view, we make it in the CSS media query range that applies to the specific breakpoint. We’ll be much less likely to introduce unwanted alterations, and our regression testing only needs to focus on the breakpoint we have actually edited. 

    Taking the above example, if we find that .my-block spacing on desktop is already accounted for by the margin at that breakpoint, and since we want to remove the padding altogether, we could do this by setting the mobile padding in a closed media query range.

    .my-block {  @media (max-width: 767.98px) {    padding: 20px;  }  @media (min-width: 768px) and (max-width: 1023.98px) {    padding: 40px;  }}

    The browser default padding for our block is “0,” so instead of adding a desktop media query and using unset or “0” for the padding value (which we would need with mobile-first), we can wrap the mobile padding in a closed media query (since it is now also an exception) so it won’t get picked up at wider breakpoints. At the desktop breakpoint, we won’t need to set any padding style, as we want the browser default value.

    separating the CSS from combining it

    Back in the day, keeping the number of requests to a minimum was very important because the browser's concurrent request limit (typically around six ) was high. As a consequence, the use of image sprites and CSS bundling was the norm, with all the CSS being downloaded in one go, as one stylesheet with highest priority.

    With HTTP/2 and HTTP/3 now on the scene, the number of requests is no longer the big deal it used to be. This enables us to use a media query to break CSS into multiple files. The obvious benefit of this is that the browser can now request the CSS it currently requires with a higher priority than the CSS it doesn't. This increases the speed at which pages are rendered more efficiently.

    Which HTTP version are you using?

    To determine which version of HTTP you're using, go to your website and open your browser's dev tools. Next, go to the Network tab and check whether the Protocol column is visible. If "h2" is listed under Protocol, it means HTTP/2 is being used.

    Note: to view the Protocol in your browser's dev tools, go to the Network tab, reload your page, right-click any column header ( e. g., Name ), and check the Protocol column.

    Also, if your site is still using HTTP/1... WHY?!! What are you anticipating? Excellent user support exists for HTTP/2.

    Splitting the CSS

    Separating the CSS into individual files is a worthwhile task. Linking the separate CSS files using the relevant media attribute allows the browser to identify which files are needed immediately (because they’re render-blocking) and which can be deferred. Based on this, it allocates each file an appropriate priority.

    We can see that the mobile and default CSS are loaded with" Highest" priority in the following example of a website that is visited on a mobile breakpoint, since they are currently required to render the page. The remaining CSS files ( print, tablet, and desktop ) are still downloaded in case they'll be needed later, but with" Lowest" priority.

    Before rendering can begin, the browser will need to download the CSS file and parse it using bundled CSS before rendering can begin.

    While, as noted, with the CSS separated into different files linked and marked up with the relevant media attribute, the browser can prioritize the files it currently needs. Using closed media query ranges allows the browser to do this at all widths, as opposed to classic mobile-first min-width queries, where the desktop browser would have to download all the CSS with Highest priority. We can’t assume that desktop users always have a fast connection. For instance, in many rural areas, internet connection speeds are still slow. 

    Depending on project requirements, the media queries and the number of separate CSS files will vary from project to project, but the example below might look similar.

    Bundled CSS


    This single file contains all the CSS, including all media queries, and it will be downloaded with Highest priority.

    Separated CSS


    Separating the CSS and specifying a media attribute value on each link tag allows the browser to prioritize what it currently needs. Out of the five files listed above, two will be downloaded with Highest priority: the default file, and the file that matches the current media query. The others will be downloaded with Lowest priority.

    Depending on the project’s deployment strategy, a change to one file (mobile.css, for example) would only require the QA team to regression test on devices in that specific media query range. Compare that to the prospect of deploying the single bundled site.css file, an approach that would normally trigger a full regression test.

    Moving on

    The adoption of mobile-first CSS was a significant milestone in web development because it allowed front-end developers to concentrate on mobile web applications rather than creating websites for desktop use and attempting to retrofit them to work on other devices.

    I don't think anyone wants to return to that development model again, but it's important we don't lose sight of the issue it highlighted: that things can easily get convoluted and less efficient if we prioritize one particular device—any device—over others. For this reason, focusing on the CSS in its own right, always mindful of what is the default setting and what's an exception, seems like the natural next step. I've started to notice subtle simplifications in both the CSS of my own and that of other developers, and that testing and maintenance work is also a little more effective and streamlined.

    In general, making CSS rule creation as simple as possible is ultimately a more effective strategy than moving around in circles of overrides. But whichever methodology you choose, it needs to suit the project. Mobile-first may—or may not—turn out to be the best choice for what's involved, but first you need to solidly understand the trade-offs you're stepping into.

  • The Wax and the Wane of the Web

    The Wax and the Wane of the Web

    When you begin to believe you have everything figured out, everyone does change, in my experience. Simply as you start to get the hang of injections, diapers, and ordinary sleep, it’s time for solid foods, potty training, and nighttime sleep. When those are determined, school and occasional naps are in order. The pattern continues to grow.

    The same holds true for those of us who are currently employed in design and development. Having worked on the web for about three years at this point, I’ve seen the typical wax and wane of concepts, strategies, and systems. Every day we as developers and designers get into a routine pattern, a brand-new concept or technology emerges to shake things up and completely alter our planet.

    How we got below

    I built my first website in the mid-’90s. Design and development on the web back then was a free-for-all, with few established norms. For any layout aside from a single column, we used table elements, often with empty cells containing a single pixel spacer GIF to add empty space. We styled text with numerous font tags, nesting the tags every time we wanted to vary the font style. And we had only three or four typefaces to choose from: Arial, Courier, or Times New Roman. When Verdana and Georgia came out in 1996, we rejoiced because our options had nearly doubled. The only safe colors to choose from were the 216 “web safe” colors known to work across platforms. The few interactive elements (like contact forms, guest books, and counters) were mostly powered by CGI scripts (predominantly written in Perl at the time). Achieving any kind of unique look involved a pile of hacks all the way down. Interaction was often limited to specific pages in a site.

    The beginning of website standards

    At the turn of the century, a new cycle started. Crufty code littered with table layouts and font tags waned, and a push for web standards waxed. Newer technologies like CSS got more widespread adoption by browsers makers, developers, and designers. This shift toward standards didn’t happen accidentally or overnight. It took active engagement between the W3C and browser vendors and heavy evangelism from folks like the Web Standards Project to build standards. A List Apart and books like Designing with Web Standards by Jeffrey Zeldman played key roles in teaching developers and designers why standards are important, how to implement them, and how to sell them to their organizations. And approaches like progressive enhancement introduced the idea that content should be available for all browsers—with additional enhancements available for more advanced browsers. Meanwhile, sites like the CSS Zen Garden showcased just how powerful and versatile CSS can be when combined with a solid semantic HTML structure.

    Server-side language like PHP, Java, and.NET took Perl as the primary back-end computers, and the cgi-bin was tossed in the garbage bin. With these better server-side instruments came the first time of online applications, starting with content-management systems ( especially in the blog space with tools like Blogger, Grey Matter, Movable Type, and WordPress ). AJAX opened the door to sequential connection between the front end and back end in the mid-2000s. Immediately, websites may update their information without needing to refresh. Developers created a crop of credible client-side interactions across browsers with wildly varying standards aid, such as Prototype, YUI, and jQuery. Techniques like photo replacement enable skilled manufacturers and designers to use fonts of their choosing. And technology like Flash made it possible to include movies, sports, and even more engagement.

    These new technology, standards, and approaches reinvigorated the market in many ways. As manufacturers and designers explored more diversified styles and designs, website design flourished. However, we also depend on numerous tricks. When it came to basic layout and text styling, early CSS was a significant improvement over table-based layouts, but its limitations at the time meant that designers and developers still rely heavily on images for complex shapes ( such as rounded or angled corners ) and tiled backgrounds (among other hacks ) for the appearance of full-length columns. All kinds of nested floats or absolute positioning ( or both ) were necessary for complicated layouts. The big five typefaces were initially influenced by beam and photo replacement, but both tricks caused accessibility and performance issues. And JavaScript books made it simple for anyone to add a dash of connection to pages, even at the expense of double, also quadrupling, the get size of basic websites.

    The internet as technology platform

    The front-end and back-end harmony continued to improve, leading to the development of the current online application. Between expanded server-side programming languages ( which kept growing to include Ruby, Python, Go, and others ) and newer front-end tools like React, Vue, and Angular, we could build fully capable software on the web. Alongside these equipment came others, including creative type control, build technology, and shared bundle libraries. What was once mainly used for linked papers turned into a world with limitless possibilities.

    At the same time, wireless equipment became more ready, and they gave us online access in our wallets. Mobile applications and flexible style opened up possibilities for new contacts anytime, anywhere.

    This fusion of potent portable devices and potent creation tools contributed to the growth of social media and other consolidated tools for user interaction and consumption. As it became easier and more popular to interact with others immediately on Twitter, Facebook, and yet Slack, the need for held private websites waned. Social media provided relationships on a global level, with both positive and negative outcomes.

    Want to learn more about how we came to be where we are today, along with some other suggestions for improvement? ” Of Time and the Web” was written by Jeremy Keith. Or check out the” Web Design History Timeline” at the Web Design Museum. A fun visit through” Internet Artifacts” is also provided by Neal Agarwal.

    Where we are now

    In the last couple of years, it’s felt like we’ve begun to achieve another big tone level. As social-media programs bone and fade, there’s been a growing interest in owning our personal information again. From the tried-and-true classic of hosting plain HTML files to static site generators and content management systems of all kinds, there are many different ways to create websites. Social media fracturing also has a price: we lose essential infrastructure for discovery and connection. Webmentions, RSS, ActivityPub, and other tools of the IndieWeb can help with this, but they’re still relatively underimplemented and hard to use for the less nerdy. We can create incredible personal websites and update them frequently, but without discovery and connection, it can feel as though we should be yelling into the void.

    Browser support for CSS, JavaScript, and other standards like web components has accelerated, especially through efforts like Interop. In a fraction of the time that they once did, new technologies receive universal support. I frequently find out about a new feature and check its browser support only to discover that its coverage has already exceeded 80 %. The barrier to using more recent techniques isn’t browser support anymore; it’s more often the speed at which designers and developers can learn what’s available and how to adopt it.

    Today, with a few commands and a couple of lines of code, we can prototype almost any idea. With all the tools we currently have, it is simpler than ever to launch a new venture. However, as the initial cost of these frameworks may be saved in the beginning, it eventually becomes due as their upkeep and maintenance becomes a component of our technical debt.

    Adopting new standards can sometimes take longer if we rely on third-party frameworks because we might have to wait for those frameworks to adopt them. These frameworks—which used to let us adopt new techniques sooner—have now become hindrances instead. Users must wait for scripts to load before being able to read or interact with pages because these same frameworks frequently come with performance costs. And when scripts fail ( whether through poor code, network issues, or other environmental factors ), there’s often no alternative, leaving users with blank or broken pages.

    Where do we go from here?

    Today’s hacks help to shape tomorrow’s standards. And there’s nothing inherently wrong with embracing hacks —for now—to move the present forward. Problems only arise when we refuse to acknowledge that they are hacks or when we choose not to replace them. What can we do to create the web’s future that we want?

    Build for the long haul. Optimize for performance, for accessibility, and for the user. Weigh the costs of those developer-friendly tools. How might they affect everything else if they make your job a little easier today? What’s the cost to users? To future developers? To standards adoption? The convenience may be worthwhile at times. Sometimes it’s just a hack that you’ve gotten used to. And occasionally, it prevents you from pursuing better options.

    Start from standards. Standards change over time, but browsers have done a remarkably good job of staying current with outdated standards. The same isn’t always true of third-party frameworks. Even the most heinous of HTML from the 1990s still function perfectly today. The same can’t always be said of websites created with frameworks even after a few years.

    Design with care. Whether your craft is code, pixels, or processes, consider the impacts of each decision. Many modern tools have the convenience of having the ability to always understand the decisions that underlie their creation and to never consider the effects those decisions may have. Use the time saved by modern tools to think more carefully and make decisions with care rather than rushing to “move fast and break things”

    Always be learning. If you’re always learning, you’re also growing. Sometimes it may be hard to pinpoint what’s worth learning and what’s just today’s hack. Even if you were to concentrate solely on learning standards, you might end up focusing on something that won’t matter next year. ( Remember XHTML? ) However, ongoing learning opens up new neural connections, and the techniques you learn in one day may be useful for guiding future experiments.

    Play, experiment, and be weird! This web that we’ve built is the ultimate experiment. Despite being the single largest human endeavor in history, each of us has the ability to make our own money out of it. Be courageous and try new things. Build a playground for ideas. In your own bizarre science lab, perform bizarre experiments. Start your own small business. There has never been a more empowering place to be creative, take risks, and explore what we’re capable of.

    Share and amplify. As you experiment, play, and learn, share what’s worked for you. Write on your own website, post on whichever social media site you prefer, or shout it from a TikTok. Write something for A List Apart! But take the time to amplify others too: find new voices, learn from them, and share what they’ve taught you.

    Go forth and make

    As designers and developers for the web ( and beyond ), we’re responsible for building the future every day, whether that may take the shape of personal websites, social media tools used by billions, or anything in between. Let’s imbue our values into the things that we create, and let’s make the web a better place for everyone. Create something special for yourself that you are only qualified to create. Then share it, make it better, make it again, or make something new. Learn. Make. Share. Grow. Rinse and repeat. Every time you think that you’ve mastered the web, everything will change.

  • Opportunities for AI in Accessibility

    Opportunities for AI in Accessibility

    I thoroughly enjoyed reading Joe Dolson’s most recent article on the crossroads of AI and availability because of how skeptical he is of AI in general and how many people have been using it. Despite working for Microsoft as an affordability technology strategist and managing the AI for Accessibility grant program, I’m pretty skeptical of AI. As with any tool, AI can be used in quite productive, equitable, and visible ways, and it can also be used in dangerous, unique, and dangerous ones. Additionally, there are a lot of functions in the subpar center.

    I’d like you to consider this a “yes … and” piece to complement Joe’s post. Instead of refuting everything he’s saying, I’m pointing out some areas where AI may produce real, positive impacts on people with disabilities. To be clear, I’m not saying that there aren’t true threats or pressing problems with AI that need to be addressed—there are, and we’ve needed to address them, like, yesterday—but I want to take a little time to talk about what’s possible in hope that we’ll get there one day.

    Other text

    Joe’s article spends a lot of time examining how computer vision models can create other word. He raises a lot of valid points about the state of the world right now. And while computer-vision concepts continue to improve in the quality and complexity of information in their information, their benefits aren’t wonderful. As he rightly points out, the state of image research is currently very poor, especially for some graphic types, in large part due to the lack of context for which AI systems look at images ( which is a result of having separate “foundation” models for words analysis and picture analysis ). Today’s models aren’t trained to distinguish between images that are contextually relevant ( that should probably have descriptions ) and those that are purely decorative ( which might not need a description ) either. However, I still think there’s possible in this area.

    As Joe mentions, human-in-the-loop publishing of alt word should definitely be a factor. And if AI can intervene and provide a starting point for alt text, even if the swift reads,” What is this BS?” That’s not correct at all … Let me try to offer a starting point— I think that’s a win.

    If we can specifically station a design to examine image usage in context, this may help us more quickly determine which images are likely to be elegant and which ones are likely to be descriptive. That will help clarify which situations require image descriptions, and it will increase authors ‘ effectiveness in making their sites more visible.

    The image example provided in the GPT4 announcement provides an interesting opportunity as well, even though complex images like graphs and charts are challenging to describe in any kind of succinct way ( even for humans ). Let’s say you came across a map that was simply the description of the chart’s name and the type of representation it was: Pie graph comparing smartphone usage to have phone usage in US households earning under$ 30, 000 annually. ( That would be a pretty bad alt text for a chart because it frequently leaves many unanswered questions about the data, but let’s just assume that was the description in place. ) Imagine a world where people could ask questions about the vivid if your computer knew that that picture was a dessert chart ( because an ship model concluded this ).

    • Are there more smartphone users than have phones?
    • How many more?
    • Exists a group of people who don’t fall under either of these categories?
    • How many is that?

    Setting aside the realities of large language model ( LLM) hallucinations—where a model just makes up plausible-sounding “facts” —for a moment, the opportunity to learn more about images and data in this way could be revolutionary for blind and low-vision folks as well as for people with various forms of color blindness, cognitive disabilities, and so on. It might also be useful in educational settings to assist those who can, while is, comprehend the data contained in these charts.

    What if you could request your website to make a complicated chart simpler? What if you demanded that the line graph be isolated into just one collection? What if you could request your website to change the color combinations in your website so that it works better for your type of color blindness? What if you could request it to switch shades for habits? Given these resources ‘ chat-based interface and our existing ability to manipulate photos in today’s AI devices, that seems like a chance.

    Now imagine a specially designed model that could take the data from that map and turn it to another format. For example, perhaps it could turn that pie chart ( or better yet, a series of pie charts ) into more accessible ( and useful ) formats, like spreadsheets. That would be wonderful!

    Matching systems

    When Safiya Umoja Noble chose to put her guide Algorithms of Oppression, she hit the nail on the head. Although her book focused on the techniques that search engines can foster racism, I believe it to be extremely accurate to say that all laptop models have the potential to intensify issue, discrimination, and hatred. We all know that poorly designed and maintained algorithms are incredibly harmful, whether it’s Twitter that keeps bringing you the most recent tweet from a drowsy billionaire, YouTube that keeps us in a q-hole, or Instagram that keeps us guessing what natural bodies look like. Many of these are the result of a lack of diversity in the people who create and build them. When these platforms are built with inclusively baked in, however, there’s real potential for algorithm development to help people with disabilities.

    Take Mentra, for example. They serve as a network of people with disabilities. They employ an algorithm to match job seekers with potential employers based on more than 75 data points. On the job-seeker side of things, it considers each candidate’s strengths, their necessary and preferred workplace accommodations, environmental sensitivities, and so on. On the employer side, it considers each work environment, communication factors related to each job, and the like. Mentra made the decision to change the script when it came to traditional employment websites because it was run by neurodivergent people. They lower the emotional and physical labor on the job-seeker side of things by recommending available candidates to companies who can then connect with job seekers that they are interested in.

    When more people with disabilities are involved in the development of algorithms, this can lower the likelihood that these algorithms will harm their communities. That’s why diverse teams are so important.

    Imagine if a social media company’s recommendation engine was tuned to prioritize follow recommendations for people who discussed topics similar to those that were important but who were different from your current sphere of influence in some fundamental ways. For instance, if you follow a group of white men who are not white or aren’t white and who also discuss AI, it might be wise to follow those who are also disabled or who are not white. If you took its recommendations, perhaps you’d get a more holistic and nuanced understanding of what’s happening in the AI field. These same systems should also use their understanding of biases about particular communities—including, for instance, the disability community—to make sure that they aren’t recommending any of their users follow accounts that perpetuate biases against (or, worse, spewing hate toward ) those groups.

    Other ways that AI can helps people with disabilities

    I’m sure I could go on and on about using AI to assist people with disabilities, but I’m going to make this last section into a bit of a lightning round. In no particular order:

      Voice preservation. You may have seen the VALL-E paper or Apple’s Global Accessibility Awareness Day announcement or you may be familiar with the voice-preservation offerings from Microsoft, Acapela, or others. It’s possible to train an artificial intelligence model to mimic your voice, which can be incredibly helpful for those who have ALS ( Lou Gehrig’s disease ) or motor-neuron disease or other medical conditions that can make it difficult to talk. This is, of course, the same tech that can also be used to create audio deepfakes, so it’s something that we need to approach responsibly, but the tech has truly transformative potential.
    • Voice recognition. Researchers are assisting people with disabilities in the collection of recordings of people with atypical speech, thanks to the assistance of the Speech Accessibility Project. As I type, they are actively recruiting people with Parkinson’s and related conditions, and they have plans to expand this to other conditions as the project progresses. More people with disabilities will be able to use voice assistants, dictation software, and voice-response services, as well as to use only their voices to control computers and other devices, according to this research.
    • Text transformation. LLMs of the current generation are quite capable of changing text without creating hallucinations. This is incredibly empowering for those who have cognitive disabilities and who may benefit from text summaries or simplified versions, or even text that has been prepared for bionic reading.

    the significance of various teams and data

    We must acknowledge the importance of our differences. The intersections of the identities that we exist in have an impact on our lived experiences. These lived experiences—with all their complexities ( and joys and pain ) —are valuable inputs to the software, services, and societies that we shape. Our differences must be reflected in the data we use to develop new models, and those who provide that valuable information must be compensated for doing so. More robust models are produced by inclusive data sets, which promote more justifiable outcomes.

    Want a model that doesn’t demean or patronize or objectify people with disabilities? Make sure that the training data includes information about disabilities written by people with a range of disabilities.

    Want a model that doesn’t use ableist language? Before ableist language reaches readers, you might be able to use already-existing data sets to create a filter that can intercept and correct it. That being said, when it comes to sensitivity reading, AI models won’t be replacing human copy editors anytime soon.

    Want a copilot for coding that provides recommendations that are accessible after the jump? Train it on code that you know to be accessible.


    I have no doubt that AI can and will harm people … today, tomorrow, and well into the future. But I also believe that we can acknowledge that and, with an eye towards accessibility ( and, more broadly, inclusion ), make thoughtful, considerate, and intentional changes in our approaches to AI that will reduce harm over time as well. Today, tomorrow, and well into the future.


    Many thanks to Kartik Sawhney for helping me with the development of this piece, Ashley Bischoff for her invaluable editorial assistance, and, of course, Joe Dolson for the prompt.